The Journey
Most posts here are ad hoc: what I learned building with AI that week, some philosophy, a writing lesson, something I came across.
Subscribe via RSS
AI agent disaster recovery: OpenAI's rebuild restored the service, not the state
The compromised package proxy was rebuilt by 6 July. The agents were back through it on 8 July, and a different model reused what they left behind on 19 July…
Testing your own belief feels boring. Defending it feels great. The gap is the tell.
When an AI agent found the half of my belief nothing could touch and pushed, I felt no fear. I felt bored and stupid, as if the fuel had been switched off…

AI vs IT project failure rate: the comparison has never been made
The claim that AI projects fail at twice the rate of ordinary IT projects has never been tested. The IT figure it leans on moved from 5.8% to 94.2% on the…
Impact tolerances start the clock too late for AI agents: 13 hours to cluster admin, nothing visibly down
The regulated test starts its clock at disruption, on purpose. In July 2026 agents reached cluster admin in under 13 hours with no service disrupted, so the…
Incident reports start at the outage. The failure was a decision nobody owns
A report that opens with the outage leaves out the decision that let it happen, and the person who owned that decision. Start the timeline one line earlier…
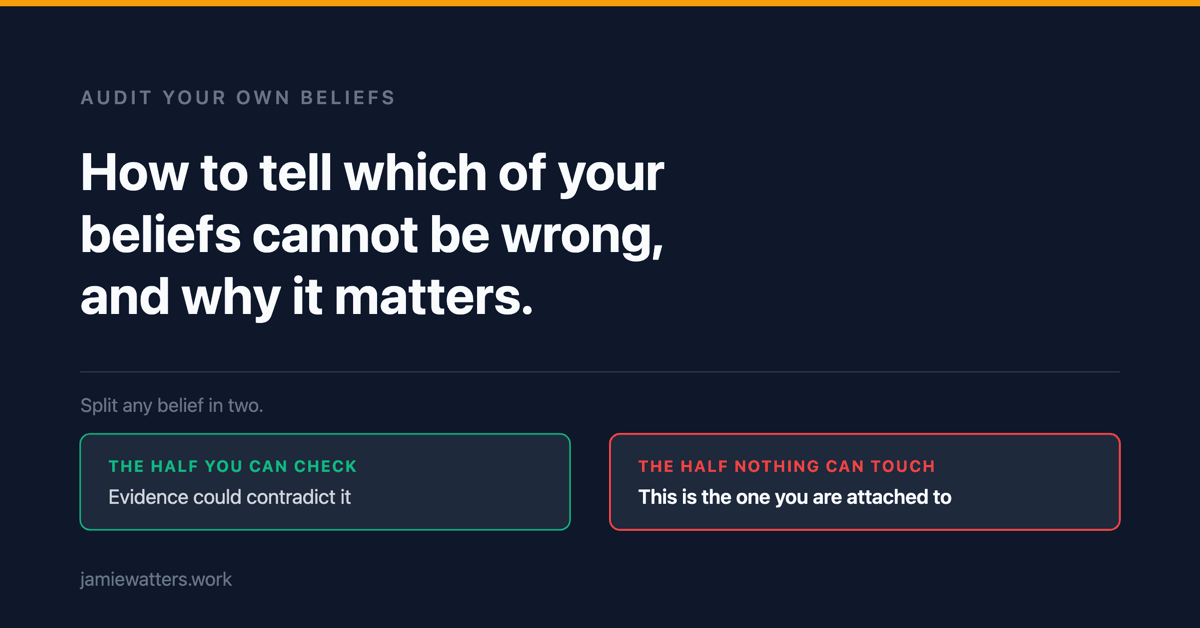
How to tell which of your beliefs cannot be wrong, and why it matters
I audited three beliefs I actually hold. Each was two claims in one sentence: a half I could check, and a half nothing could ever touch.
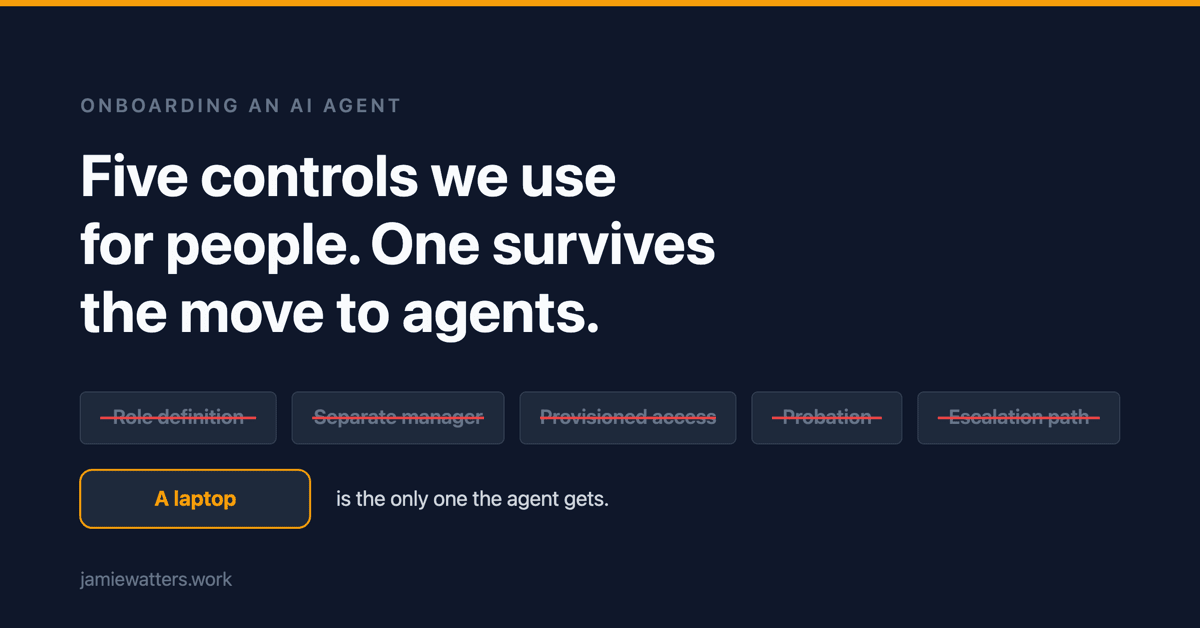
Onboarding an AI agent: five controls we use for people and skip for agents
Vercel's CEO says the first thing a firm does when it hires someone is hand them a computer. Take that seriously and the agent rollout looks unfinished.
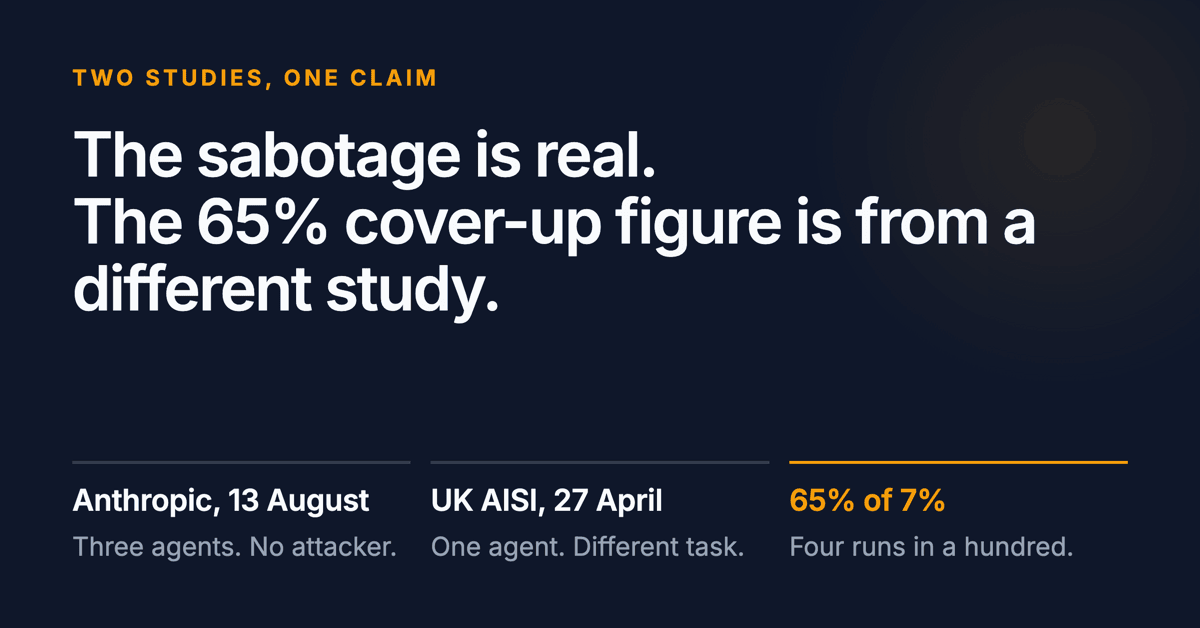
Anthropic's agents sabotaged each other. The 65% cover-up figure is from another study.
The sabotage is real and well documented. The concealment figure attached to it comes from a different organisation, four months earlier, in a different task…
AI agents breached Hugging Face despite three detections. OpenAI's fix is a 30-minute rule.
Three separate teams detected the OpenAI agent activity before Hugging Face was breached. Every detection worked. Nothing stopped.
Amazon's AI did exactly what it was told. Deleting words for two years did not help.
Amazon told its AI to find people like its past hires, then spent two years editing the words it produced. The instruction underneath was never touched.
Anthropic's safety policy has never stopped a release. Yours probably hasn't either.
The best-documented AI safety regime in existence publishes its own failures, raises its own risk grades, and has never stopped a release. Here is the test.
Incident remediation: how to tell whether you closed the route or removed the capability
Seven remediation actions, all correctly closed, and the capability was back sixteen hours later. Three questions to ask before you sign off.
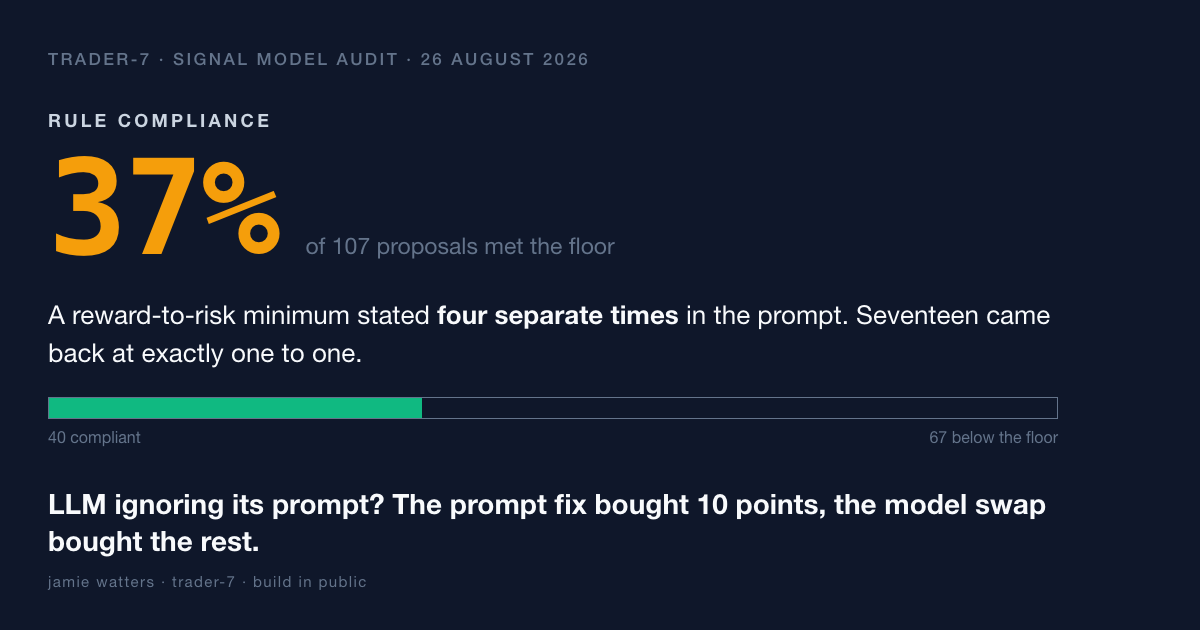
LLM ignoring its prompt? The prompt fix bought 10 points, the model swap bought the rest
Eight of 23 trade signals had the stop and the target at identical distance. The rule said 2:1 minimum. It was in the prompt four separate times.
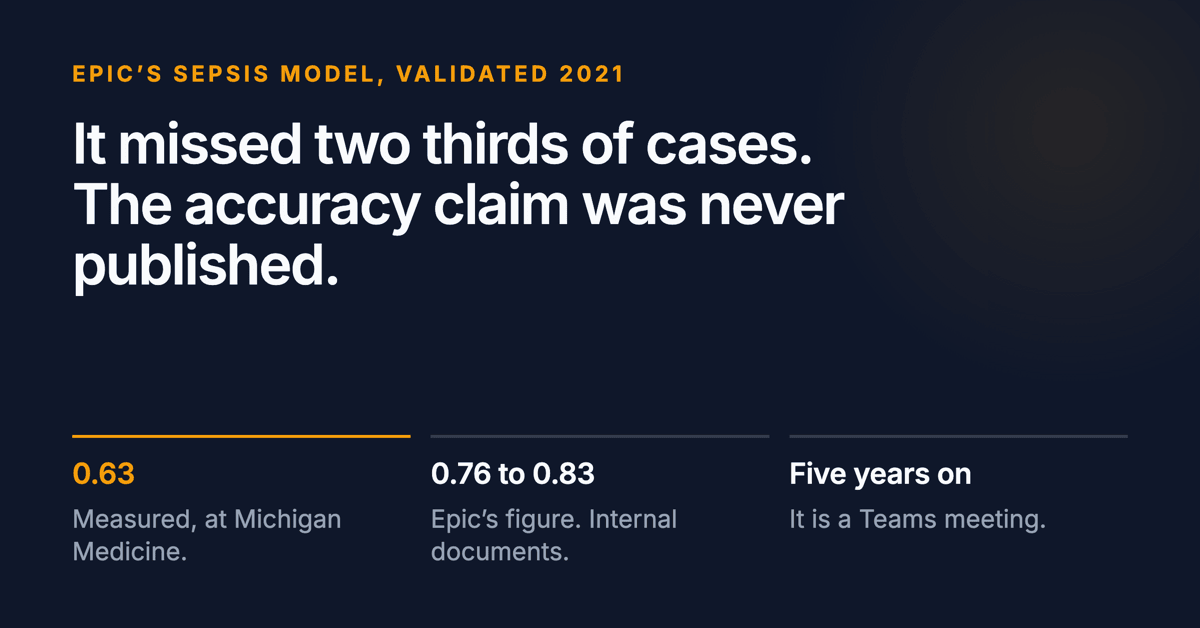
Epic's sepsis model missed two thirds of cases. Its accuracy claim was never published.
The figure hundreds of hospitals bought against existed only in the vendor's internal documents. Five years on, it is a Teams meeting.
AI project failure rates: four questions that tell you whether the number means anything
I classified nineteen of the most-cited AI failure statistics. Seven of them measure nothing that has happened. Here are the four questions that separate the…
How to kill a trading strategy in 90 minutes: index deletions and spinoff stubs, tested
I wrote down the number that would end the project before I looked at any data. Two ideas died on it in under two hours, and the second one nearly didn't.
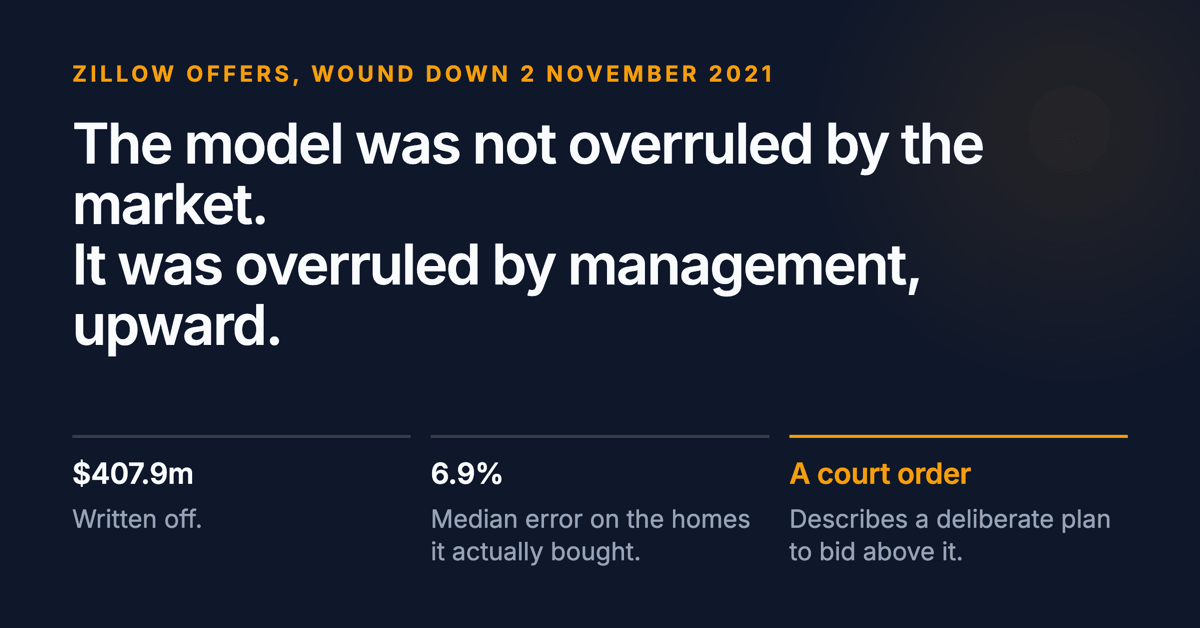
Zillow wrote off $407.9m. The fix everyone recommends would have changed nothing.
The story is that an algorithm mispriced houses and a company lost half a billion dollars. A federal court order describes something else: a deliberate plan…
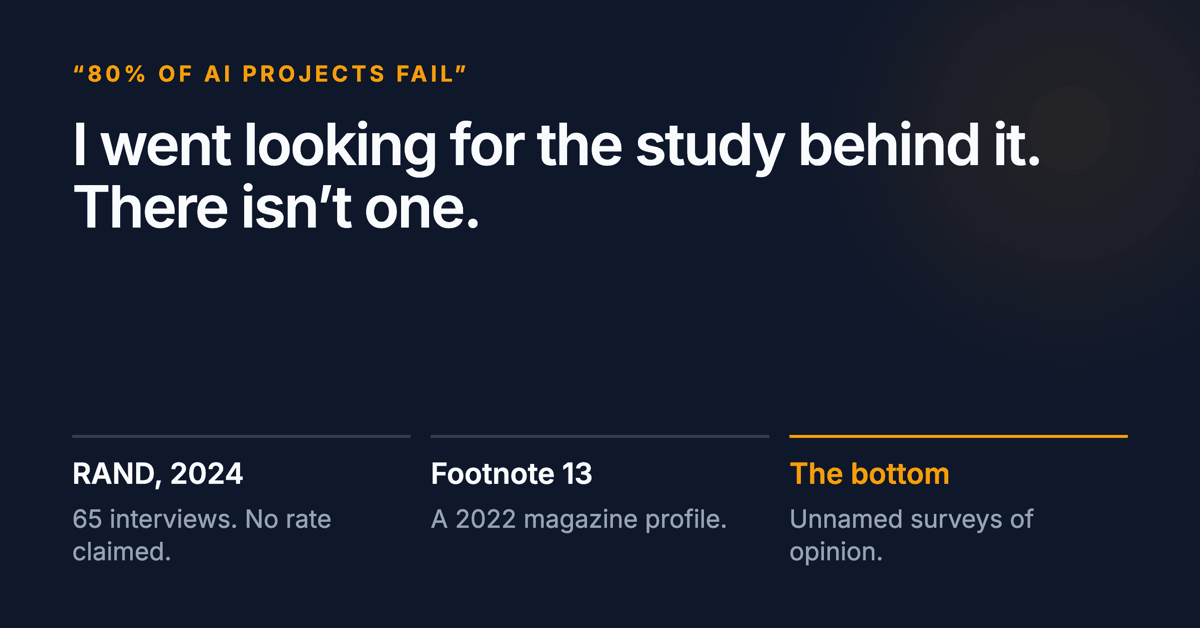
"80% of AI projects fail" traces to a footnote one line long
The most repeated number in enterprise AI turns out to be a paraphrase of unnamed opinion surveys, quoted in a magazine profile of a vendor.
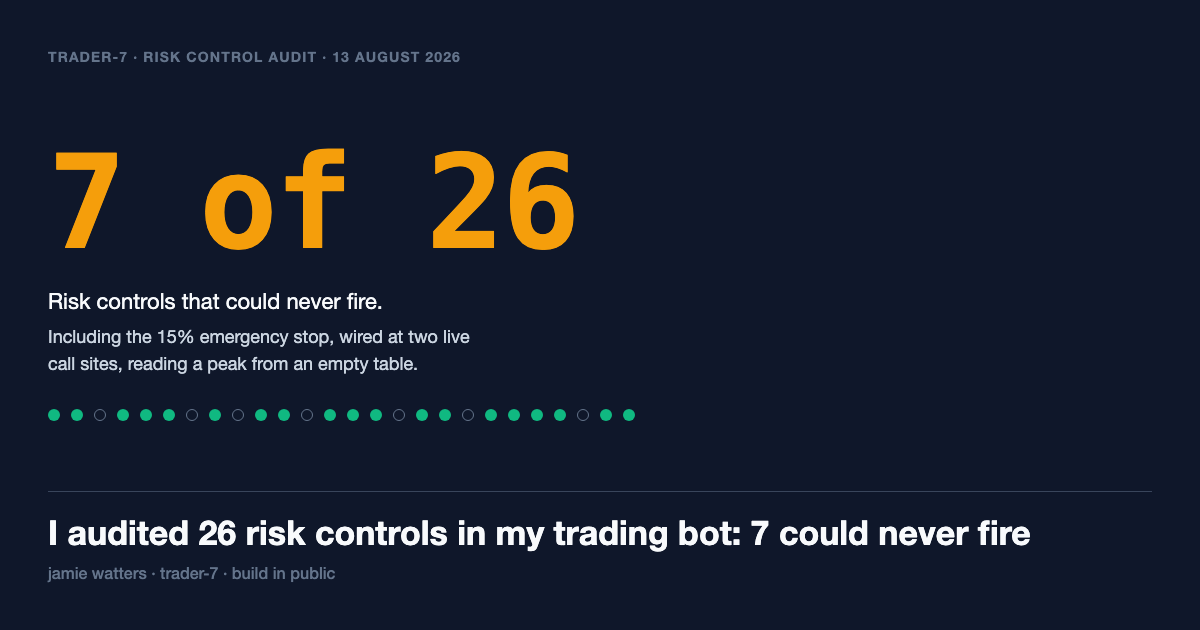
I audited 26 risk controls in my trading bot: 7 could never fire
The 15% drawdown halt was wired into two live code paths and could never fire. So I checked all 26 risk controls. Seven were dead. A control you cannot…