Building
Shipping products solo: the craft, the stack, the decisions.
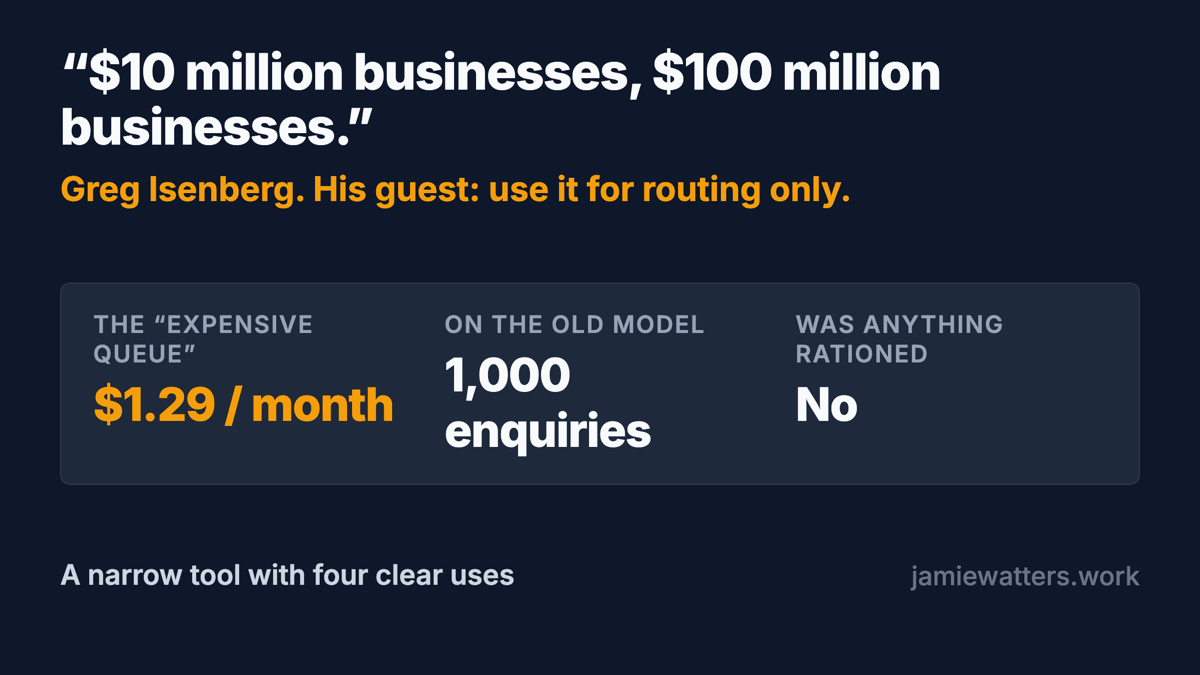
Jev is a narrow tool with four clear uses. Greg Isenberg's $10m framing is not one of them.
Greg Isenberg's episode on Jev promised $10m businesses. His own guest says use it for routing and keep it away from your money. Here is each claim against the data, and the four conditions under which the tool earns its place.
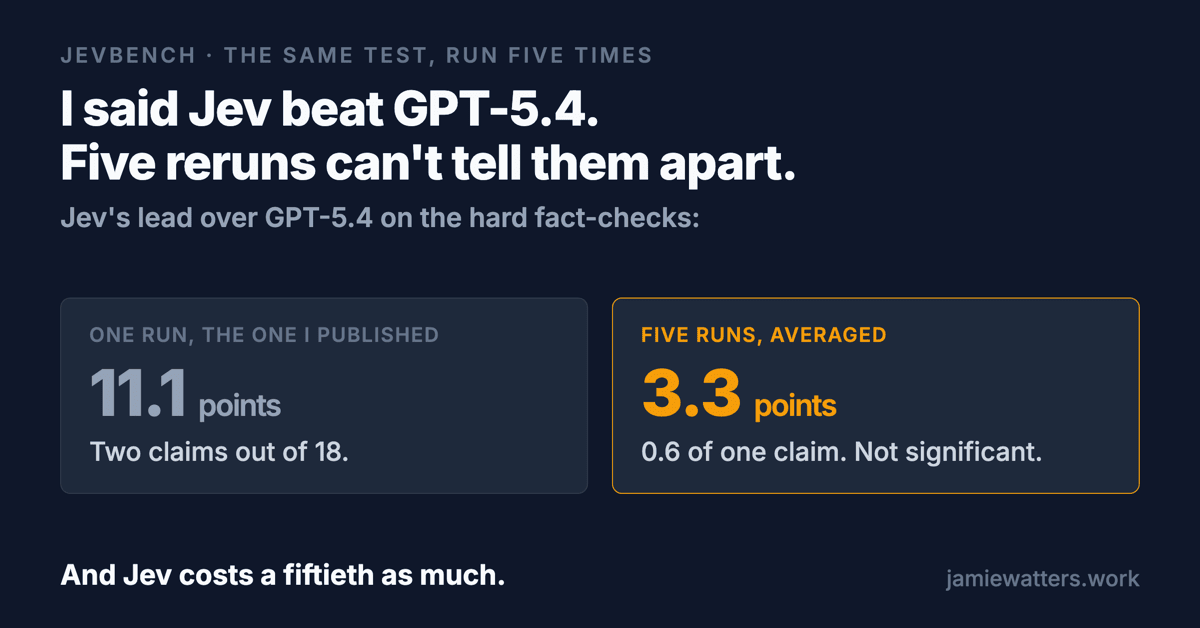
I said Jev beat GPT-5.4. Five reruns can't tell them apart, at a fiftieth of the cost.
I published that Jev, TypeSafe's new model, beat GPT-5.4 by 11.1 points on hard fact-checks. Rerun five times, the two can't be told apart, Jev costs a fiftieth as much, and it lets more wrong claims through. Plus the five-run check.
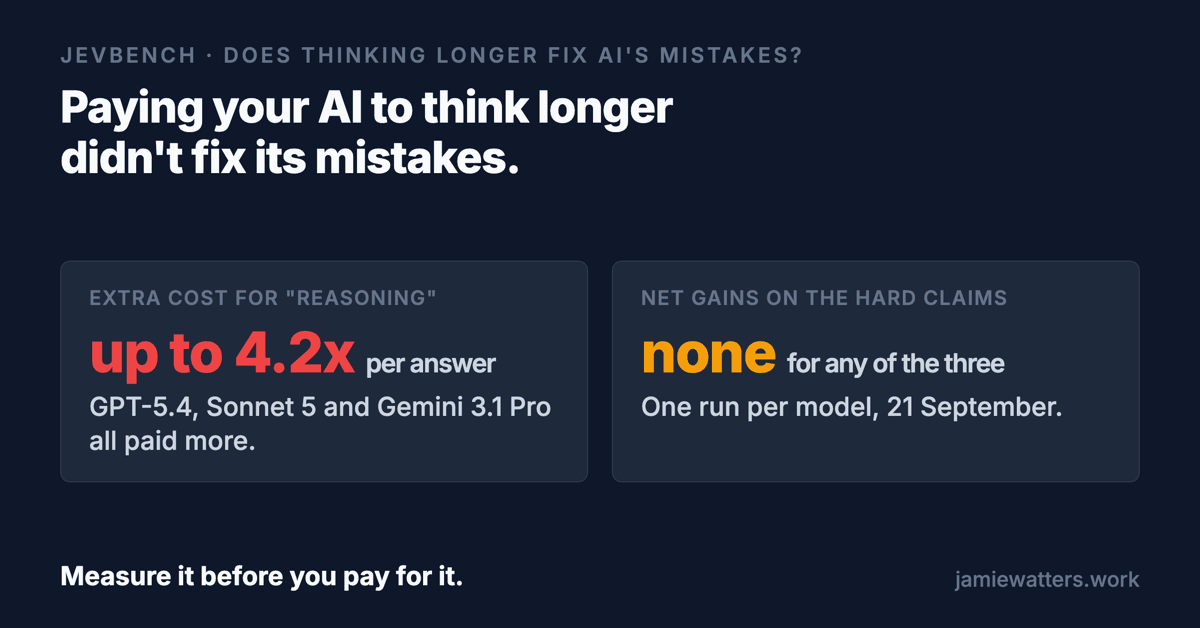
Paying your AI to think longer didn't fix its mistakes. It cost up to 4.2x more.
I gave three AI models room to think before answering, the fix everyone assumes will work. None got more reliable. It cost 2.4 to 4.2 times more per answer to find that out, and Jev, the cheap specialist model, still caught more of the mistakes.
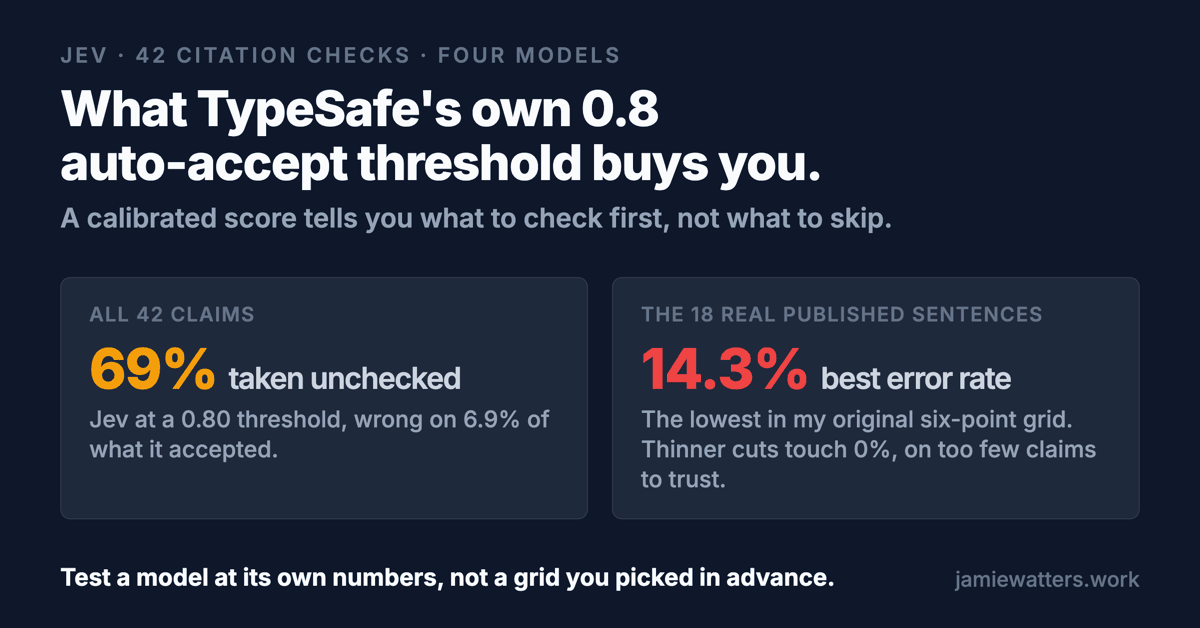
GPT-5.4 beats Jev on a confidence threshold, once tested at its own values.
I published a wrong finding last week: that GPT-5.4's confidence score has no usable threshold. It does, and swept over its own values it beats Jev at every…
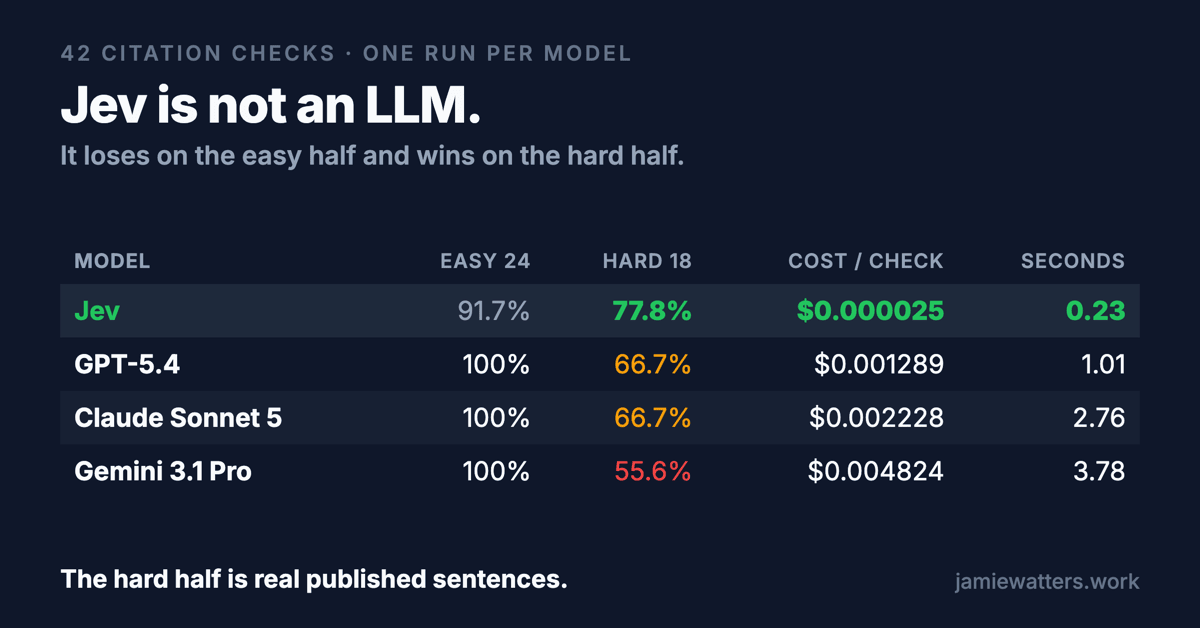
Jev is not an LLM. On the hard half it beat GPT-5.4, Gemini 3.1 Pro and Sonnet 5, at a fiftieth of the cost.
Jev does not generate text. You give it a question with defined answers and it hands back one of them plus a probability. On 42 citation checks it tied the…
The file your AI agent wrote for itself is making it worse. Ten minutes fixes it.
Somewhere in your project is a file your agent wrote, that your agent now reads as fact. Nothing in between checks it, so the good and the bad accumulate…
AI self-improvement fails at the scorer, in every case I could check
Google shipped a working self-improvement technique four days ago. One sentence in the paper explains why it works: the evaluator is frozen and sits outside the loop. Then look at the failures. Pseudo-labels that decay, a reward that gets gamed, a detector that gets bypassed, skills nobody scored. Different systems, same broken part. And if you run AI agents, you are already running the ungoverned version of this.
AI agent security: find the file your agents can write and every agent reads
In one research harness, a payload sitting in the file that loads into the next agent's system prompt infected that agent 55% of the time. The same payload in…
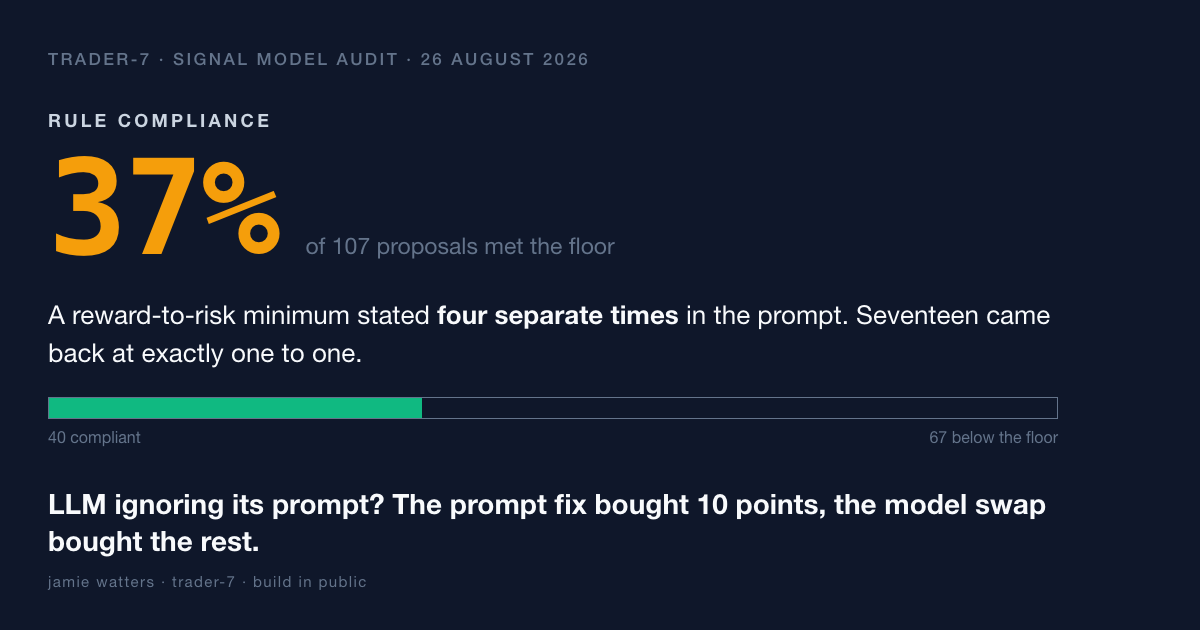
LLM ignoring its prompt? The prompt fix bought 10 points, the model swap bought the rest
Eight of 23 trade signals had the stop and the target at identical distance. The rule said 2:1 minimum. It was in the prompt four separate times.
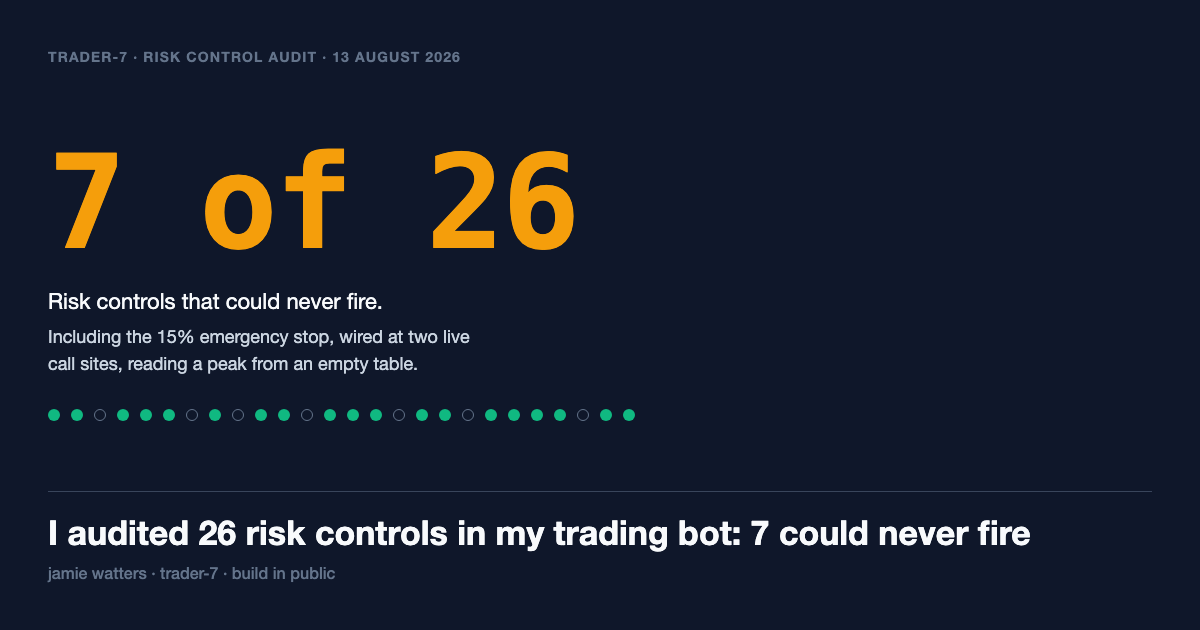
I audited 26 risk controls in my trading bot: 7 could never fire
The 15% drawdown halt was wired into two live code paths and could never fire. So I checked all 26 risk controls. Seven were dead. A control you cannot…
Opus 5 verbosity: where I wanted three sentences, I got Proust
I judge AI models by how often they make me swear. Opus 5 turned swearing into punctuation, and the reason is more interesting than I first thought.
Why AI checks fail silently: 1,278 restarts behind a healthy status
My auth check said healthy for three weeks on a dead credential. The pattern behind it costs more than the bug did.
Anthropic cut 80% of Claude Code's prompt. I cut my CLAUDE.md by 90% the same day.
An audit of 116 instruction files found one stale copy telling twenty repos they were a different project, two files no session has ever read, and 453 lines loaded twice. Here is what to delete from your own CLAUDE.md, and the method that beats judgement.
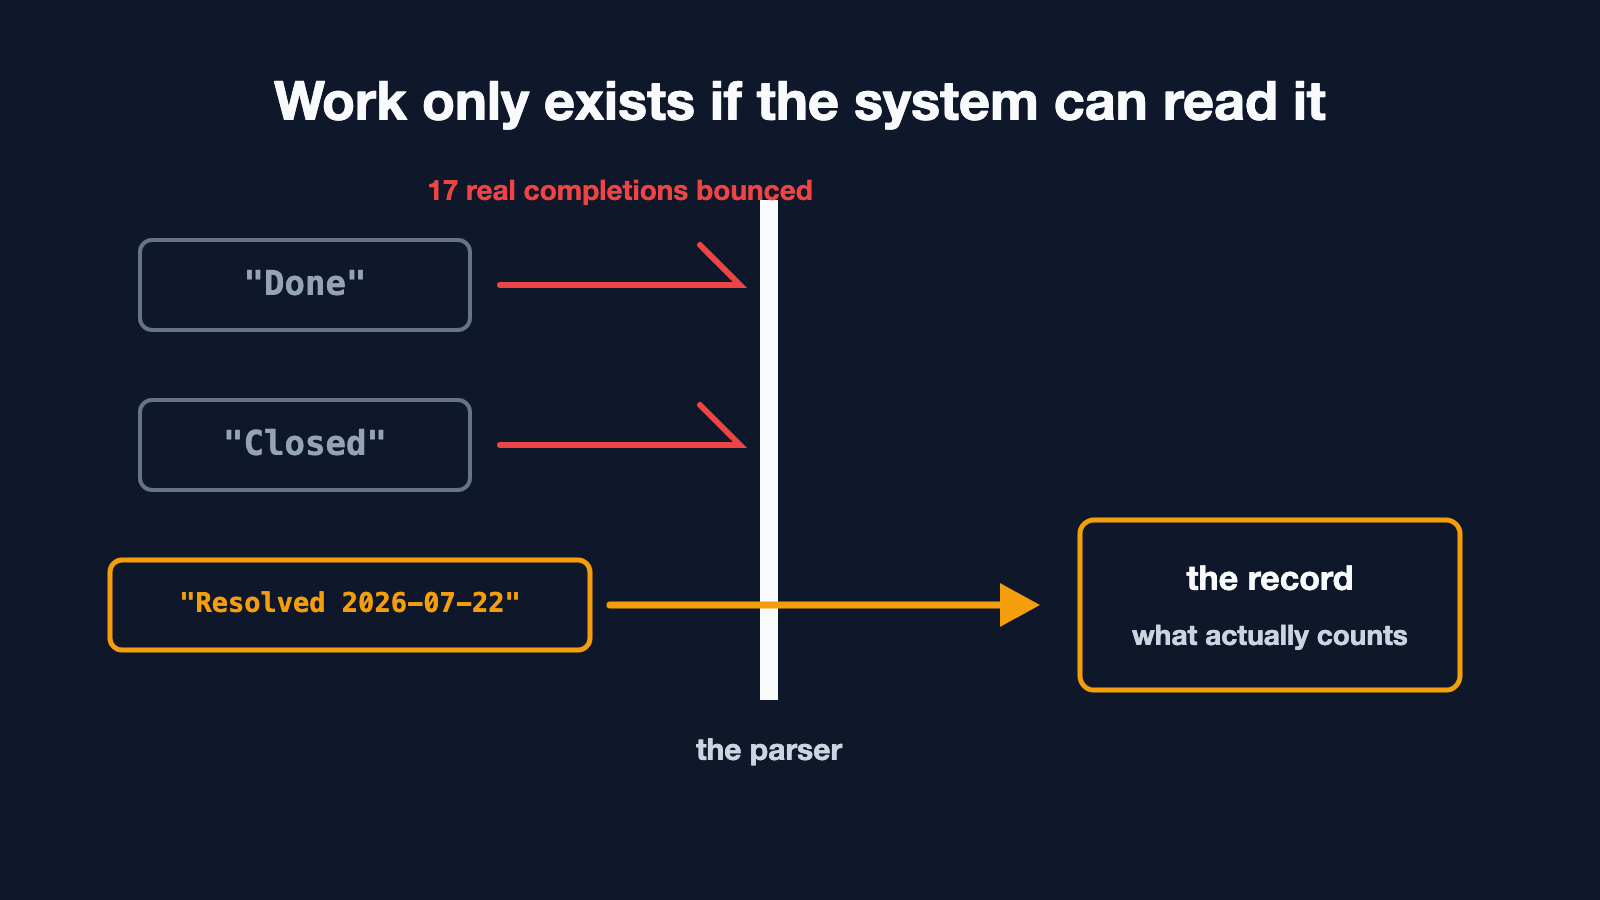
My AI Agents Kept Losing My Work. The Fix Is Older Than Computers.
Seventeen finished pieces of work were invisible to my own tracking system, and the cause wasn't effort or memory. A Berkeley talk gave me the name for what fixed it: an ontology. Here's the version that fits a one-person company.
Garry Tan Just Described My Setup. Then I Noticed What He Left Out.
The YC president gave a talk describing, almost item for item, the AI system I already run. The validation lasted about ten minutes. Then I noticed the word neither of us was saying.
I Leaked an API Key and It Turned My Own Domain Into a Phishing Weapon
I got phished from my own verified domain, using an API key I'd leaked myself: what actually leaked, how fast it happened, and what I changed.
I Almost Told You a Lie. Six AIs Handed It to Me, in Unison.
A field note from researching Graphify: the real privacy model, the honest token numbers, and why I check the source before I publish.
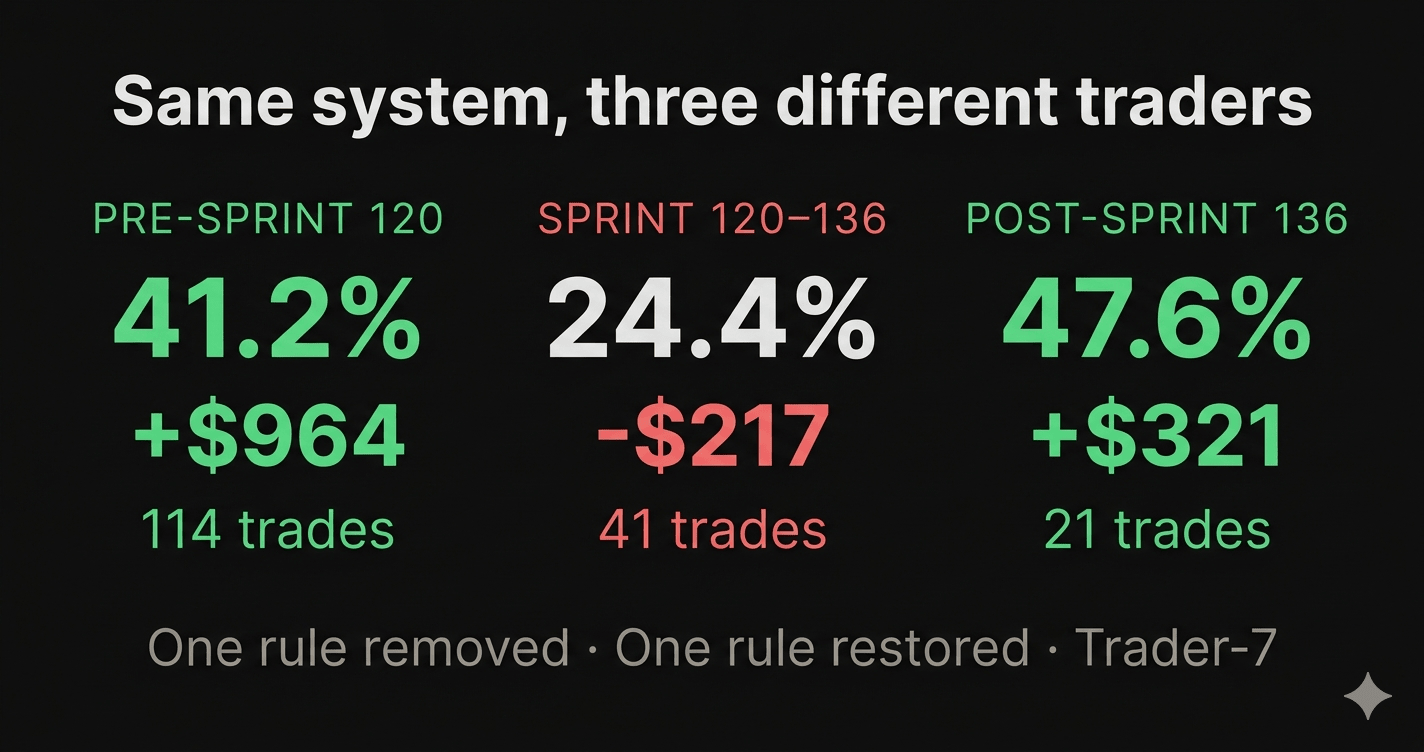
Same system, three different traders
Same code, same market, three time periods. One made $964, one lost $217, one's up $321. The difference wasn't the algorithm.
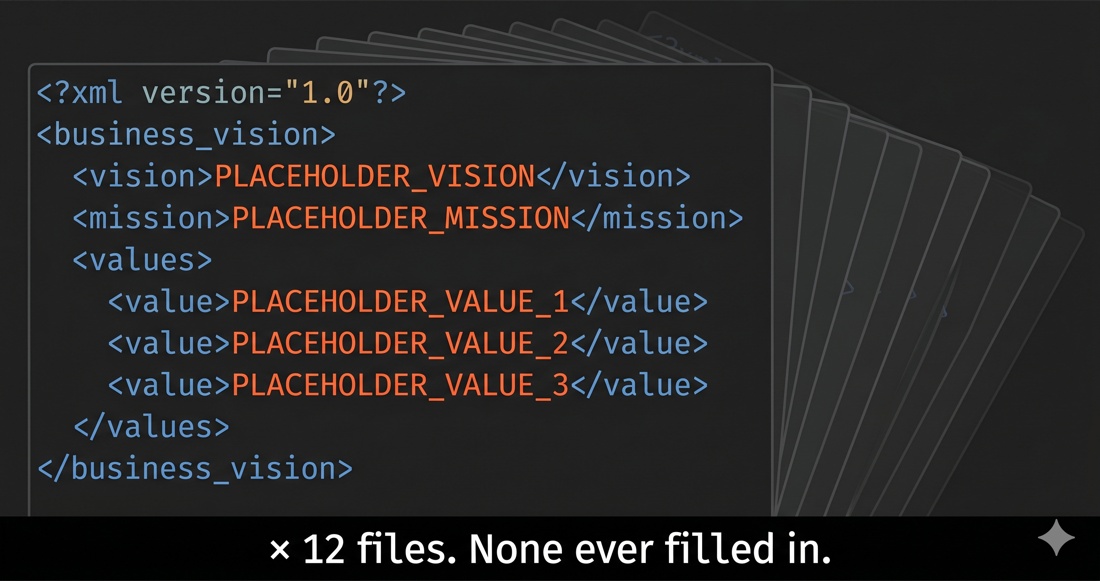
BOS-AI had twelve XML files holding nothing
I checked the XML files BOS-AI used to store 'institutional memory' for thirty agents. Every tag was PLACEHOLDER_X. So I deleted all twelve.