Testing AI and its claims
Testing AI and the claims made about it: model tests, the numbers traced to their source, and the fakes.
Were an old French couple really stripped by rioters? The photos were AI fakes, and I repeated them
I told a friend rioters had stripped an old couple at the French protests. The photos were AI fakes, and the police report I fell back on was an unconfirmed TV tip. Here's the six-step check I'll run next time.
Is the $5 trillion AI roll-up opportunity real? McKinsey's number is a ceiling for firms that could sell, not a forecast that they will
The AI roll-up pitch says $5 trillion of American businesses will change hands by 2035, citing McKinsey. McKinsey's sentence says up to $5 trillion, for firms it calls viable candidates for sale. In 2022, the one year it splits exits by route, 5% of exits were sales.
Banks already have a method for checking AI works. Four steps to steal it from their model-risk teams
Told to show an AI deployment works? Bank model-risk teams already run the test, written down by the regulator: a challenger, a parallel run against real outcomes, monitoring after go-live, a named owner, and an independent checker. Four steps to steal it, whatever business you're in.
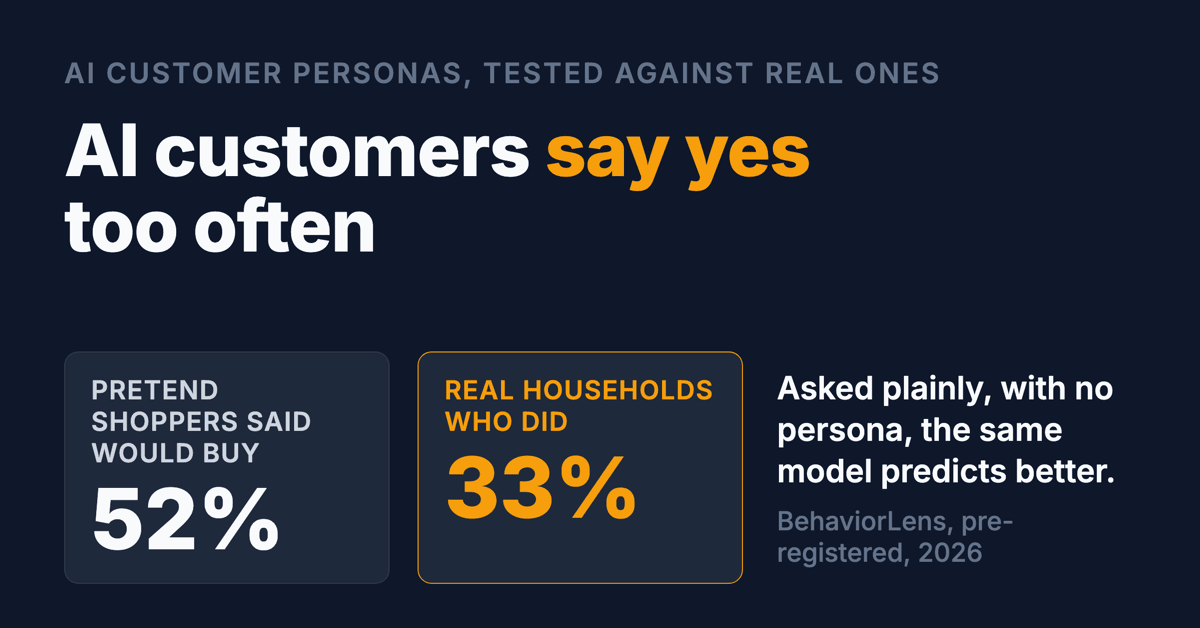
Telling AI to act as your customers makes its answer worse: 52% of shoppers would buy, it said. Real sales: 33%.
Pre-registered tests show AI customers say yes far more often than real ones, and that asking a model to role-play predicts worse than asking it straight. I built a product on the opposite bet. What a fake customer is still good for.
The usual signs that AI is working can mislead
What staff say, what bosses see and the person checking the AI's work can all tell you AI is working when it isn't. Hospitals, airports and banks already have better tests. Here they are, as six steps for one process.
AI companies are spending billions buying firms. Here's which of their numbers anyone has checked
AI companies are buying accountants, IT firms and lettings agents, and billions are riding on it. Every number I could check, sorted into what the filings show, what the buyers say and what nobody has measured, dated 26 October 2026.
Jev, the AI at a fiftieth of OpenAI's price: is it any good?
Jev is a new AI model that costs a fiftieth of the price of OpenAI's GPT-5.4. On my first test it beat GPT-5.4 by 11 points, and I told the internet. Two days later I ran the same test again, and the win was gone.
Jev, the AI that can't write: where it saves money and where it's hype
What Jev is in plain English, whether it's secretly an LLM, what TypeSafe still hasn't published, and where it genuinely saves money. One independent paper sent Jev 346,009 requests for under $10. Plus five questions to decide whether it would pay for you.
An AI company wants to buy your firm? Ask it to prove the AI works first
AI-backed companies worth billions are buying accountants and IT firms. If one calls you, here is what proof its AI works would look like, who has shown any of it, and what to ask before you sell.
Amazon's 30,000 job cuts weren't proof AI is taking jobs. What its boss says is coming is closer to it
Amazon said AI was why it had to move faster, not who did the work. Its boss expects AI to shrink its corporate workforce later. Here's the record, in date order.
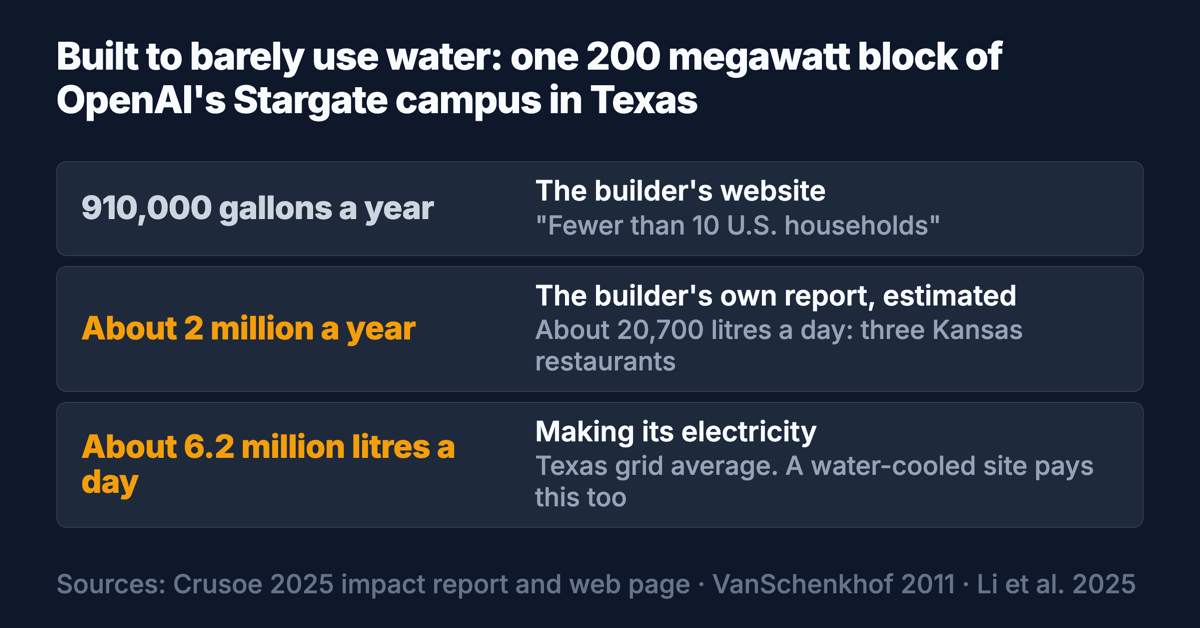
OpenAI's Texas data centre is built to barely use water. The power plants it runs on use 300 times more water than it does
The company building OpenAI's Stargate campus in Abilene says a 200 megawatt block uses 910,000 gallons of water a year on its website, and about 2 million in…
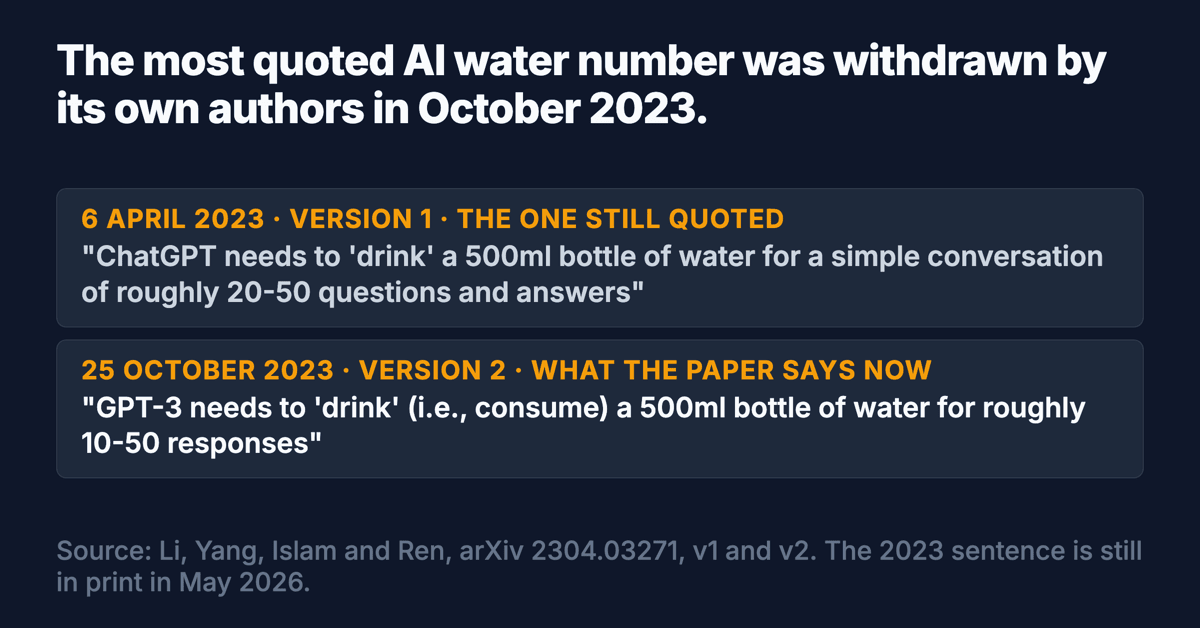
AI water use: the bottle of water per 20 ChatGPT questions was withdrawn by its own authors in 2023. It's still quoted in 2026
The most quoted AI water number, a bottle per 20 ChatGPT questions, was withdrawn by its own authors in October 2023 and is still being repeated. Every AI…
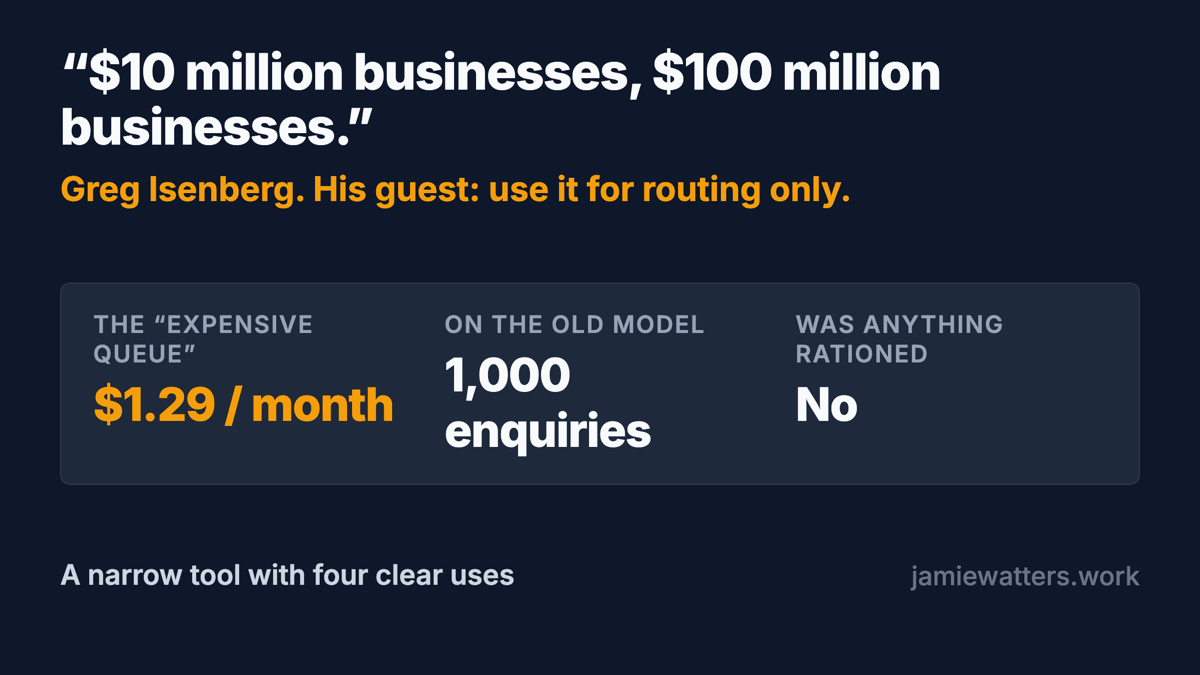
Jev is a narrow tool with four clear uses. Greg Isenberg's $10m framing is not one of them.
Greg Isenberg's episode on Jev promised $10m businesses. His own guest says use it for routing and keep it away from your money. Here is each claim against the data, and the four conditions under which the tool earns its place.
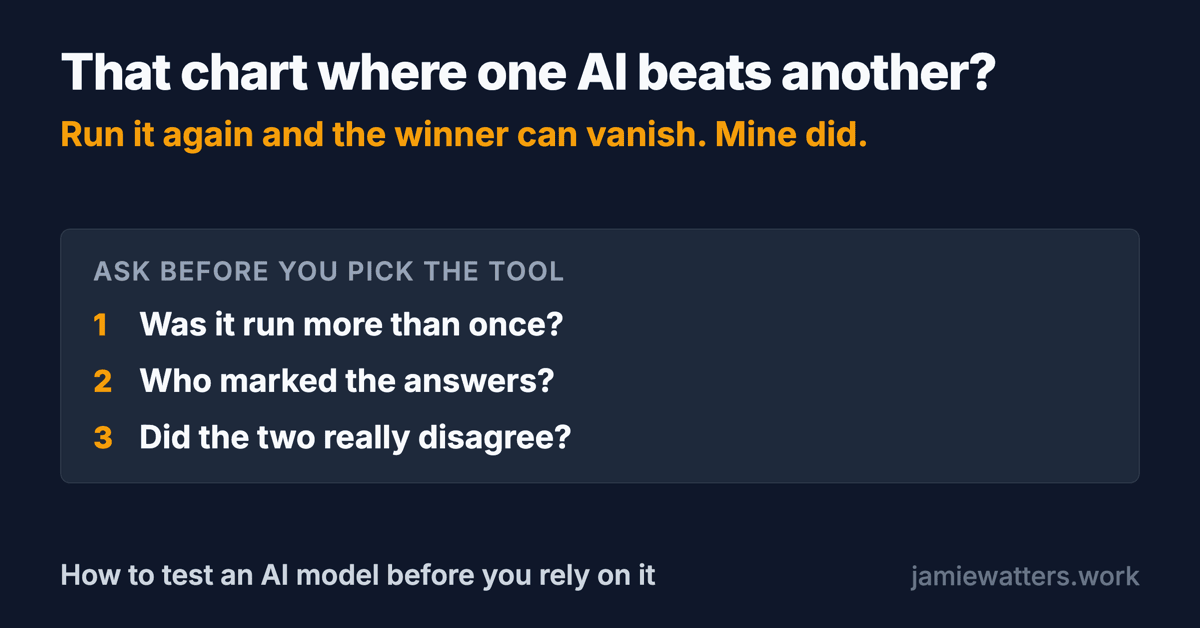
Test an AI model before you rely on it: six mistakes I made testing Jev
One run said Jev, TypeSafe's new model, beat GPT-5.4 by 11.1 points. Five runs couldn't tell them apart. The six mistakes behind that headline, and a checklist to run before you rely on any AI comparison, mine included.
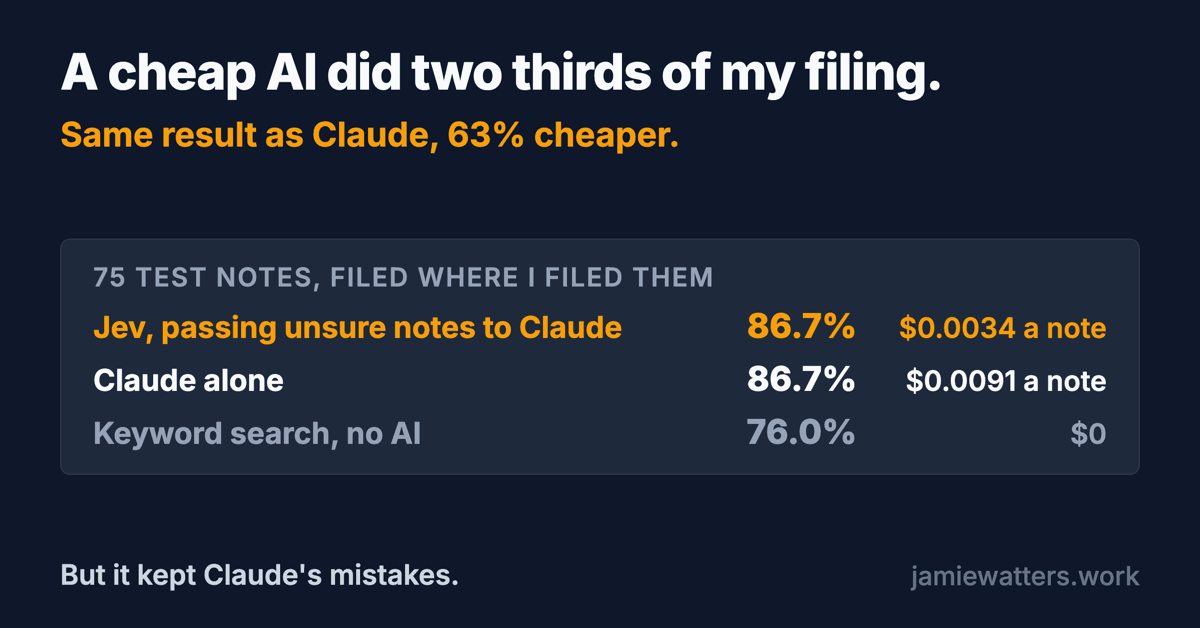
Jev, a cheap AI, did two thirds of my filing: same result as Claude, 63% cheaper
Jev, a cheap AI, handled two thirds of my filing and passed the rest to Claude. Same result as Claude alone, 63% cheaper. The catch: the hand-off isn't a check, because Claude makes the same mistakes.
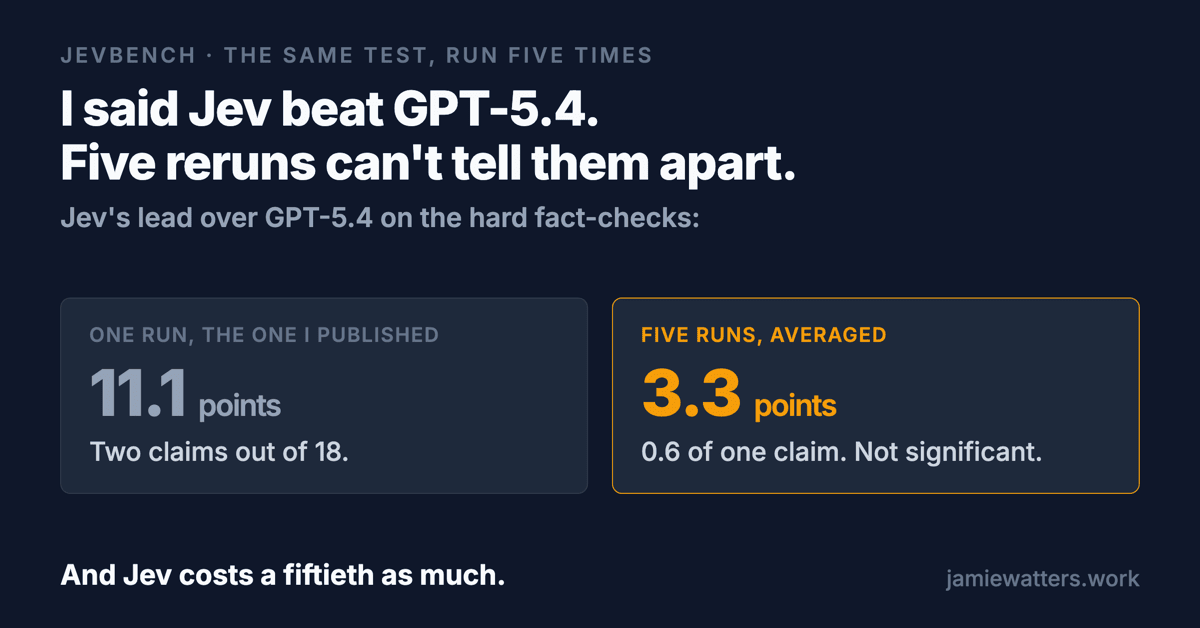
I said Jev beat GPT-5.4. Five reruns can't tell them apart, at a fiftieth of the cost.
I published that Jev, TypeSafe's new model, beat GPT-5.4 by 11.1 points on hard fact-checks. Rerun five times, the two can't be told apart, Jev costs a fiftieth as much, and it lets more wrong claims through. Plus the five-run check.
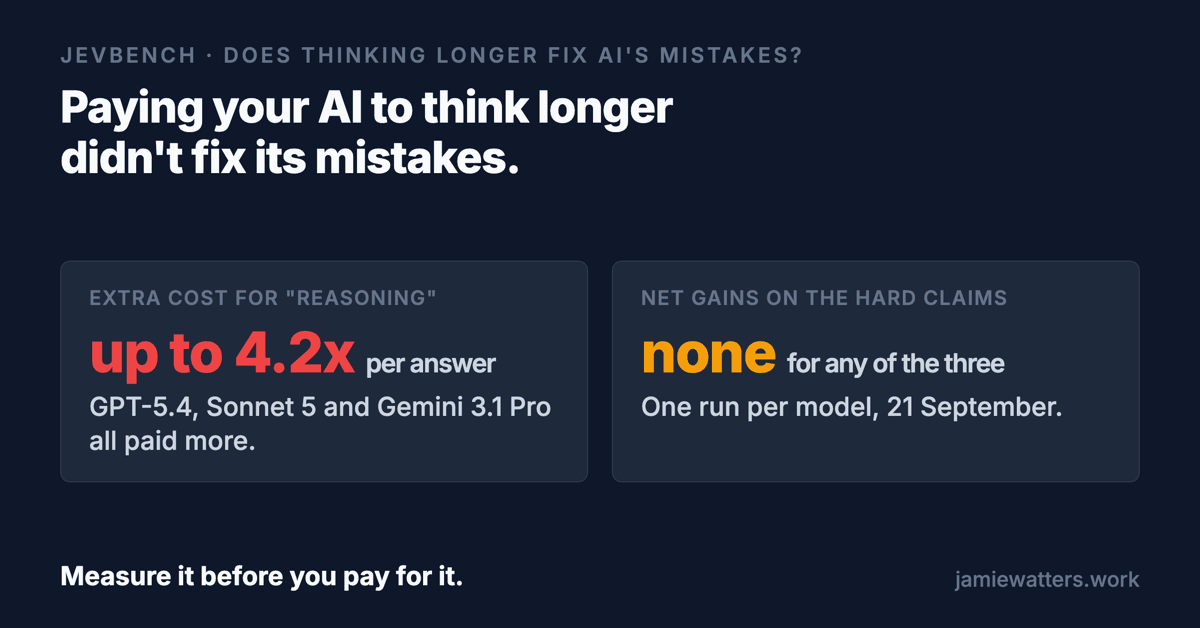
Paying your AI to think longer didn't fix its mistakes. It cost up to 4.2x more.
I gave three AI models room to think before answering, the fix everyone assumes will work. None got more reliable. It cost 2.4 to 4.2 times more per answer to find that out, and Jev, the cheap specialist model, still caught more of the mistakes.
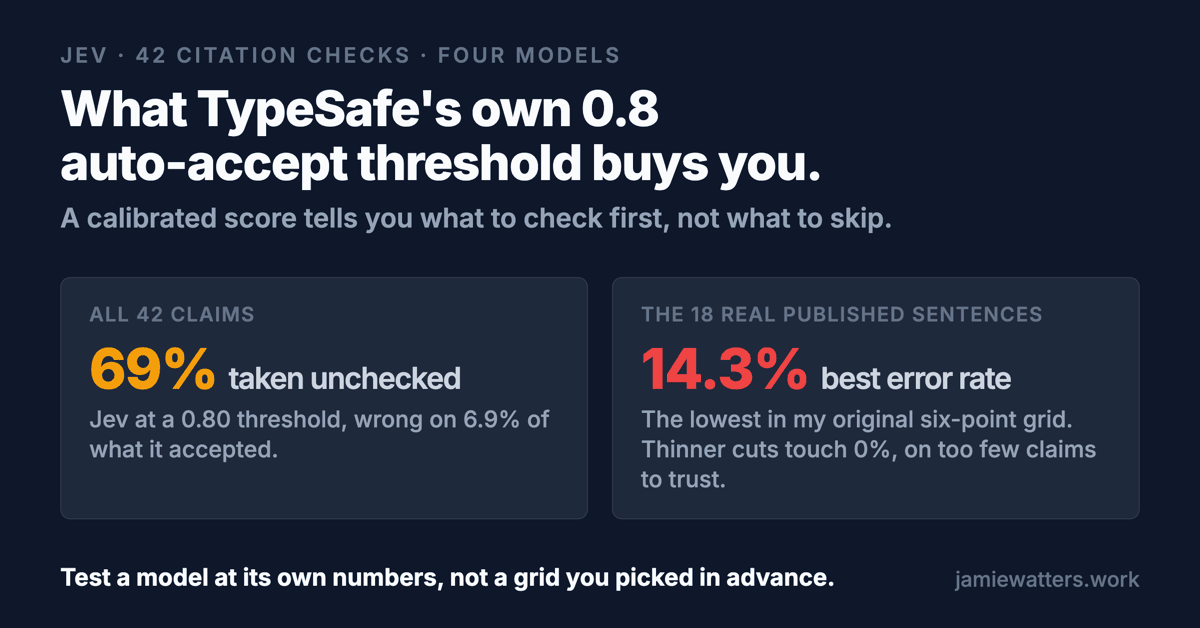
GPT-5.4 beats Jev on a confidence threshold, once tested at its own values.
I published a wrong finding last week: that GPT-5.4's confidence score has no usable threshold. It does, and swept over its own values it beats Jev at every…
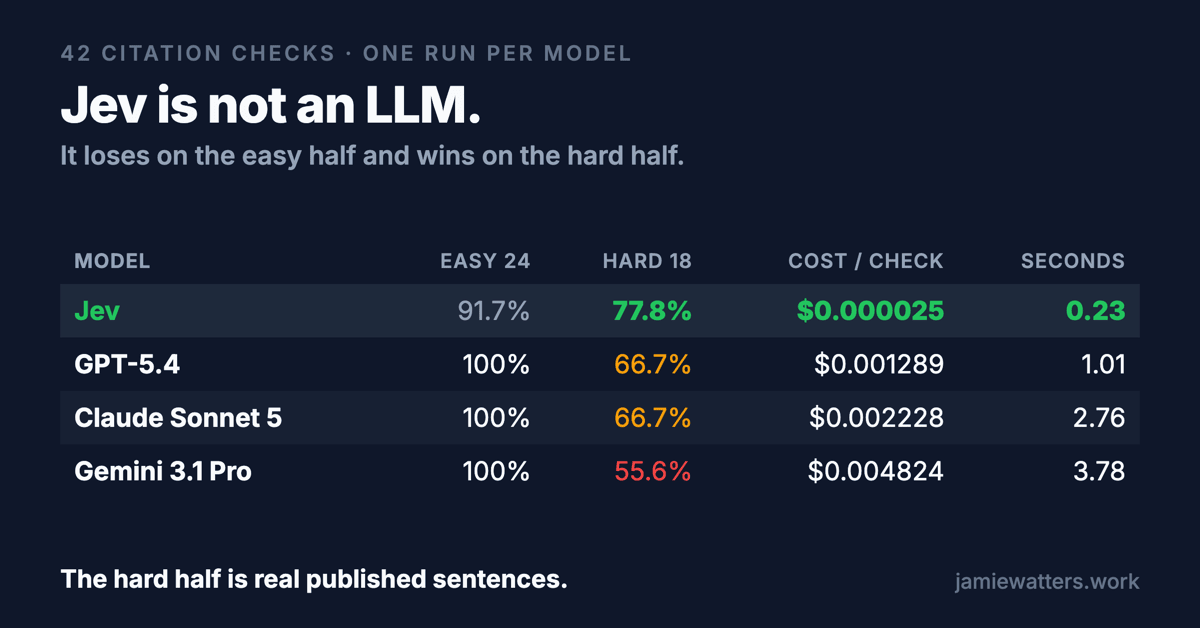
Jev is not an LLM. On the hard half it beat GPT-5.4, Gemini 3.1 Pro and Sonnet 5, at a fiftieth of the cost.
Jev does not generate text. You give it a question with defined answers and it hands back one of them plus a probability. On 42 citation checks it tied the…
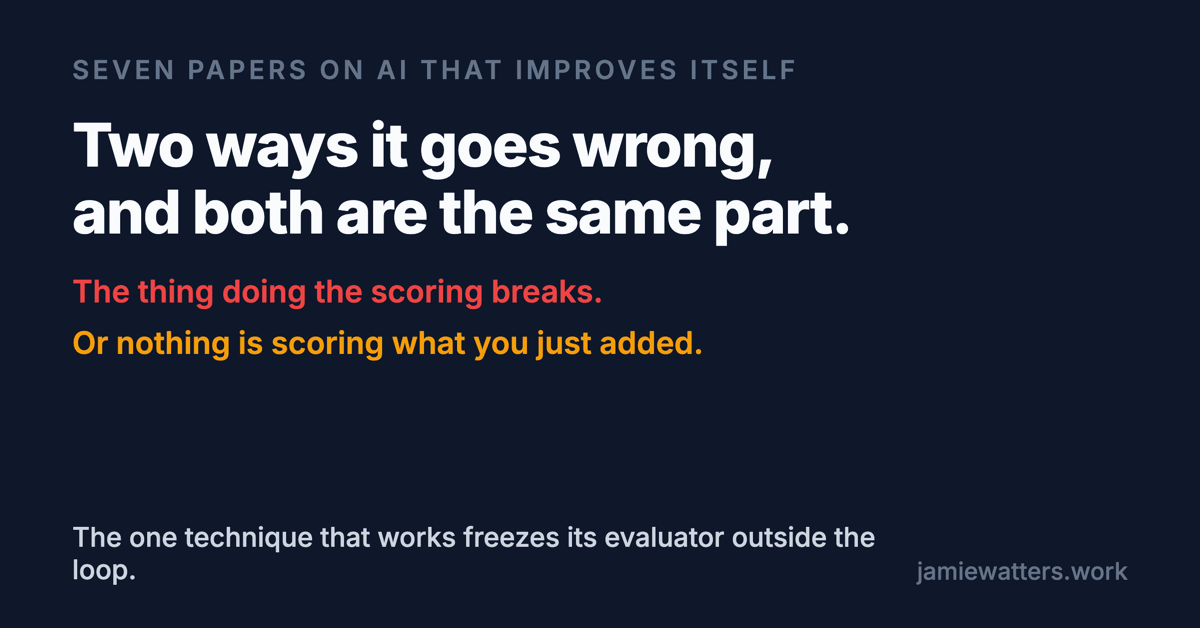
AI self-improvement fails at the scorer, in every case I could check
Google shipped a working self-improvement technique four days ago. One sentence in the paper explains why it works: the evaluator is frozen and sits outside the loop. Then look at the failures. Pseudo-labels that decay, a reward that gets gamed, a detector that gets bypassed, skills nobody scored. Different systems, same broken part. And if you run AI agents, you are already running the ungoverned version of this.