The file your AI agent wrote for itself is making it worse. Ten minutes fixes it.
Jamie Watters
Operational resilience and AI delivery practitioner.
Open your project and look for a file your agent wrote.
You are looking for one thing: whatever your tool writes to between sessions, and reads at the start of the next one. Every tool calls it something different, so here is where to look.
- In your project folder, a file called
CLAUDE.md,AGENTS.md,.cursorrules, or anything with "memory", "context", "rules" or "instructions" in the name. - In the hidden folders, the ones starting with a dot:
.claude,.cursor,.github. Your file browser hides these by default. On a Mac, press Cmd, Shift and full stop together to show them. - In the tool itself, not on disk at all. Several of them keep this in a settings panel called Memory, Rules, Custom Instructions or Project Instructions. If you have never seen a file, look there.
If you find more than one, start with the one that loads automatically at the beginning of a session. That is the one doing the most work.
Found it? Good.
Your agent wrote that. Your agent now reads it as instruction. And in between those two things, almost certainly, nothing checked whether what it wrote was any good.
That's the whole article. The rest is why it matters and what to do in the next ten minutes.
This has a name, and you're already doing it
When people say AI that improves itself, this is the boring version of it, and it's the version that's actually in your project right now. The agent does some work, writes down what it learned, and the next agent starts by treating that as true.
It's a loop. Work, write, load, work.
The thing nobody mentions is that the loop has no brakes. Nothing measures whether the file made the next run better or worse. It just gets longer.
Somebody measured this
A benchmark called SkillsBench ran the test properly, which almost nobody does. Same tasks, same models, three conditions: no skill files, skill files a human curated, and skill files the model wrote for itself.
The tasks weren't graded by an opinion. They were graded by tests that pass or fail.
Curated files raised the average pass rate by 16.6 percentage points (SkillsBench, 2026), from about a third of tasks to about half. That's a big lift and it's why skill files are having a moment.
Files the model wrote for itself came out below using no files at all, by between 8 and 11 points, on all three setups they tried (SkillsBench, 2026).
Same kind of artefact. Helpful when a person curated it. Worse than nothing when the model made it alone.
One caveat, because it matters. That test had a model write the files fresh and then hand them straight to another model to use. It is not the same thing as a file that grows over months, which is what you have. It is the closest measurement anyone has published, and it is adjacent to your situation rather than identical to it. What follows is the part I can argue from how the thing works, rather than from a number.
What that actually means for you
It doesn't mean your agent writes rubbish. Some of what it writes is good, and you already know that, because your file is why it stopped suggesting the wrong framework and stopped forgetting your deploy command. Those lines are the reason you let it write the file in the first place, and I am not asking you to stop.
That early usefulness is exactly what makes this hard to spot later. The first twenty lines earn their place. Nothing removes the next two hundred.
It means nothing separates the good from the bad, so both accumulate. And that is why this is worth your ten minutes rather than a shrug: the benchmark measured it, but you don't need a benchmark to see it coming. If nothing ever removes a line, the file only grows. If the file only grows, the proportion of it that is stale, wrong or irrelevant only rises. That happens in every setup that has no step for taking things out, which is nearly all of them. And because they accumulate in the file the next agent reads first, the bad bits don't sit quietly in a corner. They arrive at the top of every session dressed as a fact.
A few specific ways it goes wrong, all of which I've found in my own setup:
Something true once becomes true forever. The agent hits a bug on a Tuesday, writes down "always do X to avoid Y", and you fix Y on Wednesday. The instruction stays.
A guess gets recorded as a finding. It couldn't work out why something failed, formed a theory, wrote the theory down. The next agent reads a theory and sees a fact.
The file gets long. Not wrong, just long. Everything in it competes for the agent's attention with everything else, and the useful line from March is now buried under forty lines of housekeeping.
None of these announce themselves. Your agent doesn't get visibly worse. It just quietly stops being as good as it was, and there's no error message for that.
The ten minute check
Go and open the file. Actually open it. Read the whole thing.
Then, for each thing in it, ask one question: would I have written this?
Not "is it true". Would you, knowing what you know about your project, have chosen to tell a new developer this on their first day.
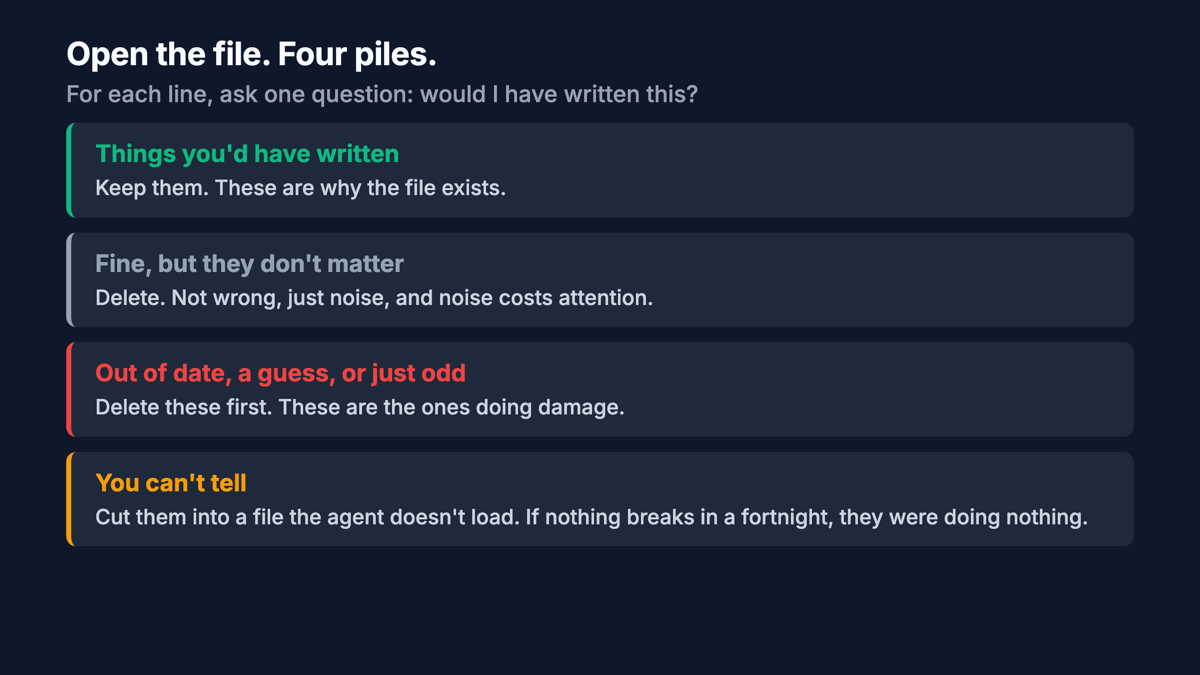
You'll find four piles.
Things you'd have written. Keep them. These are the reason the file exists.
Things that are fine but don't matter. Delete them. They're not wrong, they're noise, and noise costs attention.
Things that are out of date, or a guess, or just odd. Delete these first. These are the ones doing damage.
And a fourth pile, because you will need it: things you cannot tell. Don't delete those and don't leave them. Cut them into a separate file that the agent doesn't load. If nothing breaks in a fortnight, they were doing nothing. If something does, you know exactly which line to put back.
I did this on my own setup and found that almost every one of my agent setup files told it to write its lessons into the file every later session reads. I'd written those instructions myself, and I had never once gone back to read what had been written into it.
Three things that stop it happening again
One. Date every line. Whatever your agent writes, make it write when. A line from six months ago and a line from yesterday should not look the same, and right now they do.
Two. Give it somewhere to put guesses. A separate section, marked as unconfirmed. The agent still records what it thinks, and the next one knows not to treat it as settled.
Three. Read the file on a schedule. Once a month, or after anything big changes. Put it in your calendar, because a rule you have to remember is a rule you'll skip.
Four, and this is the one I missed. Go and find the instruction that tells the agent to write to the file at all. It's in your setup somewhere, because it didn't start doing this on its own. Read it. Mine told the agent to record every lesson it learned, with nothing about when not to, and I'd written that myself. Cleaning the file without changing that instruction means you'll be doing it again next month.
None of that is clever. All of it is the difference between a file that helps and a file that accumulates.
The one idea worth keeping
The thing worth keeping is that the writing was never the problem. Your agent writes decent notes.
What's missing is anything that takes one back out.
Right now, for most people building with agents, nothing does.
Go and read the file.
The long version of this, with the papers, the numbers and where the research is weaker than the headlines suggest, is at AI self-improvement fails at the scorer. The SkillsBench figures above are from version 4 of that paper, revised 14 June 2026: 87 tasks across 8 domains, 18 model and harness configurations for the curated result, three for the self-generated one.