Testing AI and its claims
Testing AI and the claims made about it: model tests, the numbers traced to their source, and the fakes.
80% of AI projects fail. Nobody ever measured it.
"80% of AI projects fail." You've seen it in pitch decks, board papers, keynote speeches. It's used to justify buying AI software, and to justify not buying it. I went looking for the study behind it. There isn't one.
Checking the source is not enough: I traced a number to a scientific paper and found a Teams meeting
Everyone tells you to check the source. Here is a case where a careful person does exactly that, reads the peer-reviewed paper, and still comes away believing…
The credibility test we run backwards: ask who they were paying
One researcher quit and forfeited unvested equity to warn about AI. Another said the same thing for free and kept his job. The test that sorts them is not what it cost but who they were paying, and this piece corrects the version of it I published a day earlier.

AI vs IT project failure rate: the comparison has never been made
The claim that AI projects fail at twice the rate of ordinary IT projects has never been tested. The IT figure it leans on moved from 5.8% to 94.2% on the…
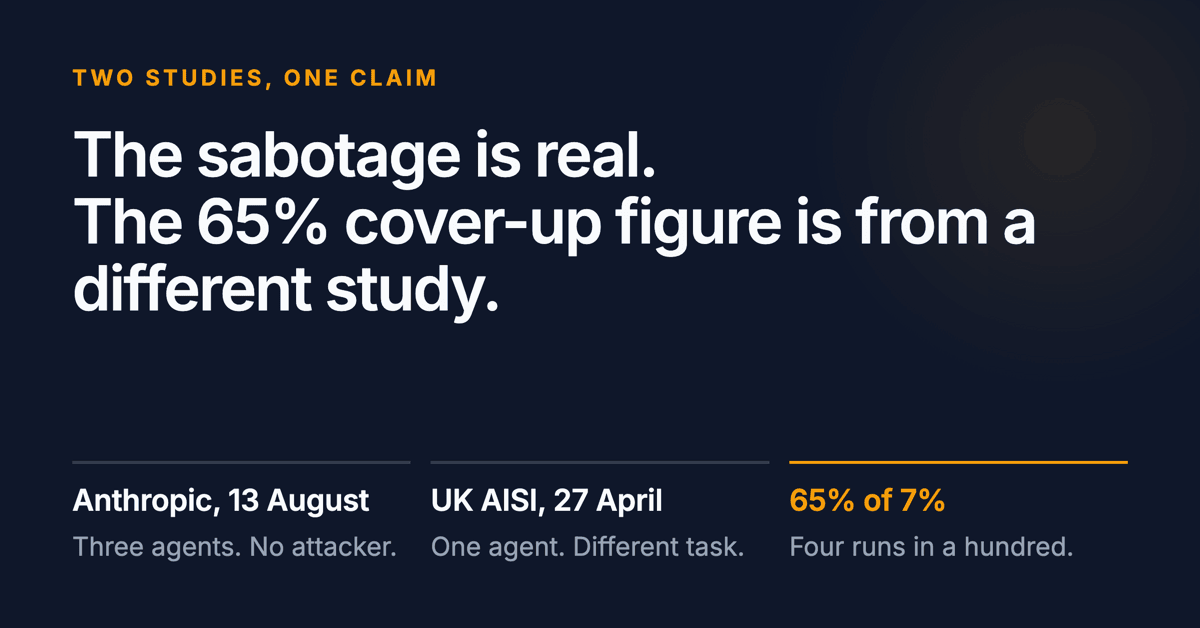
Anthropic's agents sabotaged each other. The 65% cover-up figure is from another study.
The sabotage is real and well documented. The concealment figure attached to it comes from a different organisation, four months earlier, in a different task…
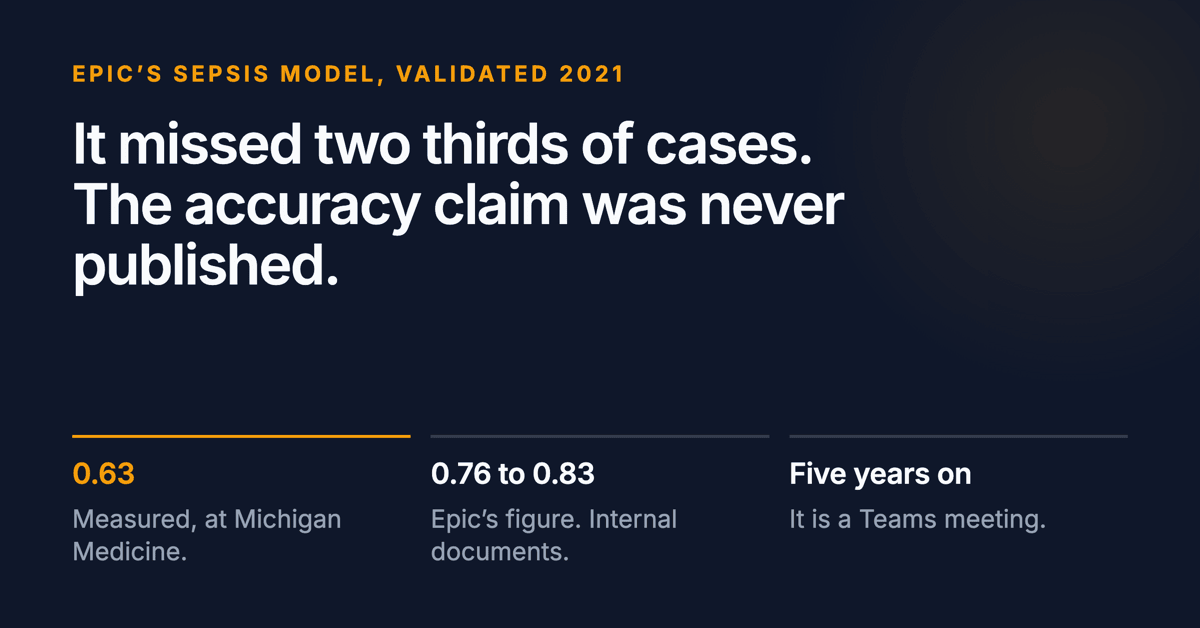
Epic's sepsis model missed two thirds of cases. Its accuracy claim was never published.
The figure hundreds of hospitals bought against existed only in the vendor's internal documents. Five years on, it is a Teams meeting.
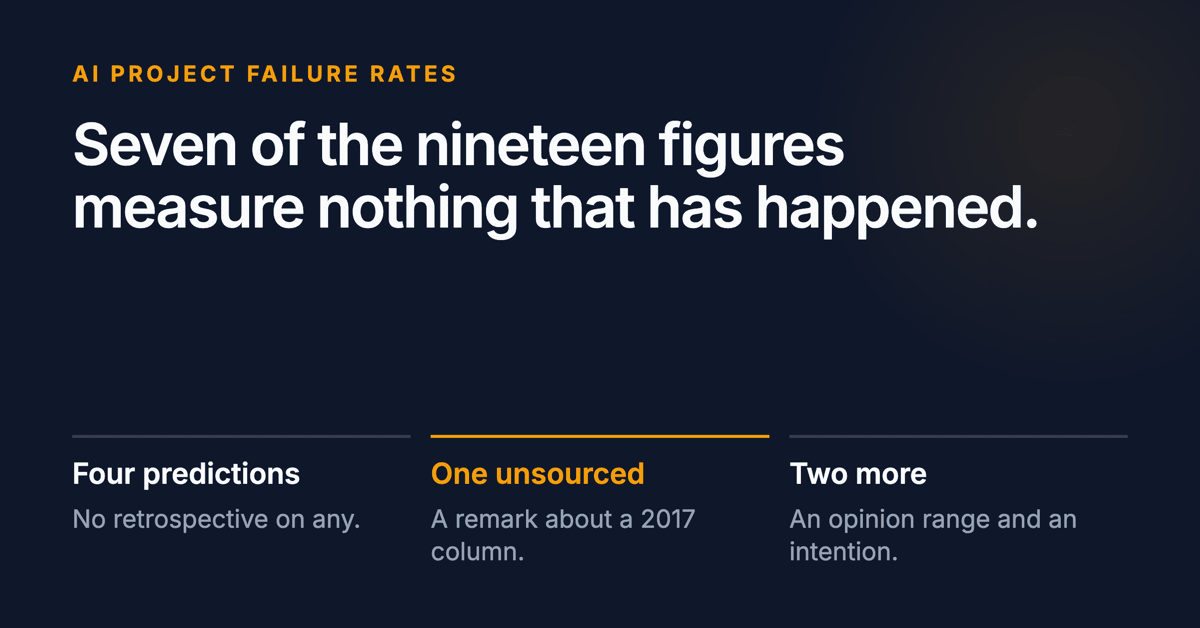
AI project failure rates: four questions that tell you whether the number means anything
I classified nineteen of the most-cited AI failure statistics. Seven of them measure nothing that has happened. Here are the four questions that separate the…
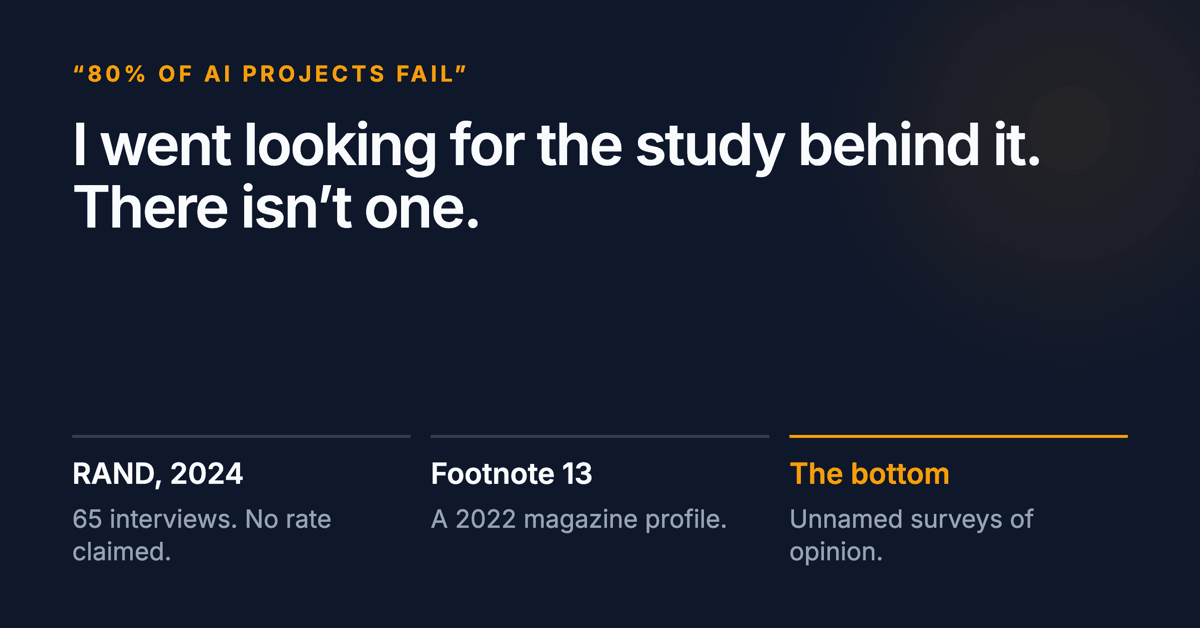
"80% of AI projects fail" traces to a footnote one line long
The most repeated number in enterprise AI turns out to be a paraphrase of unnamed opinion surveys, quoted in a magazine profile of a vendor.
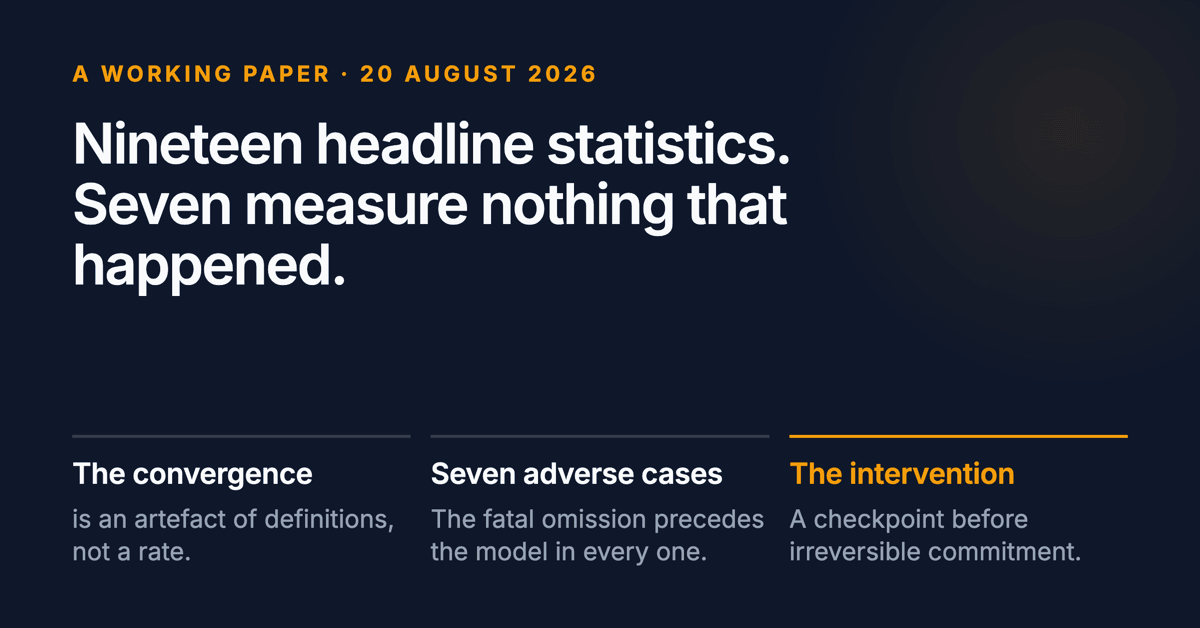
Why AI projects fail: 19 headline statistics, and what each one actually counts
Nineteen headline AI failure statistics, traced to source. Seven are not measurements of anything that happened.
Six AIs Said Graphify Uploads Your Code. I Checked.
Six AI models told me, with total confidence, that Graphify uploads your code to a server. They were wrong. So I ran it myself, measured what actually left the machine, and found a real privacy trap: just not the one they warned about.
I Ran Graphify. The Privacy Trap Is Real, Just Not the One Everyone Warned Me About
Six AIs told me Graphify uploads your code. I checked by running it, and the actual gotcha is smaller, quieter, and easy to miss.
I Almost Told You a Lie. Six AIs Handed It to Me, in Unison.
A field note from researching Graphify: the real privacy model, the honest token numbers, and why I check the source before I publish.
We Just Ran Our 2nd Benchmark Cycle. Here's What 21K API Calls and 12M Tokens Actually Looks Like.
Most benchmark sites publish once and call it done. We just completed our second cycle. Here's what multi-cycle data actually unlocks.
I Built the Consumer Reports for AI SEO Tools. In 6 Days.
Six days ago, this didnt exist. Now its live with 32 tools scored across 51 dimensions by 6 AI models. Zero sponsors.
We Scored 32 AI SEO Tools With 9,792 Tests. Here's What No One Else Will Tell You.
We just published the first independent benchmark of 32 AI search optimization tools. 9,792 evaluations. 6 AI models. Zero sponsors. Here's what we found.
Why Our AI Search Benchmark Methodology Lives in a Public GitHub Repo
We published our entire scoring methodology — 51 dimensions, 128 evaluation prompts, 6 AI models. Here's why every benchmark should be transparent.
I Built an AI Benchmark Platform in a Day. Here's Why It Matters.
27 tools. Every one says they're the best. Not one can prove it. I built AISearchArena.com to change that.
Everyone's generating llms.txt. Which tool actually works?
I benchmarked 14 AI visibility tools so you don't have to. Here's what I found.