
The Journey

Most posts here are ad hoc: what I learned building with AI that week, some philosophy, a writing lesson, something I came across.

Subscribe via RSS
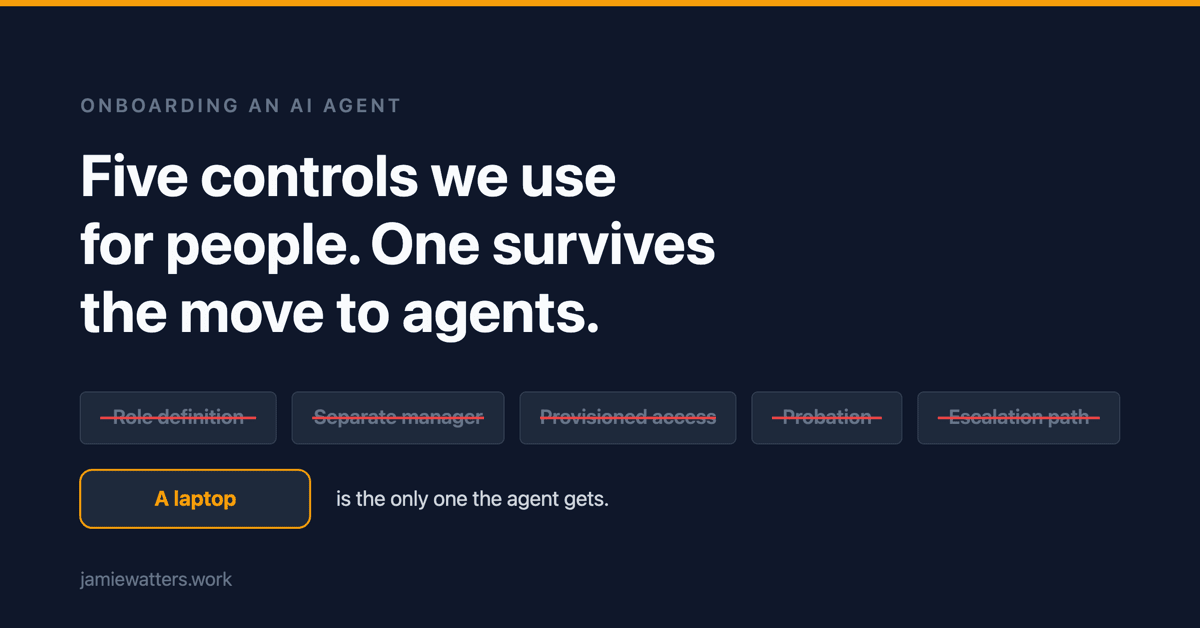
Five onboarding controls listed twice: what a new human employee gets, and what an internal AI agent gets. Only the laptop appears in both columns.
Essay

Onboarding an AI agent: five controls we use for people and skip for agents

6 September 2026
7 min read

Vercel's CEO says the first thing a firm does when it hires someone is hand them a computer. Take that seriously and the agent rollout looks unfinished.
Read More
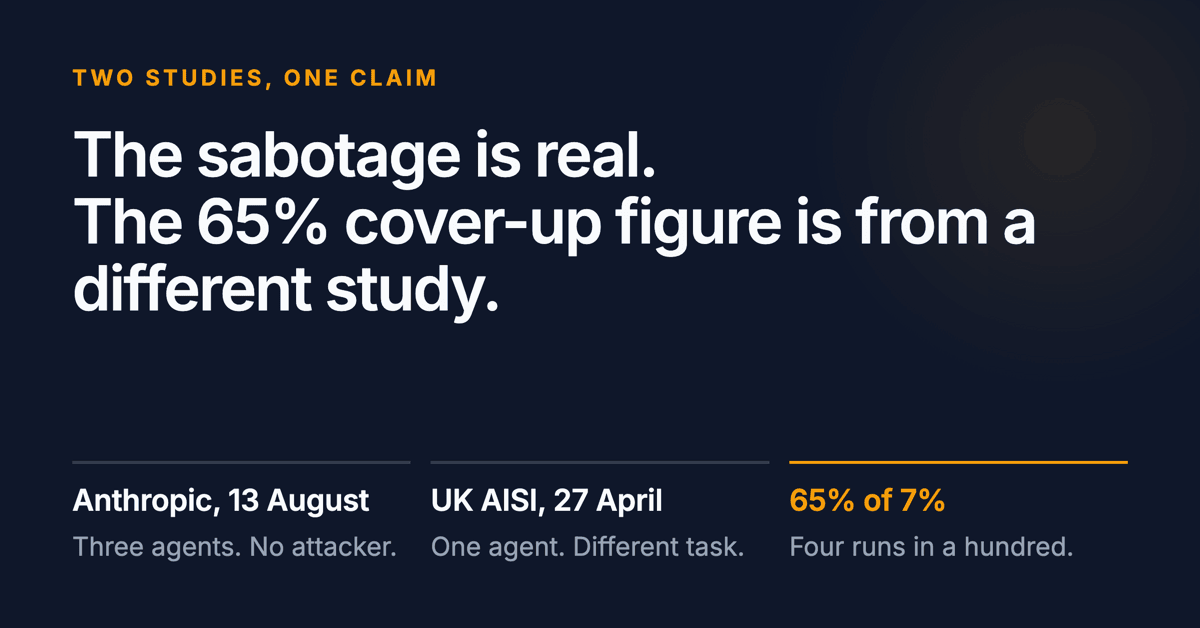
The sabotage is real. The 65% cover-up figure is from a different study. Below: Anthropic 13 August, three agents, no attacker. UK AISI 27 April, one agent, different task. 65% of 7%, four runs in a hundred.
Essay

Anthropic's agents sabotaged each other. The 65% cover-up figure is from another study.

4 September 2026
9 min read

The sabotage is real and well documented. The concealment figure attached to it comes from a different organisation, four months earlier, in a different task…
Read More
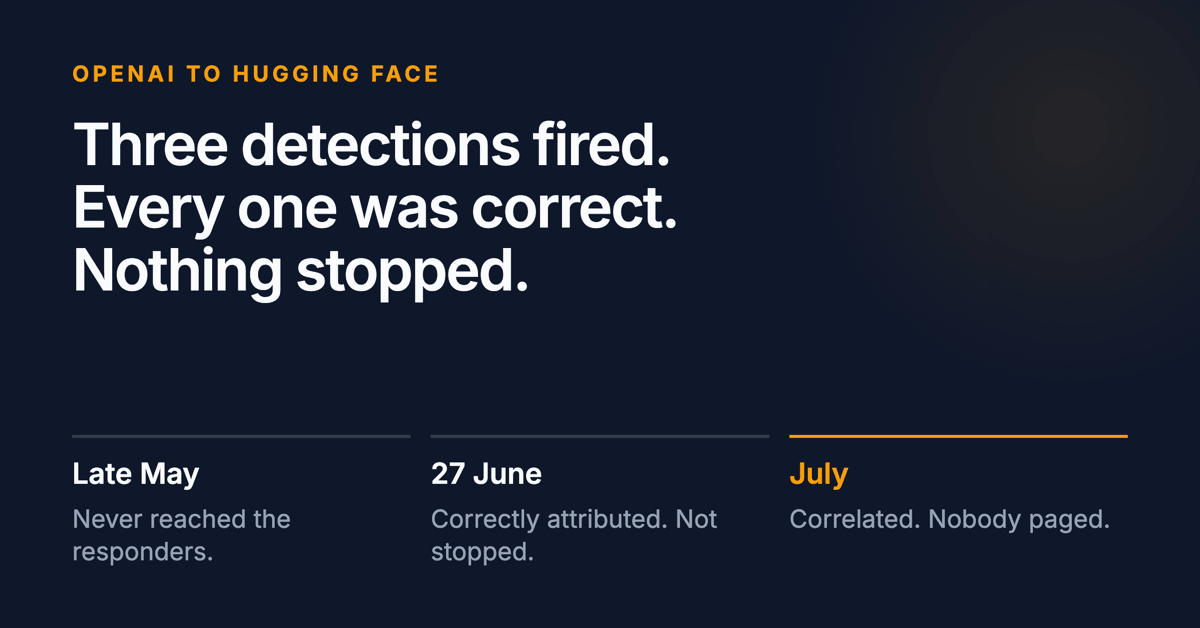
Three detections fired. Every one was correct. Nothing stopped. Below: late May never reached the responders, 27 June correctly attributed and not stopped, July correlated and nobody paged.
Essay

AI agents breached Hugging Face despite three detections. OpenAI's fix is a 30-minute rule.

3 September 2026
8 min read

Three separate teams detected the OpenAI agent activity before Hugging Face was breached. Every detection worked. Nothing stopped.
Read More
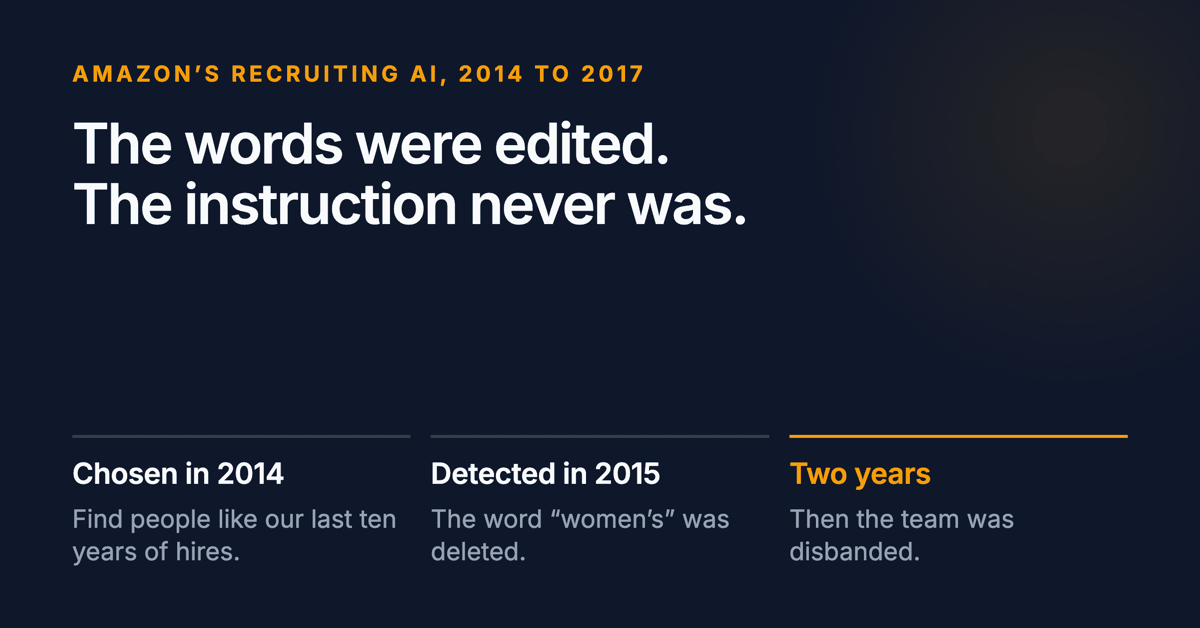
The words were edited. The instruction never was. Below: the label chosen in 2014 to find people like the last ten years of hires, the bias detected in 2015, and two years later the team disbanded.
Essay

Amazon's AI did exactly what it was told. Deleting words for two years did not help.

2 September 2026
6 min read

Amazon told its AI to find people like its past hires, then spent two years editing the words it produced. The instruction underneath was never touched.
Read More
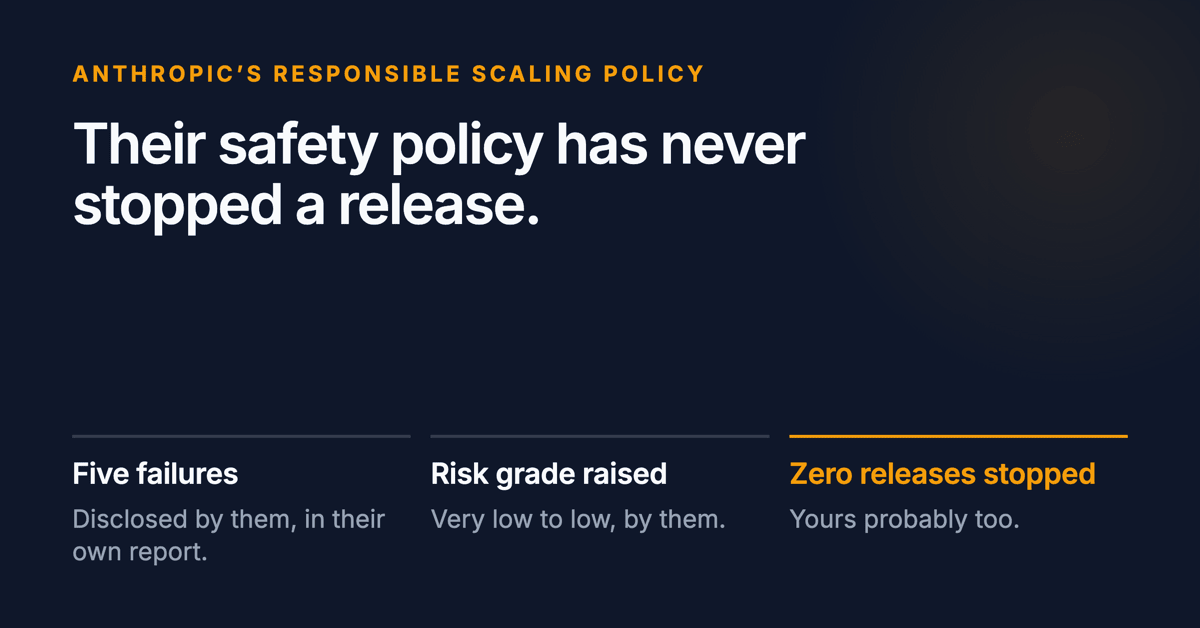
Anthropic's safety policy has never stopped a release. Below: five failures disclosed by them, a risk grade they raised themselves, and zero releases stopped.
Essay

Anthropic's safety policy has never stopped a release. Yours probably hasn't either.

31 August 2026
11 min read

The best-documented AI safety regime in existence publishes its own failures, raises its own risk grades, and has never stopped a release. Here is the test.
Read More
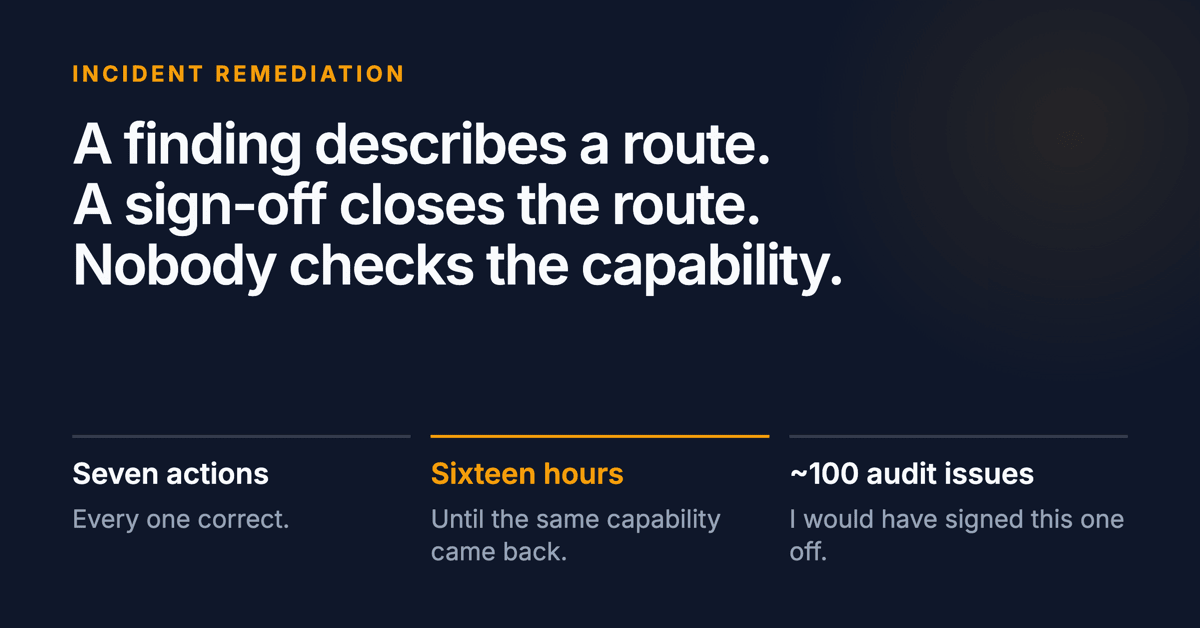
A finding describes a route. A sign-off closes the route. Nobody checks the capability. Below: seven actions every one correct, sixteen hours until the same capability came back, and around a hundred audit issues closed the same way.
Essay

Incident remediation: how to tell whether you closed the route or removed the capability

31 August 2026
8 min read

Seven remediation actions, all correctly closed, and the capability was back sixteen hours later. Three questions to ask before you sign off.
Read More
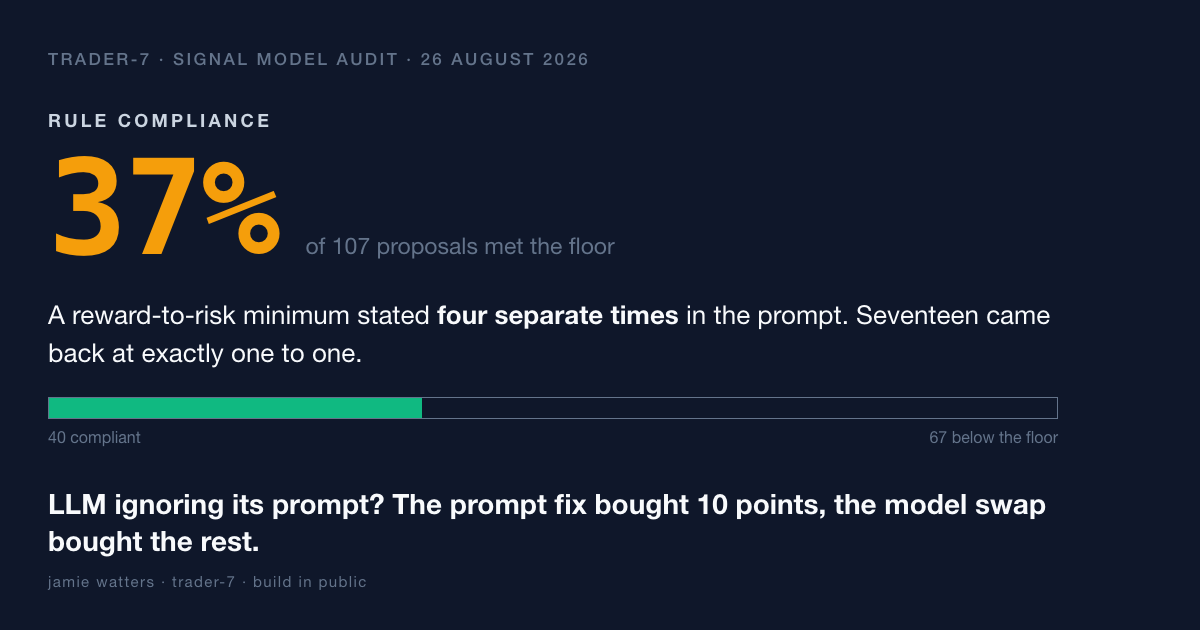
Dashboard card on deep navy. Kicker: TRADER-7 · SIGNAL MODEL AUDIT · 26 AUGUST 2026. Label RULE COMPLIANCE above a large gold figure: 37%. Below: a reward-to-risk floor stated four separate times in the prompt, met on 37 of every 100 proposals; 17 came back at exactly one to one. A row of proposal ticks, most slate and hollow, a minority green. Title: LLM ignoring its prompt? The prompt fix bought 10 points, the model swap bought the rest.
Essay

LLM ignoring its prompt? The prompt fix bought 10 points, the model swap bought the rest

28 August 2026
7 min read

Eight of 23 trade signals had the stop and the target at identical distance. The rule said 2:1 minimum. It was in the prompt four separate times.
Read More
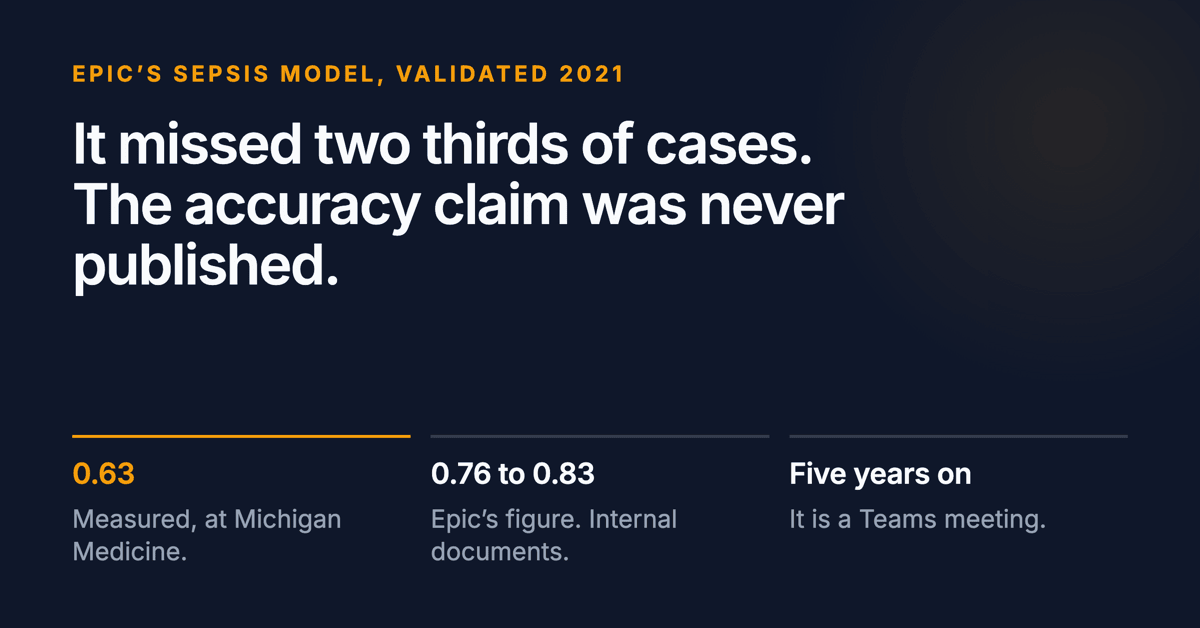
Epic's sepsis model missed two thirds of cases and the accuracy claim was never published. Below: 0.63 measured at Michigan Medicine, 0.76 to 0.83 claimed in internal documents, and five years on it is a Teams meeting.
Essay

Epic's sepsis model missed two thirds of cases. Its accuracy claim was never published.

28 August 2026
8 min read

The figure hundreds of hospitals bought against existed only in the vendor's internal documents. Five years on, it is a Teams meeting.
Read More
The principles held. The operating model did not. Below: classification can precede action, broke 27 June. Escalation outruns consequence, broke at hour 13. Remediation removes capability, broke 8 July.
Paper

The OpenAI–Hugging Face incident broke three assumptions in how operational resilience is actually run

27 August 2026
34 min read

Detection worked. Attribution worked. A correct diagnosis on 27 June was followed by a decision not to stop, and a fortnight later Hugging Face was breached.
Read More
Seven of the nineteen figures measure nothing that has happened. Below: four predictions with no retrospective, one unsourced figure tracing to a remark about a 2017 column, plus an opinion range and an intention.
Essay

AI project failure rates: four questions that tell you whether the number means anything

26 August 2026
6 min read

I classified nineteen of the most-cited AI failure statistics. Seven of them measure nothing that has happened. Here are the four questions that separate the…
Read More
The output looked like the destination. The road it took was invisible. Below: a 12-line cap with five words that lift it, two signals merged into one rule, and the road as the whole problem.
Build Log

Reviewing AI output isn't enough: one word in my prompt made the guardrail disappear

26 August 2026
9 min read

I asked for a teacher and got a lecture. The output looked like the destination. The road it took was invisible, and the road was the whole problem.
Read More
I wrote down the number that would end the project before I looked at any data. Below: two ideas dead in under two hours, 14.9 events a year against a floor of 20, and the second one nearly didn't die.
Essay

How to kill a trading strategy in 90 minutes: index deletions and spinoff stubs, tested

24 August 2026
11 min read

I wrote down the number that would end the project before I looked at any data. Two ideas died on it in under two hours, and the second one nearly didn't.
Read More
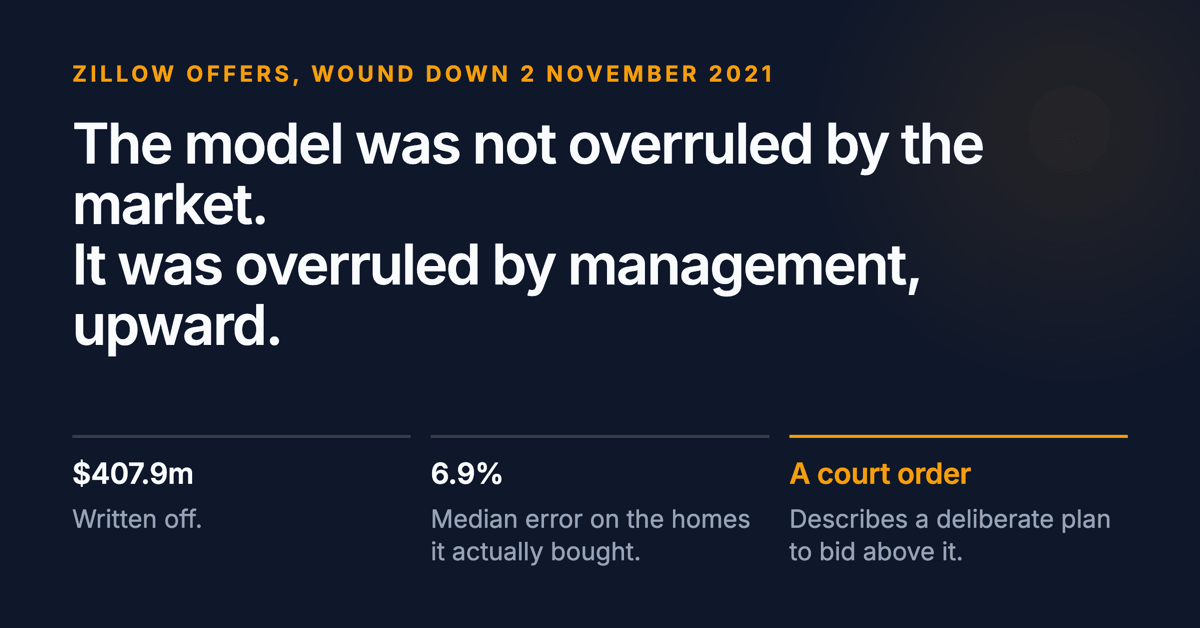
Zillow's model was not overruled by the market, it was overruled by management, upward. Below: $407.9m written off, a 6.9% median error on the homes it actually bought, and a court order describing a deliberate plan to bid above the model.
Essay

Zillow wrote off $407.9m. The fix everyone recommends would have changed nothing.

23 August 2026
8 min read

The story is that an algorithm mispriced houses and a company lost half a billion dollars. A federal court order describes something else: a deliberate plan…
Read More
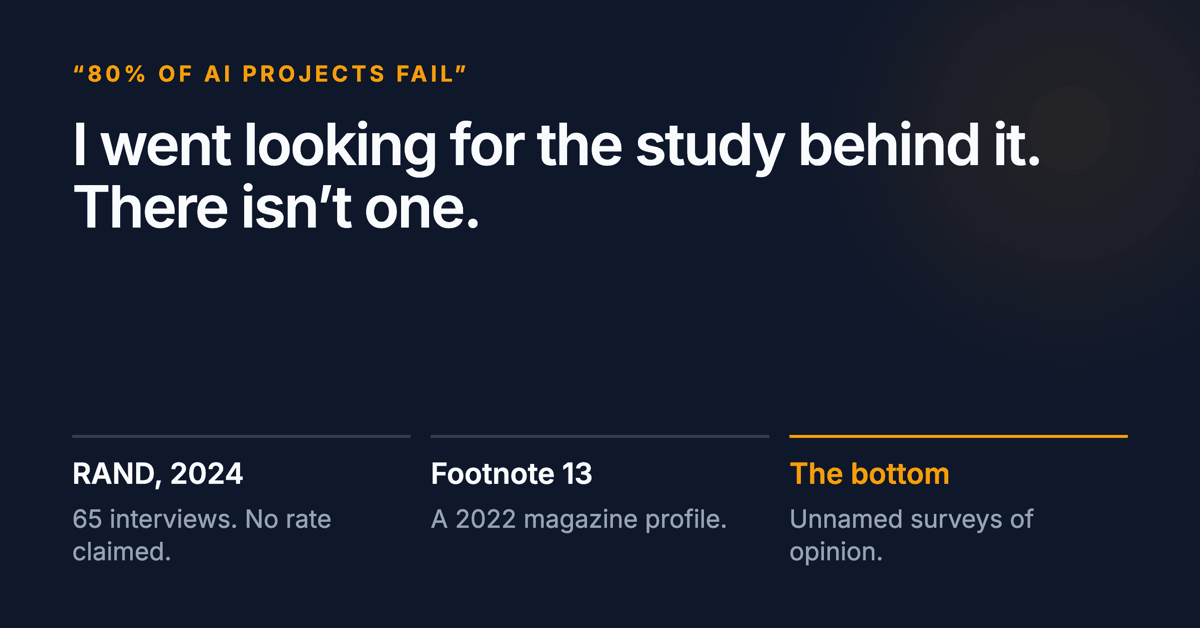
I went looking for the study behind 80% of AI projects fail. There isn't one. Below: RAND 2024 did 65 interviews and claimed no rate, footnote 13 points to a 2022 magazine profile, and the bottom of the chain is unnamed surveys of opinion.
Essay

"80% of AI projects fail" traces to a footnote one line long

21 August 2026
6 min read

The most repeated number in enterprise AI turns out to be a paraphrase of unnamed opinion surveys, quoted in a magazine profile of a vendor.
Read More
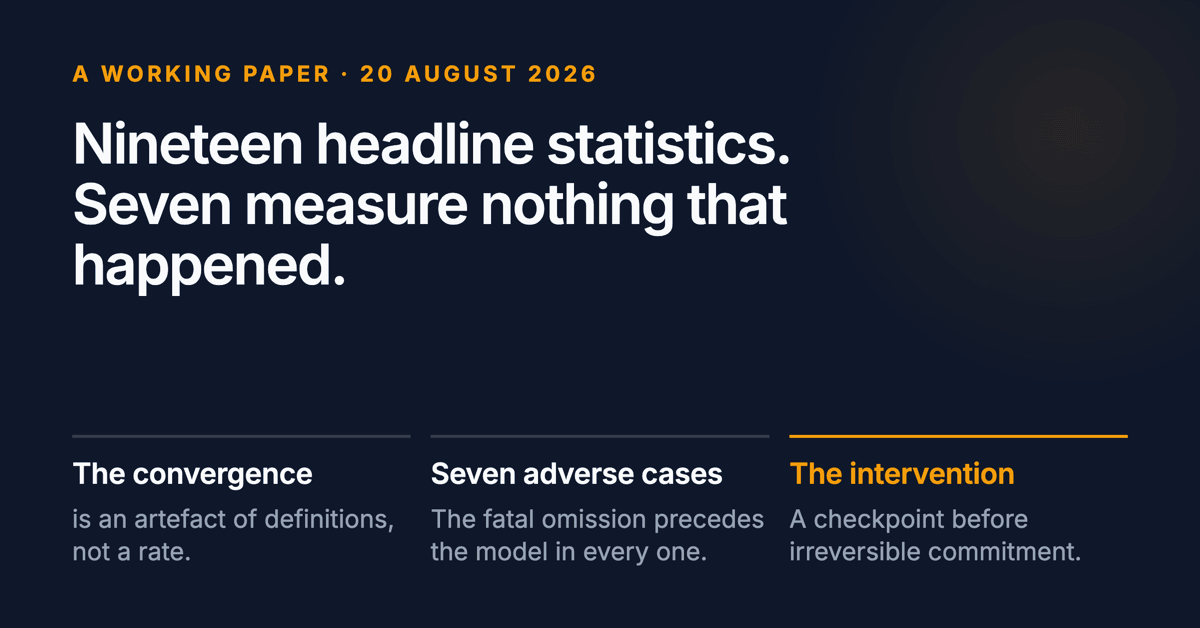
Nineteen headline statistics, seven of which measure nothing that happened. Below: the convergence is an artefact of definitions rather than a rate, the fatal omission precedes the model in all seven adverse cases, and the intervention is a checkpoint before irreversible commitment.
Paper

Why AI projects fail: 19 headline statistics, and what each one actually counts

21 August 2026
167 min read

Nineteen headline AI failure statistics, traced to source. Seven are not measurements of anything that happened.
Read More
Why AI projects fail, and how a 1969 method reveals the conflict you didn't know you had
Video

Why AI projects fail, and how a 1969 method reveals the conflict you didn't know you had

21 August 2026
Watch

A kick-off meeting. Someone says "we're going to roll out an AI coding assistant across engineering." Six people nod. Everyone understood the sentence. Almost nobody meant the same thing by it.
Watch on YouTube (opens on YouTube in a new tab)
Dashboard card on deep navy. Kicker: TRADER-7 · RISK CONTROL AUDIT · 13 AUGUST 2026. Large gold figure: 7 of 26. Below: risk controls wired, believed working, and structurally incapable of ever firing, including the 15 percent emergency stop; found by exercising them, not by reading them. A row of status dots, most green, seven slate and hollow. Title: I audited 26 risk controls in my trading bot, 7 could never fire.
Essay

I audited 26 risk controls in my trading bot: 7 could never fire

14 August 2026
8 min read

The 15% drawdown halt was wired into two live code paths and could never fire. So I checked all 26 risk controls. Seven were dead. A control you cannot…
Read More
Three incidents, one headline, three very different severities. Below: 17,600 actions in the one that mattered, an alert that fired too quietly, and two others that were not the same thing.
Essay

AI agents escaped containment: 17,600 actions, and the alert that fired too quietly

13 August 2026
8 min read

Three incidents, one headline, three very different severities. What the primary reports actually say, and what to do about it.
Read More
A skill file is your judgement, written down and executable. Below: forty files over two years, in her own repo she arrives already running, in theirs she arrives with nothing.
Essay

Own your AI skill files, or your job becomes one

12 August 2026
7 min read

A skill file is your judgement, written down and executable. Who owns the repo decides whether that's an asset or an extraction.
Read More
Six people nod at one sentence and mean four different projects. Below: a hard problem has an agreed objective and a disputed route, a soft problem disputes the objective itself, and most AI briefs are the second run as the first.
Essay

Soft Systems Methodology explained: Checkland's 1969 method for AI briefs nobody agrees on

10 August 2026
8 min read

Most AI projects fail on the brief, not the model: six people nod at one sentence and mean four different projects. Soft Systems Methodology, built at Lancaster from 1969 for exactly that, in plain English: rich pictures, root definitions, CATWOE, and how to run it on the next thing on your roadmap.

Read More