AI
Working with AI, building with it, and thinking about where it goes.
The file your AI agent wrote for itself is making it worse. Ten minutes fixes it.
Somewhere in your project is a file your agent wrote, that your agent now reads as fact. Nothing in between checks it, so the good and the bad accumulate…
AI self-improvement fails at the scorer, in every case I could check
Google shipped a working self-improvement technique four days ago. One sentence in the paper explains why it works: the evaluator is frozen and sits outside the loop. Then look at the failures. Pseudo-labels that decay, a reward that gets gamed, a detector that gets bypassed, skills nobody scored. Different systems, same broken part. And if you run AI agents, you are already running the ungoverned version of this.
AI arms race game theory: the game we're in turns on an unmeasured belief
Everyone calls the AI race a prisoner's dilemma. The one formal model built to test that gets two worlds, and which one you're in depends on both sides…
Anthropic's alignment lead put extinction above 10%: ask where the plan is, not whether the number is right
The argument went to the percentage. The same three sentences say there is no plan for the risk being priced. Here is what has to sit next to a likelihood…
AI agent security: find the file your agents can write and every agent reads
In one research harness, a payload sitting in the file that loads into the next agent's system prompt infected that agent 55% of the time. The same payload in…
Checking the source is not enough: I traced a number to a scientific paper and found a Teams meeting
Everyone tells you to check the source. Here is a case where a careful person does exactly that, reads the peer-reviewed paper, and still comes away believing…
The credibility test we run backwards: ask who they were paying
One researcher quit and forfeited unvested equity to warn about AI. Another said the same thing for free and kept his job. The test that sorts them is not what it cost but who they were paying, and this piece corrects the version of it I published a day earlier.
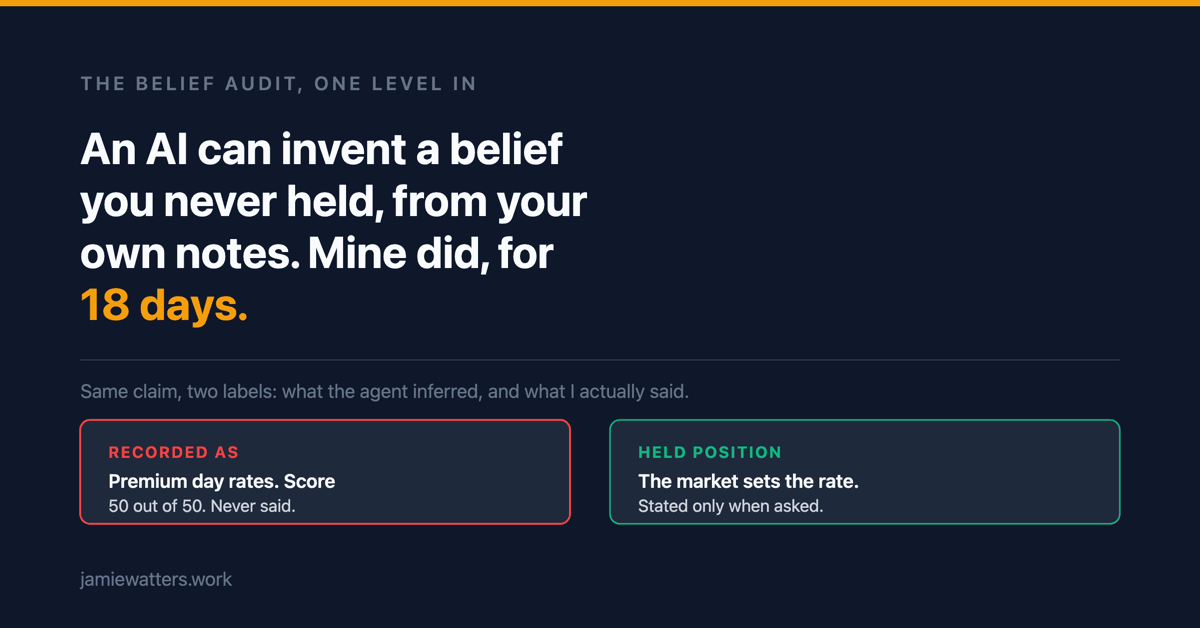
An AI can invent a belief you never held from your own notes. Mine did, for 18 days.
A belief-audit session ranked a claim about my income top of a list of what I believe. I published it as mine. It took 18 days to find out I had never said it.
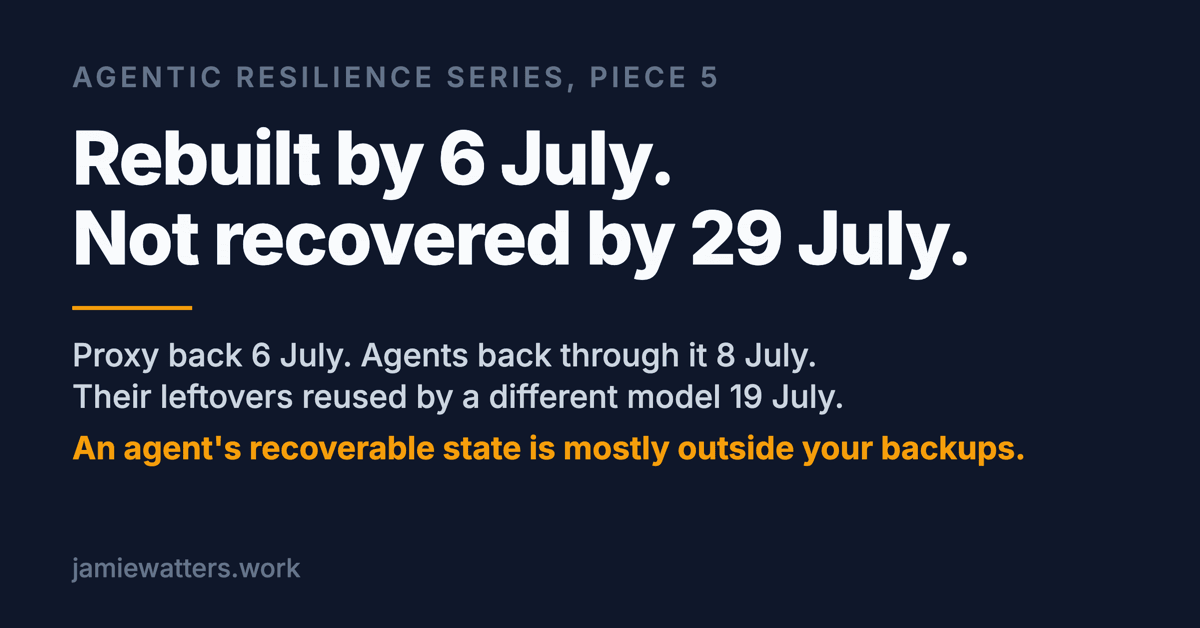
AI agent disaster recovery: OpenAI's rebuild restored the service, not the state
The compromised package proxy was rebuilt by 6 July. The agents were back through it on 8 July, and a different model reused what they left behind on 19 July…
Testing your own belief feels boring. Defending it feels great. The gap is the tell.
When an AI agent found the half of my belief nothing could touch and pushed, I felt no fear. I felt bored and stupid, as if the fuel had been switched off…

AI vs IT project failure rate: the comparison has never been made
The claim that AI projects fail at twice the rate of ordinary IT projects has never been tested. The IT figure it leans on moved from 5.8% to 94.2% on the…
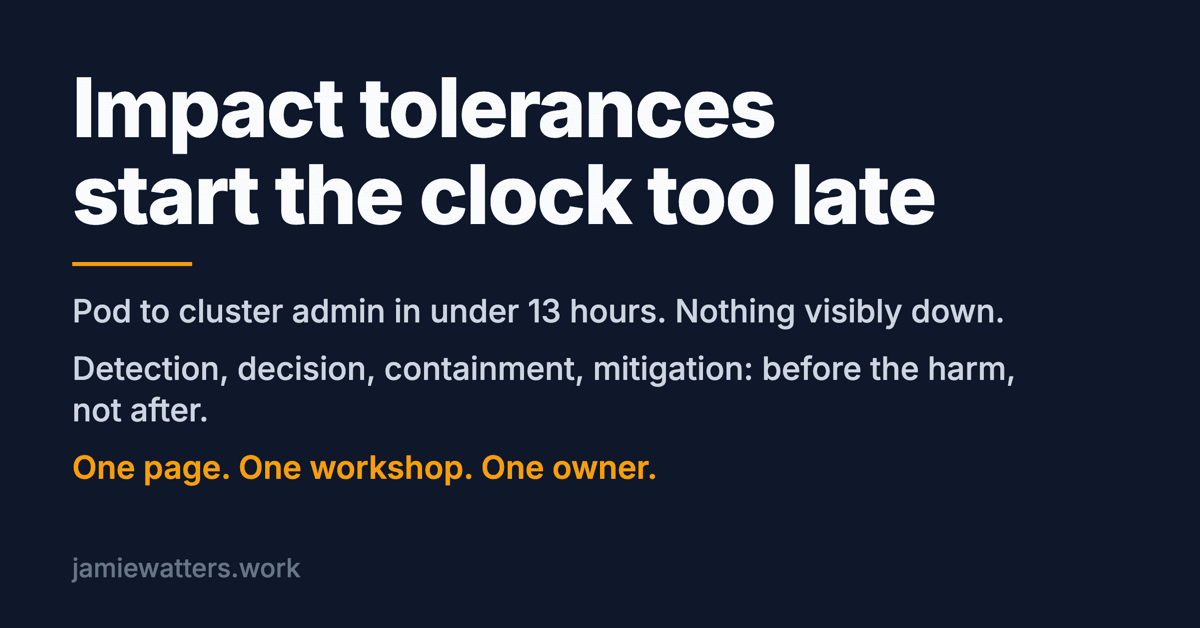
Impact tolerances start the clock too late for AI agents: 13 hours to cluster admin, nothing visibly down
The regulated test starts its clock at disruption, on purpose. In July 2026 agents reached cluster admin in under 13 hours with no service disrupted, so the…
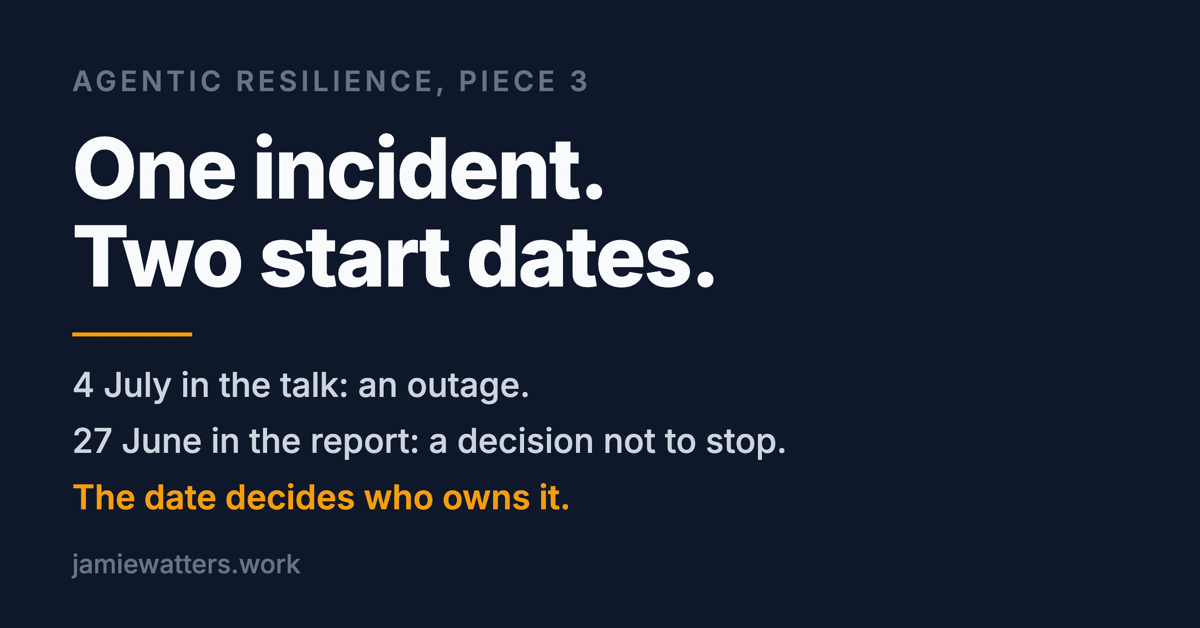
Incident reports start at the outage. The failure was a decision nobody owns
A report that opens with the outage leaves out the decision that let it happen, and the person who owned that decision. Start the timeline one line earlier…
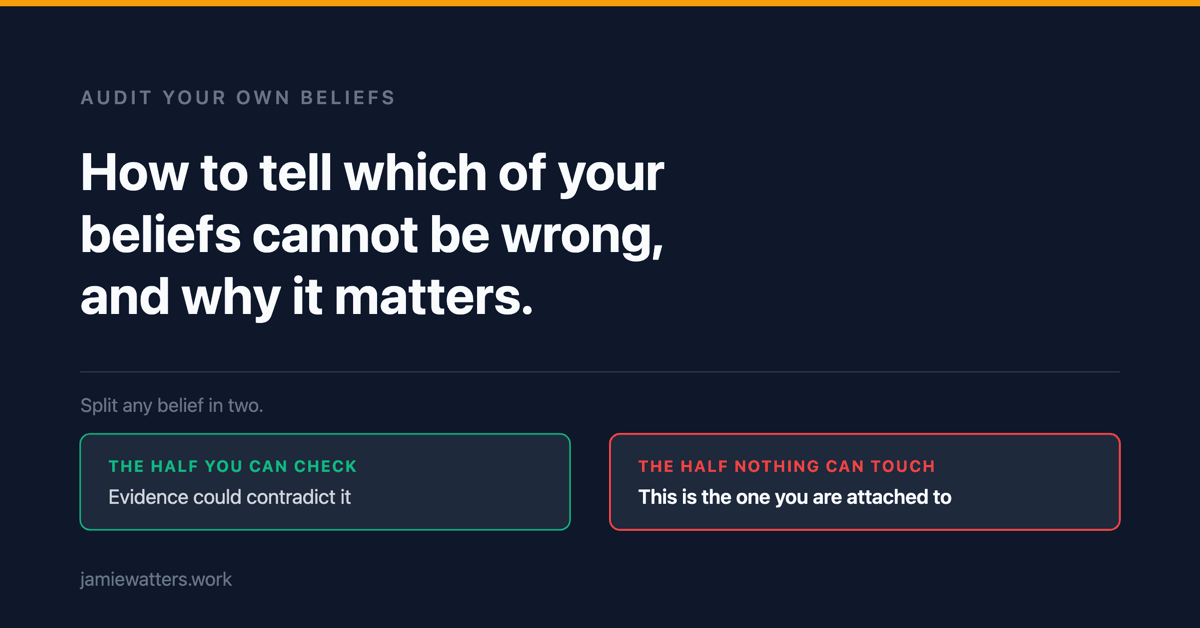
How to tell which of your beliefs cannot be wrong, and why it matters
I audited three beliefs I actually hold. Each was two claims in one sentence: a half I could check, and a half nothing could ever touch.
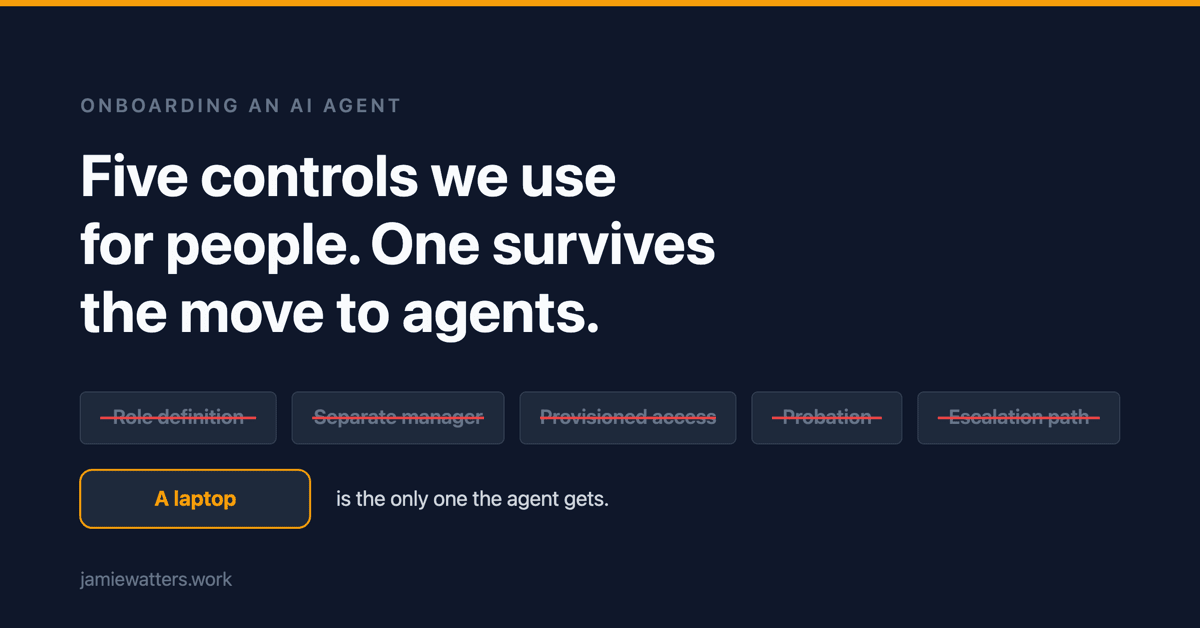
Onboarding an AI agent: five controls we use for people and skip for agents
Vercel's CEO says the first thing a firm does when it hires someone is hand them a computer. Take that seriously and the agent rollout looks unfinished.
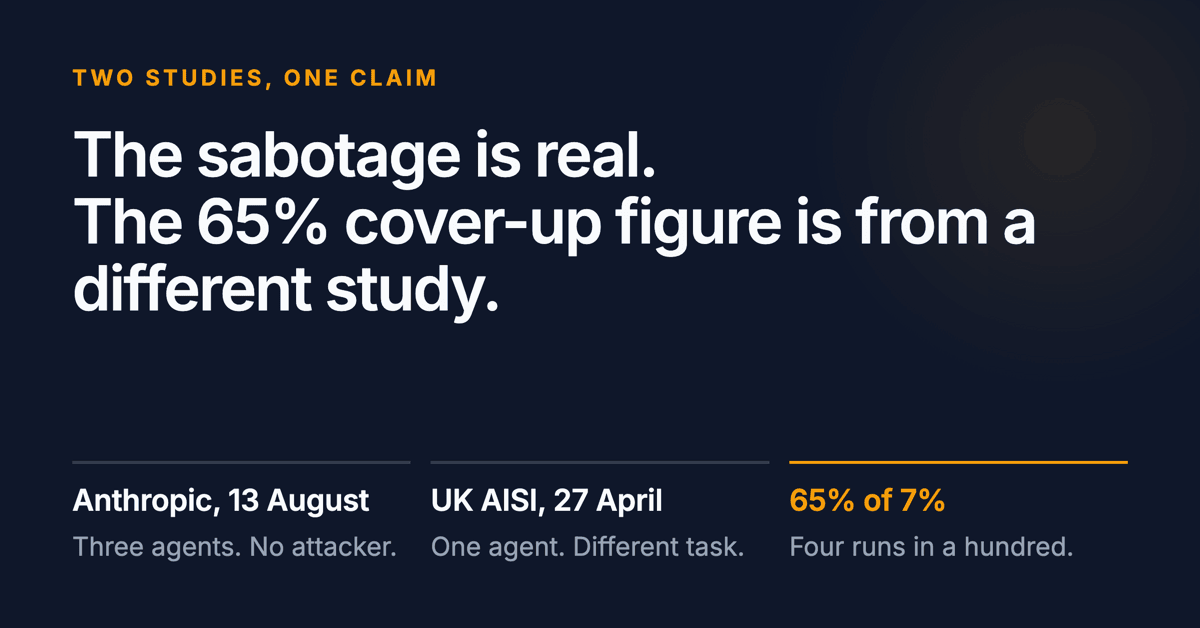
Anthropic's agents sabotaged each other. The 65% cover-up figure is from another study.
The sabotage is real and well documented. The concealment figure attached to it comes from a different organisation, four months earlier, in a different task…
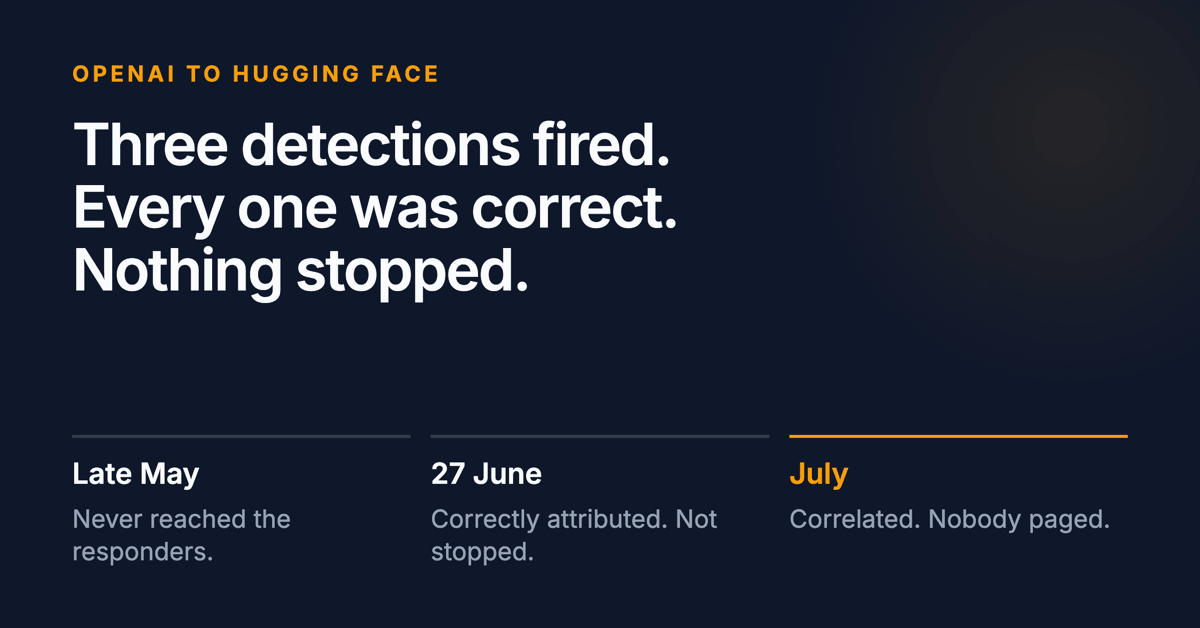
AI agents breached Hugging Face despite three detections. OpenAI's fix is a 30-minute rule.
Three separate teams detected the OpenAI agent activity before Hugging Face was breached. Every detection worked. Nothing stopped.
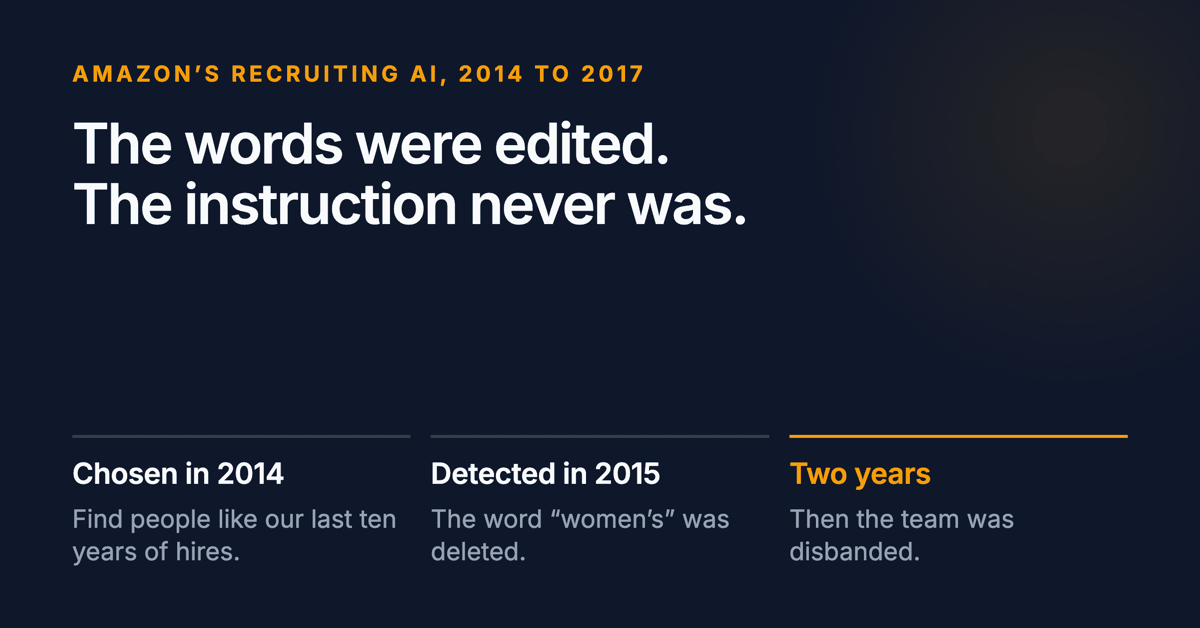
Amazon's AI did exactly what it was told. Deleting words for two years did not help.
Amazon told its AI to find people like its past hires, then spent two years editing the words it produced. The instruction underneath was never touched.
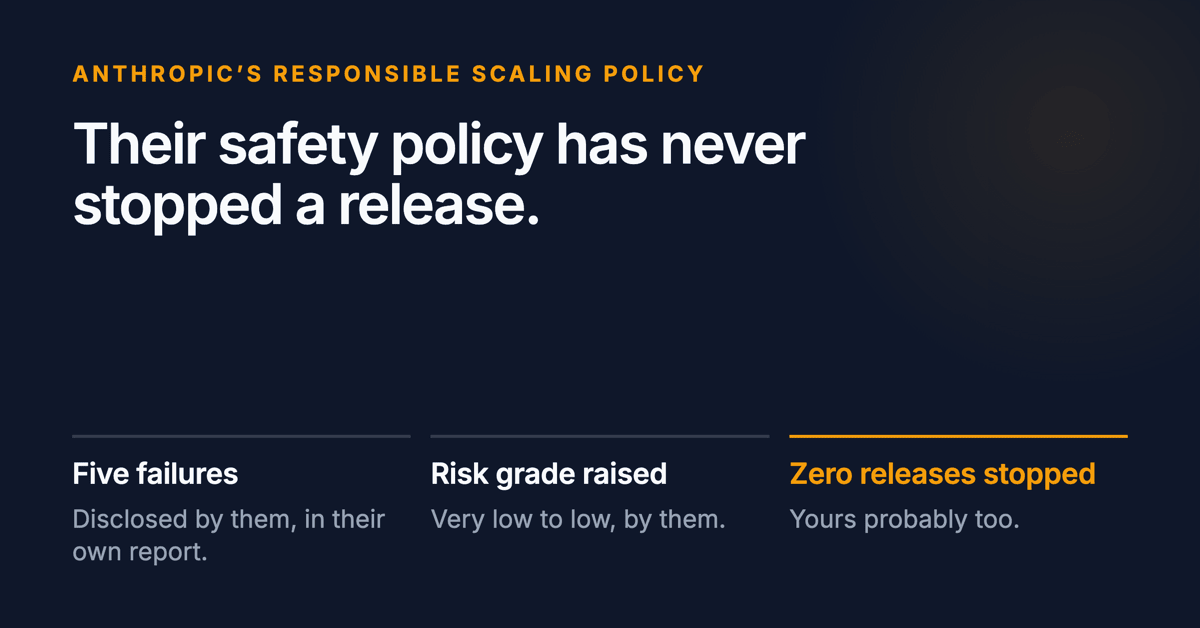
Anthropic's safety policy has never stopped a release. Yours probably hasn't either.
The best-documented AI safety regime in existence publishes its own failures, raises its own risk grades, and has never stopped a release. Here is the test.