
The Journey

Most posts here are ad hoc: what I learned building with AI that week, some philosophy, a writing lesson, something I came across.

Subscribe via RSS
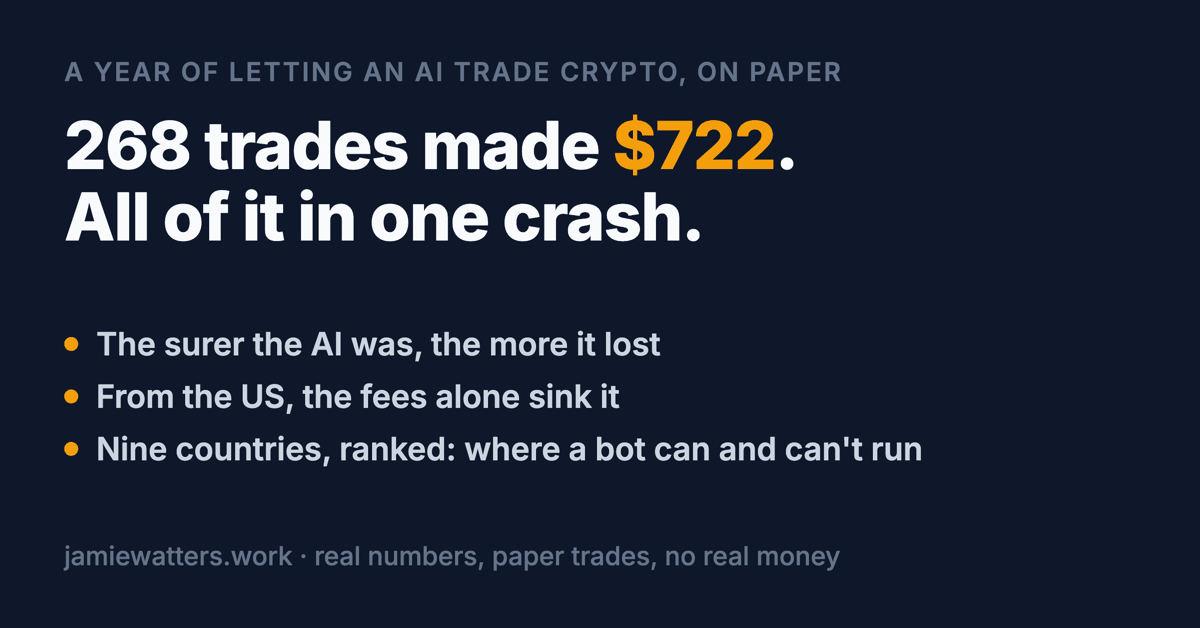
Dark card reading: a year of AI crypto trades made $722, all of it in one crash. Three lines beneath: its confidence ran backwards; US fees alone would sink it; where it can and cannot be run.
Build Log

Thinking of buying a crypto trading bot? One year, 268 trades and $722 of profit say read this first

10 October 2026
11 min read

A year of an AI picking crypto trades, 268 of them on paper, made $722 and all of it in one crash. Fees, the exchange you can legally use and the country you live in decided more than the strategy. The five numbers to get before you build or buy a bot, and where it can't be run.
Read More
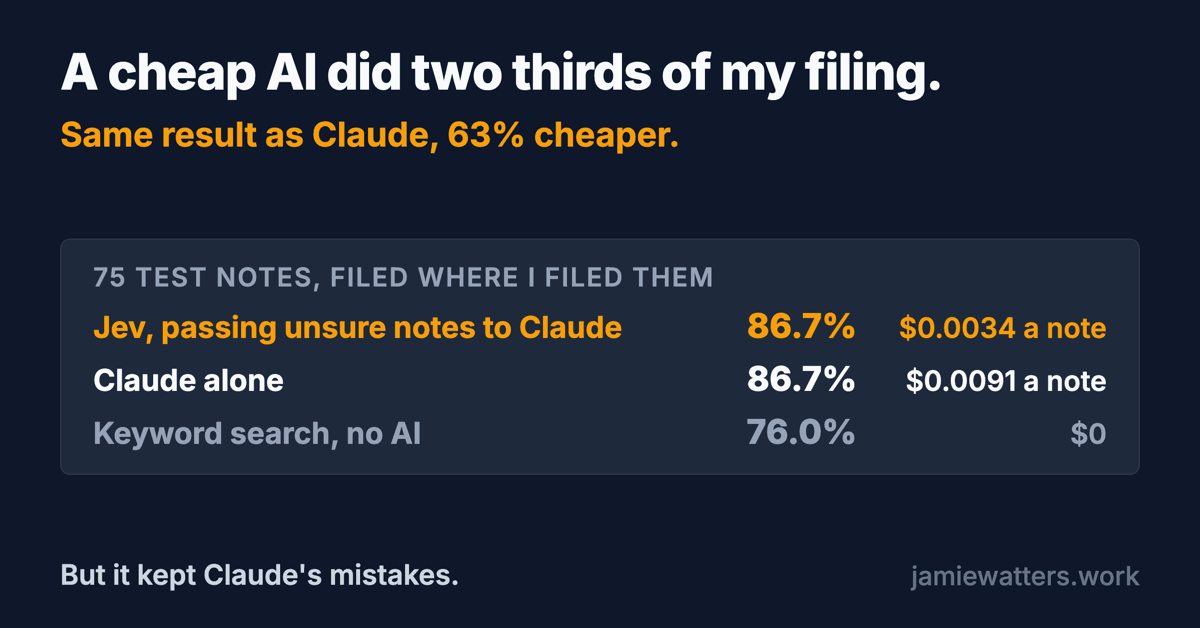
A card reading: A cheap AI did two thirds of my filing. Same result as Claude, 63% cheaper. Jev passing unsure notes to Claude 86.7% at $0.0034 a note; Claude alone 86.7% at $0.0091 a note; keyword search with no AI 76.0%. But it kept Claude's mistakes.
Build Log

Jev, a cheap AI, did two thirds of my filing: same result as Claude, 63% cheaper

23 September 2026
12 min read

Jev, a cheap AI, handled two thirds of my filing and passed the rest to Claude. Same result as Claude alone, 63% cheaper. The catch: the hand-off isn't a check, because Claude makes the same mistakes.
Read More
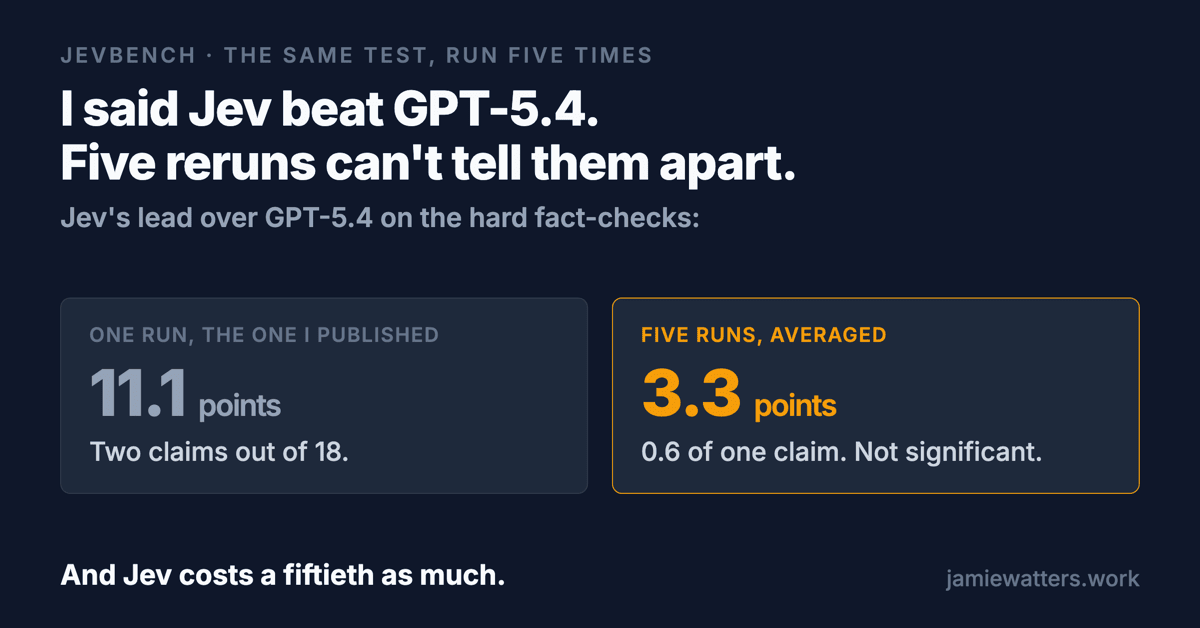
A results card reading: I said Jev beat GPT-5.4, five reruns can't tell them apart. Jev's lead over GPT-5.4 on the hard claims was 11.1 points in one run and 3.3 points averaged over five runs, which is 0.6 of one claim and not significant.
Build Log

I said Jev beat GPT-5.4. Five reruns can't tell them apart, at a fiftieth of the cost.

23 September 2026
13 min read

I published that Jev, TypeSafe's new model, beat GPT-5.4 by 11.1 points on hard fact-checks. Rerun five times, the two can't be told apart, Jev costs a fiftieth as much, and it lets more wrong claims through. Plus the five-run check.
Read More
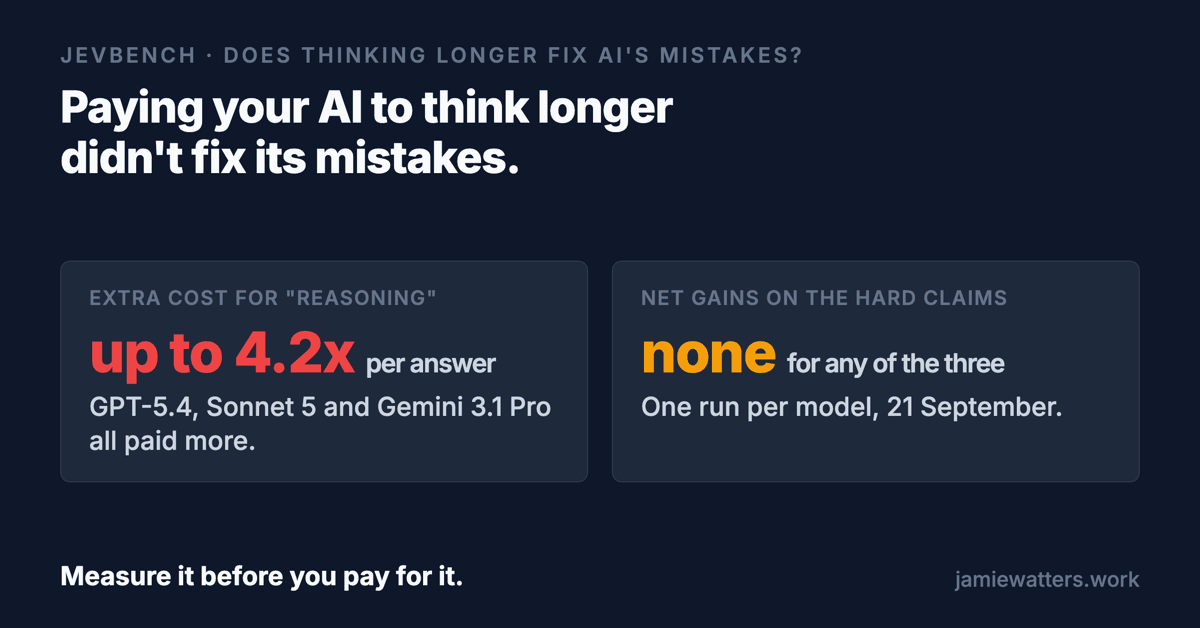
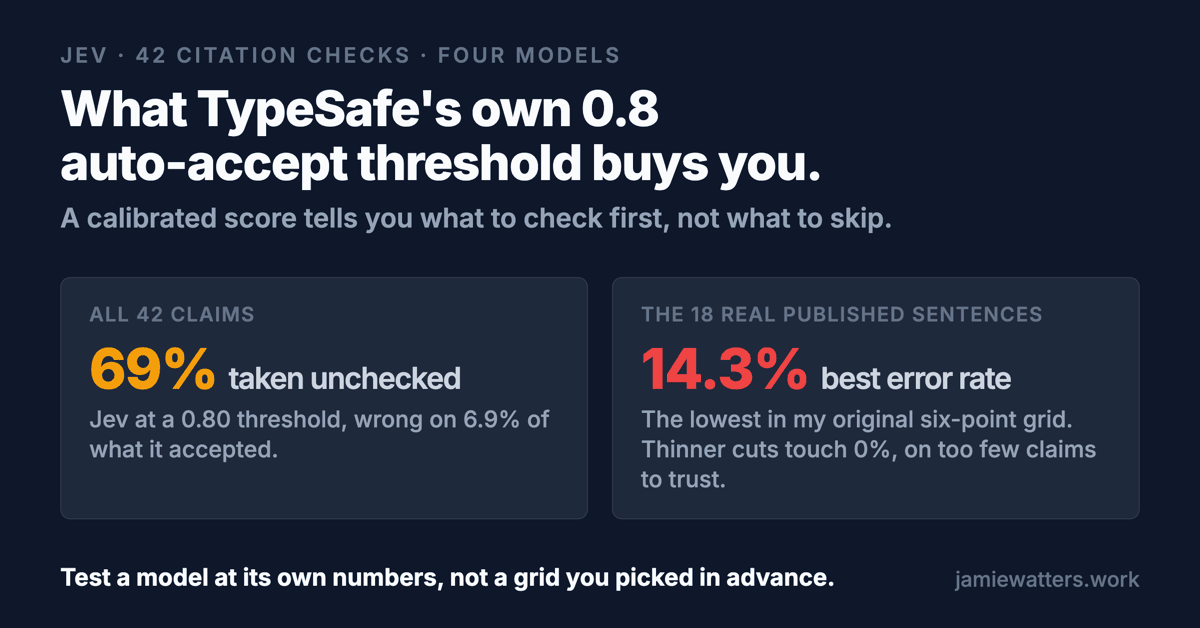
A results card reading: paying your AI to think longer didn't fix its mistakes. Up to 4.2x extra cost per answer for GPT-5.4, Sonnet 5 and Gemini 3.1 Pro, and no net gain on the hard claims for any of the three, one run per model.
Build Log

Paying your AI to think longer didn't fix its mistakes. It cost up to 4.2x more.

23 September 2026
14 min read

I gave three AI models room to think before answering, the fix everyone assumes will work. None got more reliable. It cost 2.4 to 4.2 times more per answer to find that out, and Jev, the cheap specialist model, still caught more of the mistakes.
Read More
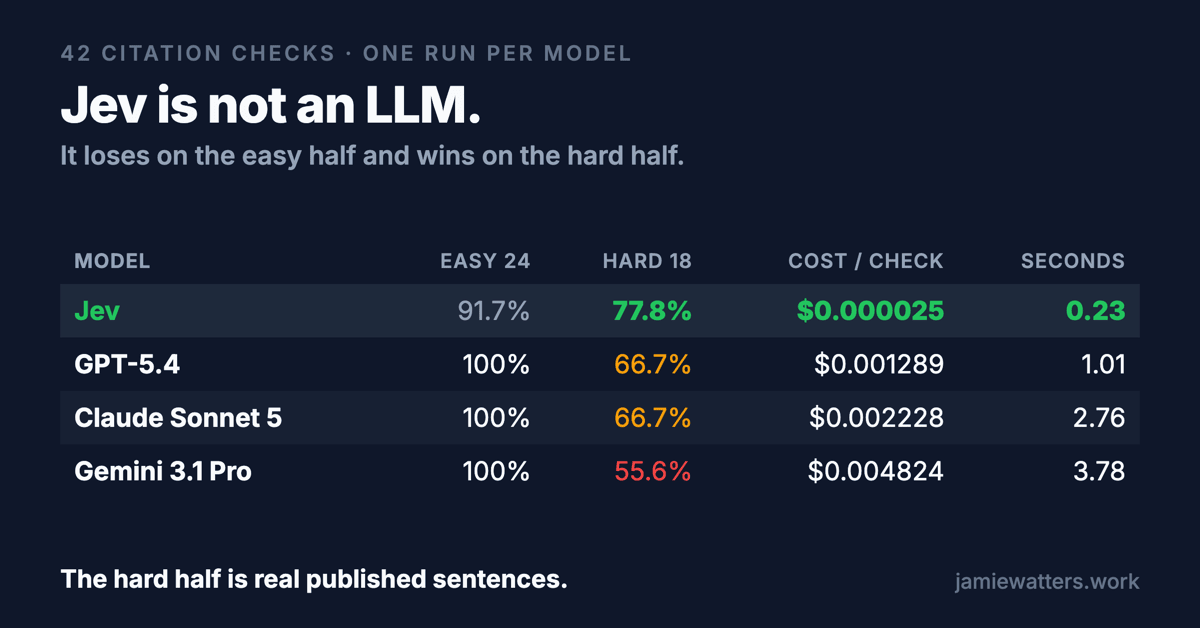
A card reading: what TypeSafe's own 0.8 auto-accept threshold buys you, and that a model's confidence threshold has to be tested at its own numbers, not a grid chosen in advance
Build Log

GPT-5.4 beats Jev on a confidence threshold, once tested at its own values.

21 September 2026
26 min read

I published a wrong finding last week: that GPT-5.4's confidence score has no usable threshold. It does, and swept over its own values it beats Jev at every…
Read More
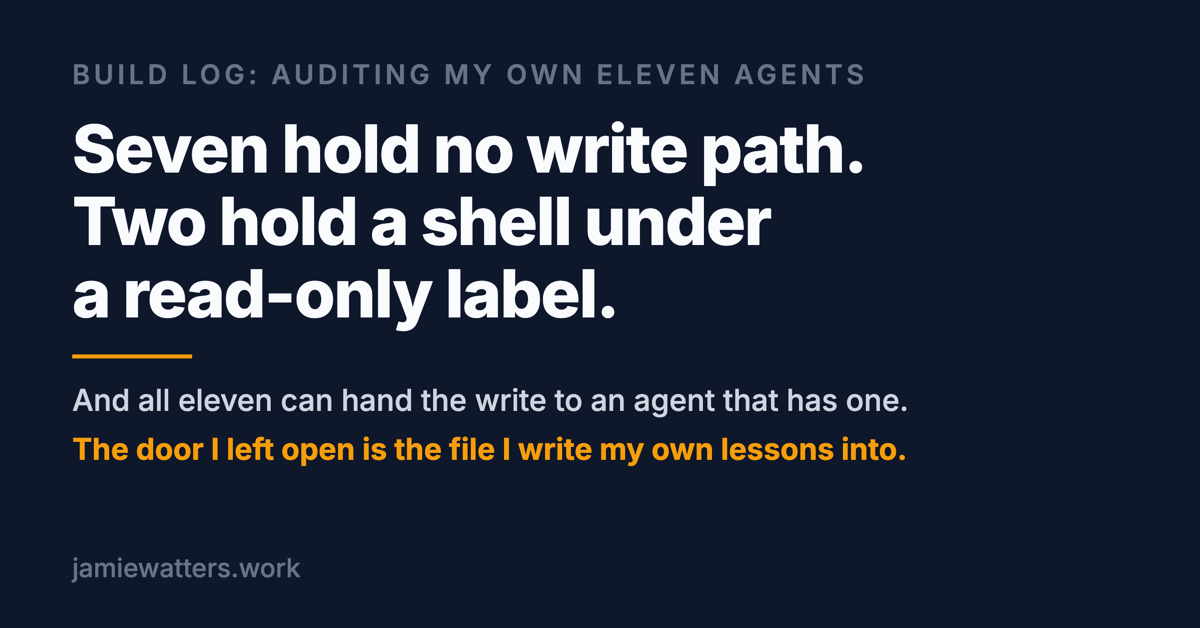
A results table comparing Jev with GPT-5.4, Claude Sonnet 5 and Gemini 3.1 Pro across 42 citation checks, split into an easy set and a hard set
Build Log

Jev is not an LLM. On the hard half it beat GPT-5.4, Gemini 3.1 Pro and Sonnet 5, at a fiftieth of the cost.

20 September 2026
18 min read

Jev does not generate text. You give it a question with defined answers and it hands back one of them plus a probability. On 42 citation checks it tied the…
Read More
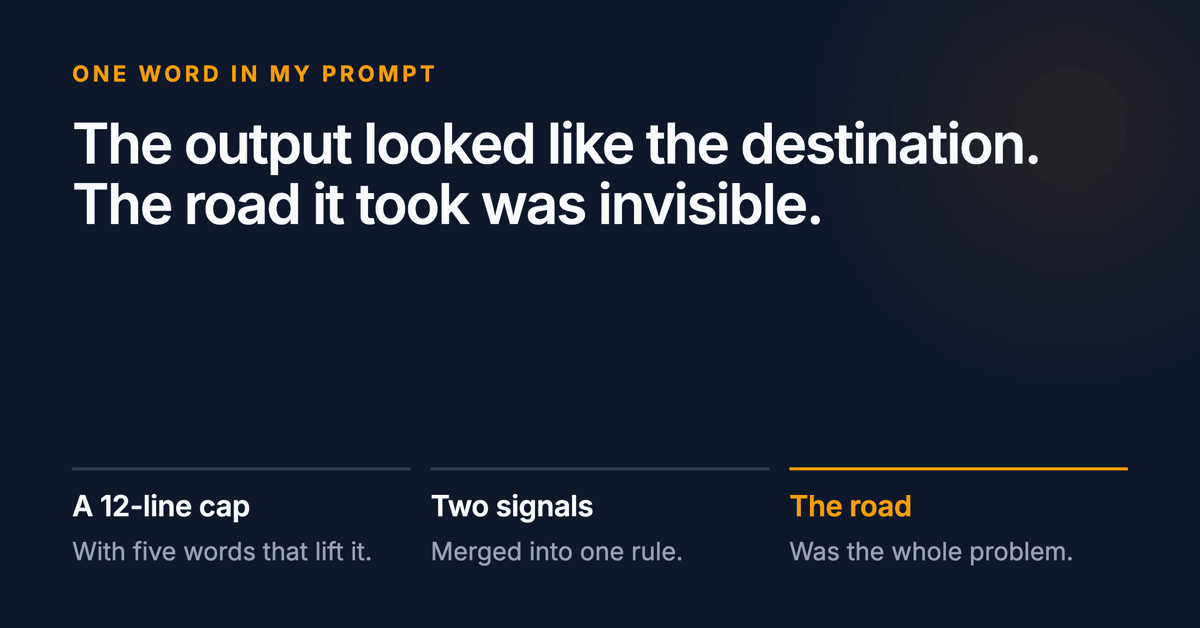
Social card reading: seven hold no write path, two hold a shell under a read-only label, and all eleven can hand the write to an agent that has one. The door I left open is the file I write my own lessons into.
Build Log

AI agent security: find the file your agents can write and every agent reads

15 September 2026
16 min read

In one research harness, a payload sitting in the file that loads into the next agent's system prompt infected that agent 55% of the time. The same payload in…
Read More
The output looked like the destination. The road it took was invisible. Below: a 12-line cap with five words that lift it, two signals merged into one rule, and the road as the whole problem.
Build Log

Reviewing AI output isn't enough: one word in my prompt made the guardrail disappear

26 August 2026
9 min read

I asked for a teacher and got a lecture. The output looked like the destination. The road it took was invisible, and the road was the whole problem.
Read More
My auth check said healthy for three weeks on a dead credential. Below: the check ran and passed every time, the oracle was answering the wrong question, and the pattern costs more than the bug did.
Build Log

Why AI checks fail silently: 1,278 restarts behind a healthy status

3 August 2026
8 min read

My auth check said healthy for three weeks on a dead credential. The pattern behind it costs more than the bug did.
Read More
Anthropic cut 80% of the prompt and I cut my instructions by 90%. Below: one stale copy telling twenty repos they were a different project, two files no session has ever read, and 453 lines loaded twice.
Build Log

Anthropic cut 80% of Claude Code's prompt. I cut my CLAUDE.md by 90% the same day.

3 August 2026
6 min read

An audit of 116 instruction files found one stale copy telling twenty repos they were a different project, two files no session has ever read, and 453 lines loaded twice. Here is what to delete from your own CLAUDE.md, and the method that beats judgement.
Read More
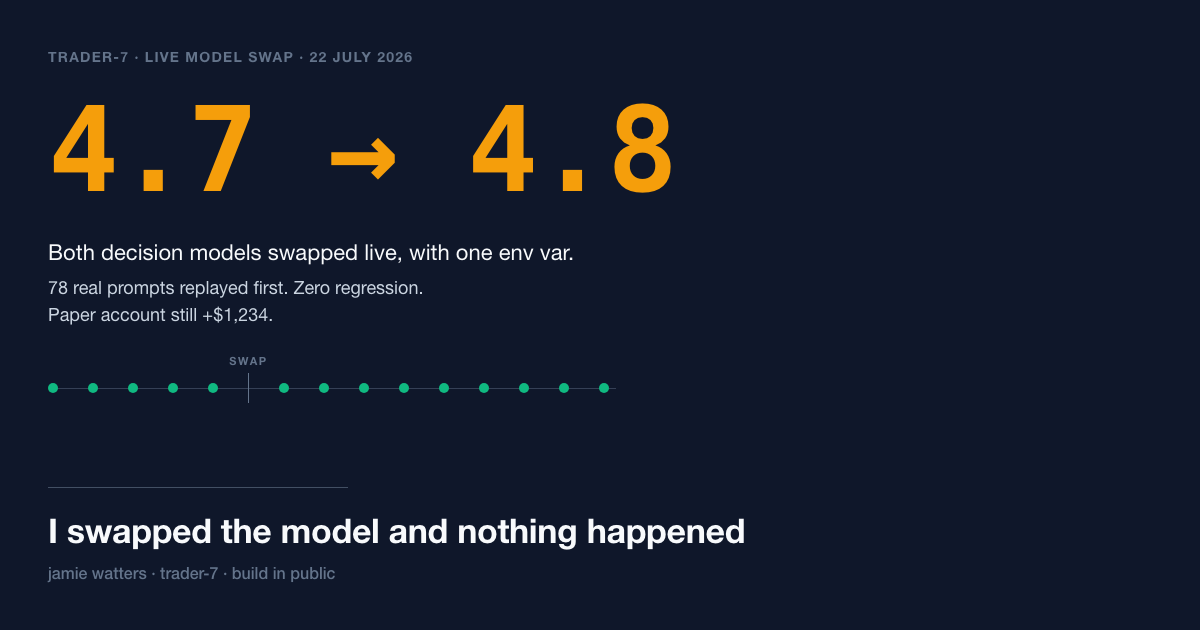
Dashboard card on deep navy. Kicker: TRADER-7 · LIVE MODEL SWAP · 22 July 2026. Large gold figure: 4.7 arrow 4.8. Below: both decision models swapped live with one env var; 78 real prompts replayed first, zero regression, paper account still plus $1,234. A row of even green dots crossed by a thin slate SWAP marker, the dots unbroken on both sides. Title: I swapped the model and nothing happened.
Build Log

I swapped the model and nothing happened

22 July 2026
5 min read

Swapping the two LLMs behind an autonomous trading bot from Opus 4.7 to 4.8, live, without it missing a beat. The trick was replaying 78 real prompts first.
Read More
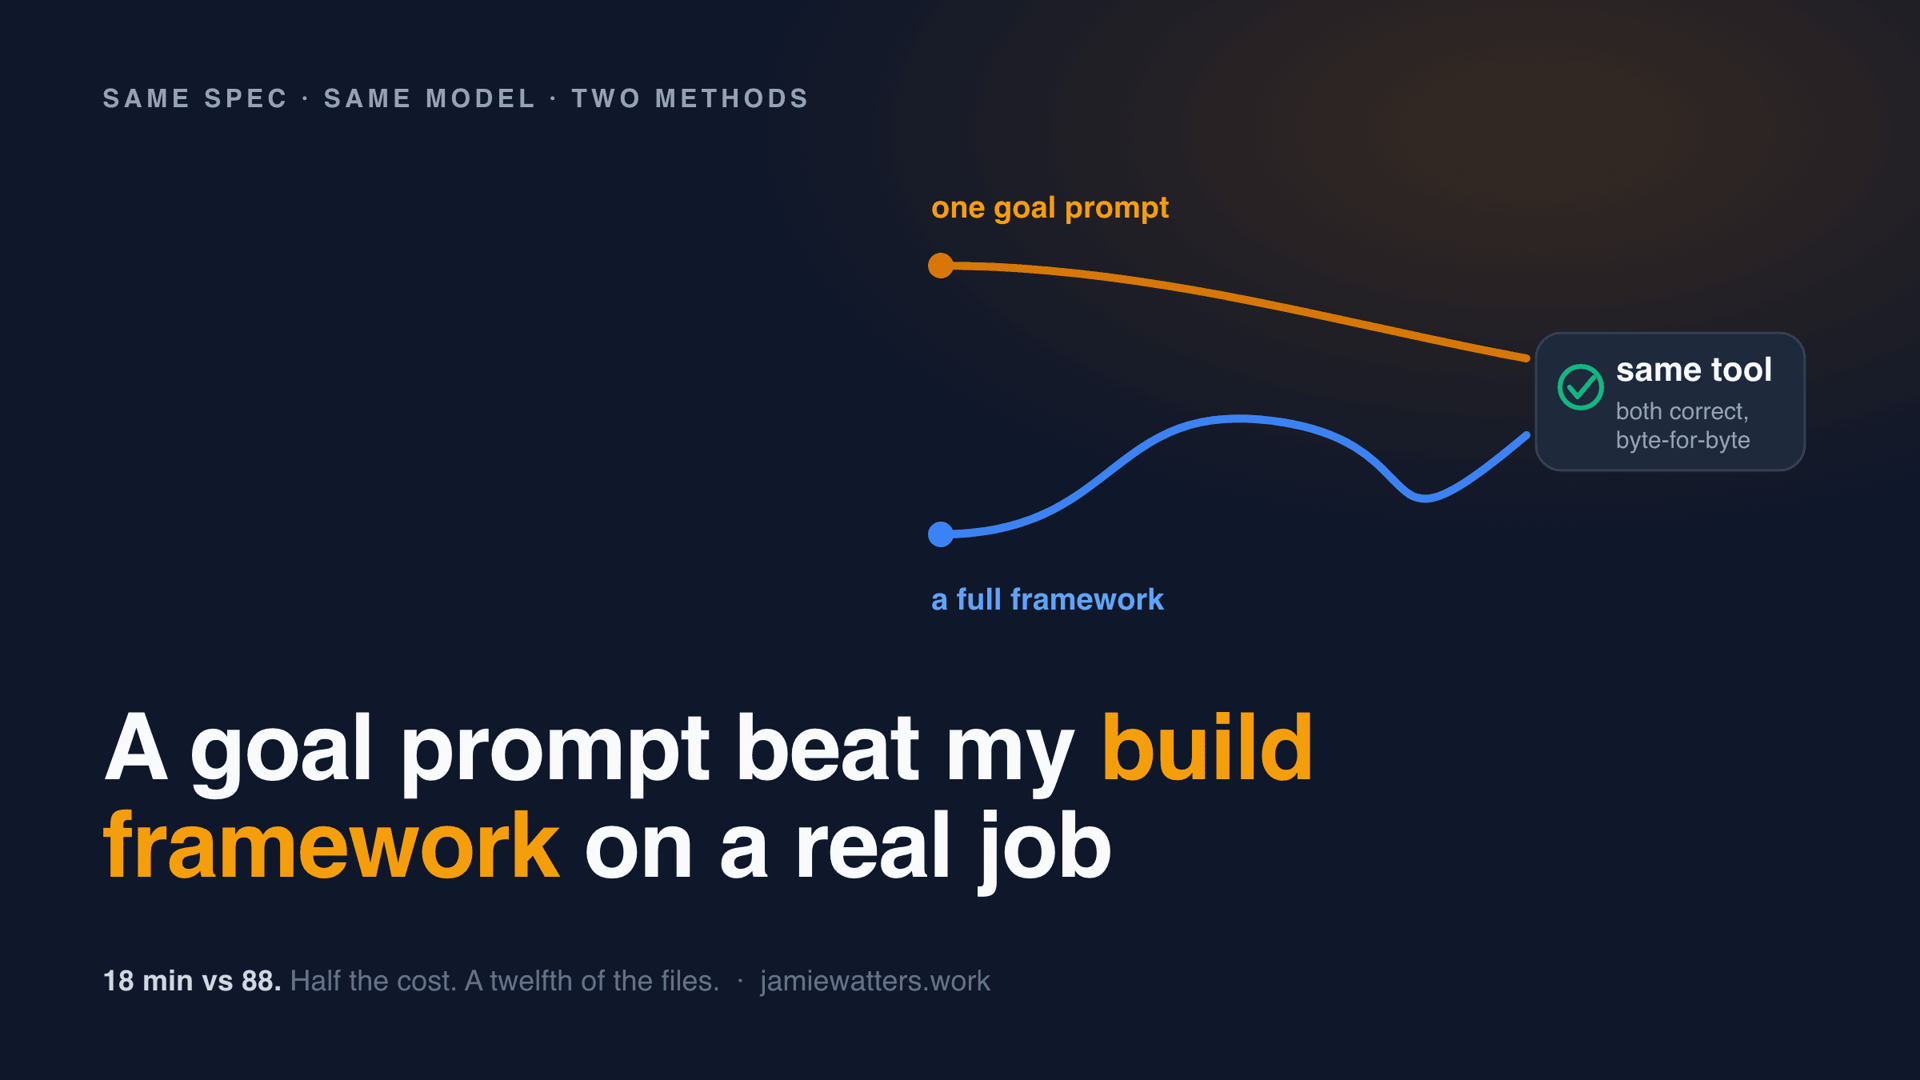
Two workbenches building the same object, one cluttered with scaffolding, one spare, both producing an identical result.
Build Log

I built the same tool two ways to settle an argument

16 July 2026
5 min read

Spec-first or goal-first? I didn't believe either side, so I built the same tool both ways with one spec and one model. Both worked. The bill didn't tie.
Read More
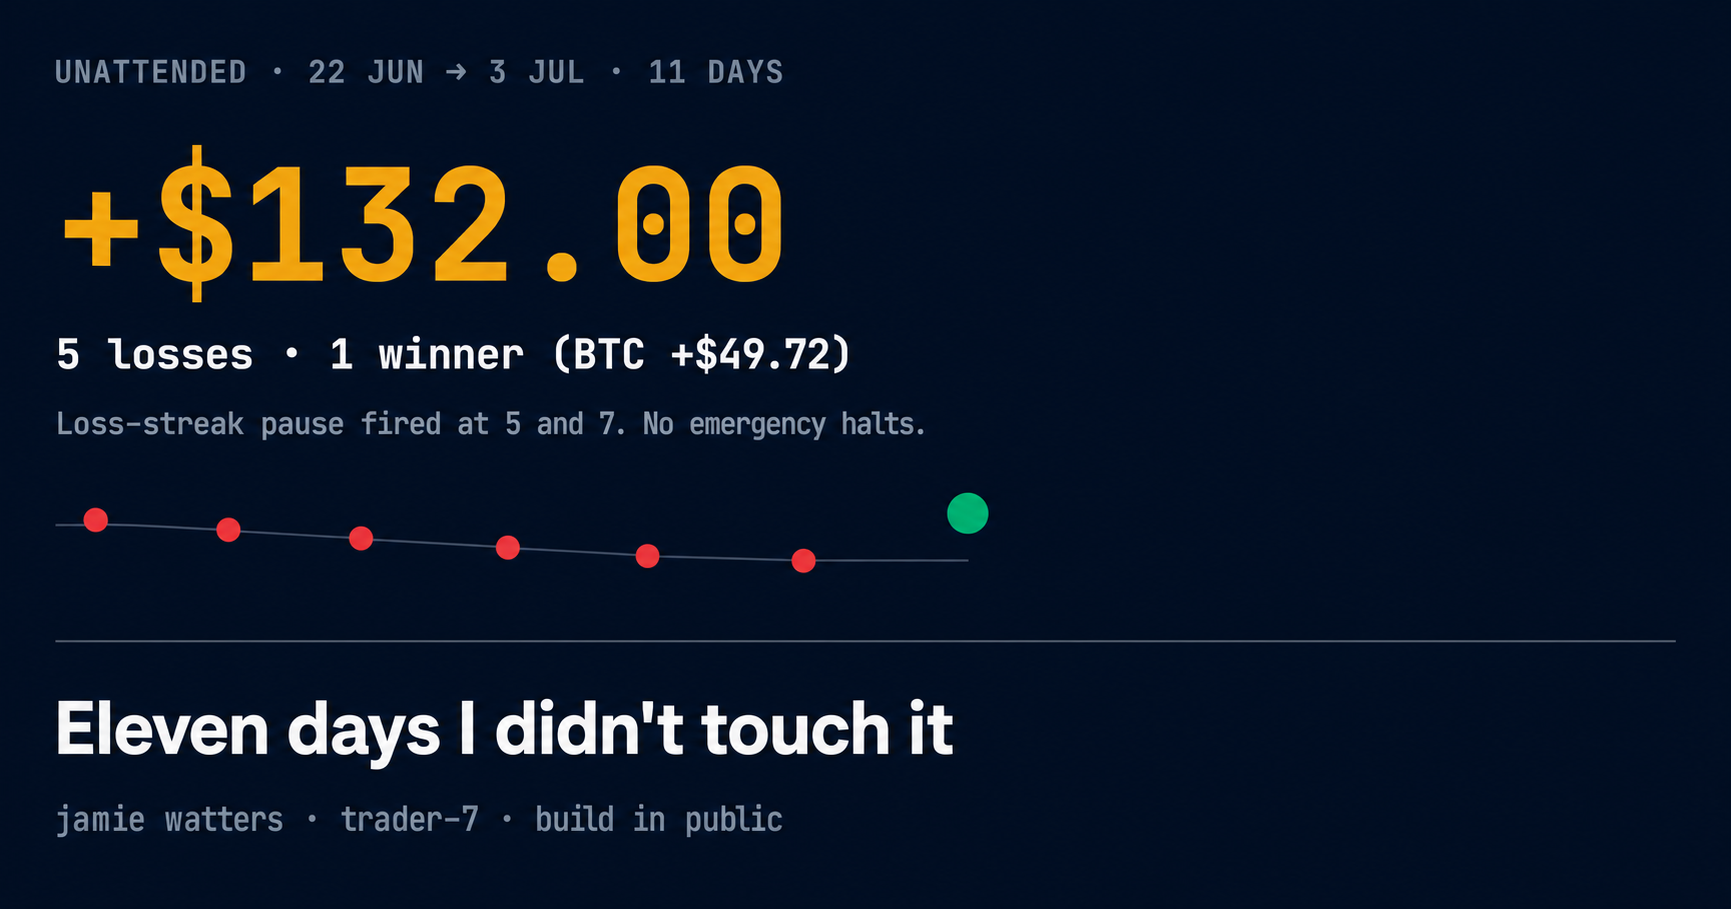
Dashboard card on Deep Space navy background. Kicker: UNATTENDED, 22 JUN to 3 JUL, 11 DAYS. Large gold number: plus $132.00. Below: 5 losses, 1 winner (BTC plus $49.72), loss-streak pause fired at 5 and 7, no emergency halts. Sparkline: five red dots stepping down, one green dot jumping up. Title: Eleven days I didn't touch it.
Build Log

Eleven days I didn't touch it

4 July 2026
5 min read

Eleven days of unattended trading. Five losing trades, one winner covered them, +$132 net. What the system did right, what drifted, what I fixed on return.
Read More
On the left, a lone clamp gripping a single tool; on the right, an organised wall of specialist tools around a small instrument sealed under glass with a wax seal.
Build Log

How to trust AI-written code you didn't read line by line

22 June 2026
5 min read

AI can write working code in minutes. The hard part is trusting it without reading every line. Here's what actually makes AI-built code trustworthy.
Read More
A craftsman's workbench with hand tools and wood shavings beside a brass measuring gauge sealed under a glass dome with a wax seal
Build Log

Everyone's selling autonomous AI agents. I built one, and the real lesson was 20 years old.

21 June 2026
4 min read

An AI agent spent an afternoon optimising one of my apps. It tried a change, measured it, kept the one that was genuinely faster, reverted three that weren...
Read More
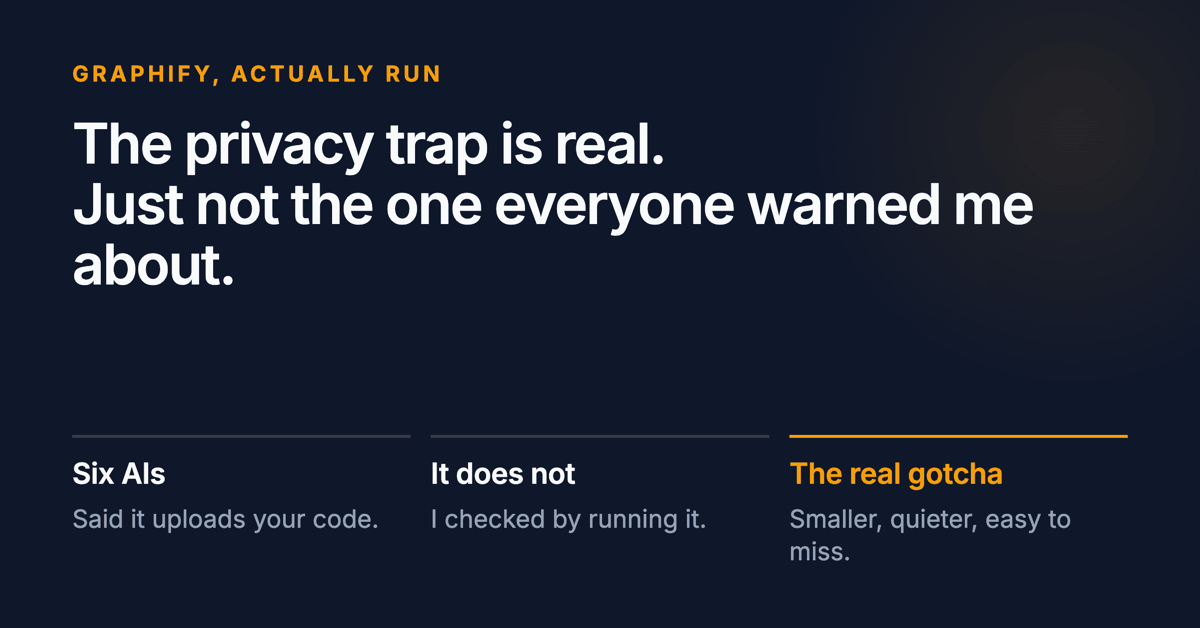
The privacy trap is real, just not the one everyone warned me about. Below: six AIs said it uploads your code, it does not, and the real gotcha is smaller and easy to miss.
Build Log

I Ran Graphify. The Privacy Trap Is Real, Just Not the One Everyone Warned Me About

20 June 2026
7 min read

Six AIs told me Graphify uploads your code. I checked by running it, and the actual gotcha is smaller, quieter, and easy to miss.
Read More
Claude keeps killing the good bit by turning it into a multiple choice. Below: an open question becomes three options, the best answer was usually the fourth, and once you see why you can stop it.
Build Log

The Three Options Trap: Why Claude Keeps Killing the Good Bit

18 June 2026
7 min read

Claude has a habit of collapsing an open conversation into three multiple-choice options, and once you see why it does it, you can stop it doing it to you.
Read More
Six AIs handed me the same lie, in unison. Below: unanimous reads as corroboration, but it was one claim repeated, so I check the source before I publish.
Build Log

I Almost Told You a Lie. Six AIs Handed It to Me, in Unison.

17 June 2026
7 min read

A field note from researching Graphify: the real privacy model, the honest token numbers, and why I check the source before I publish.
Read More
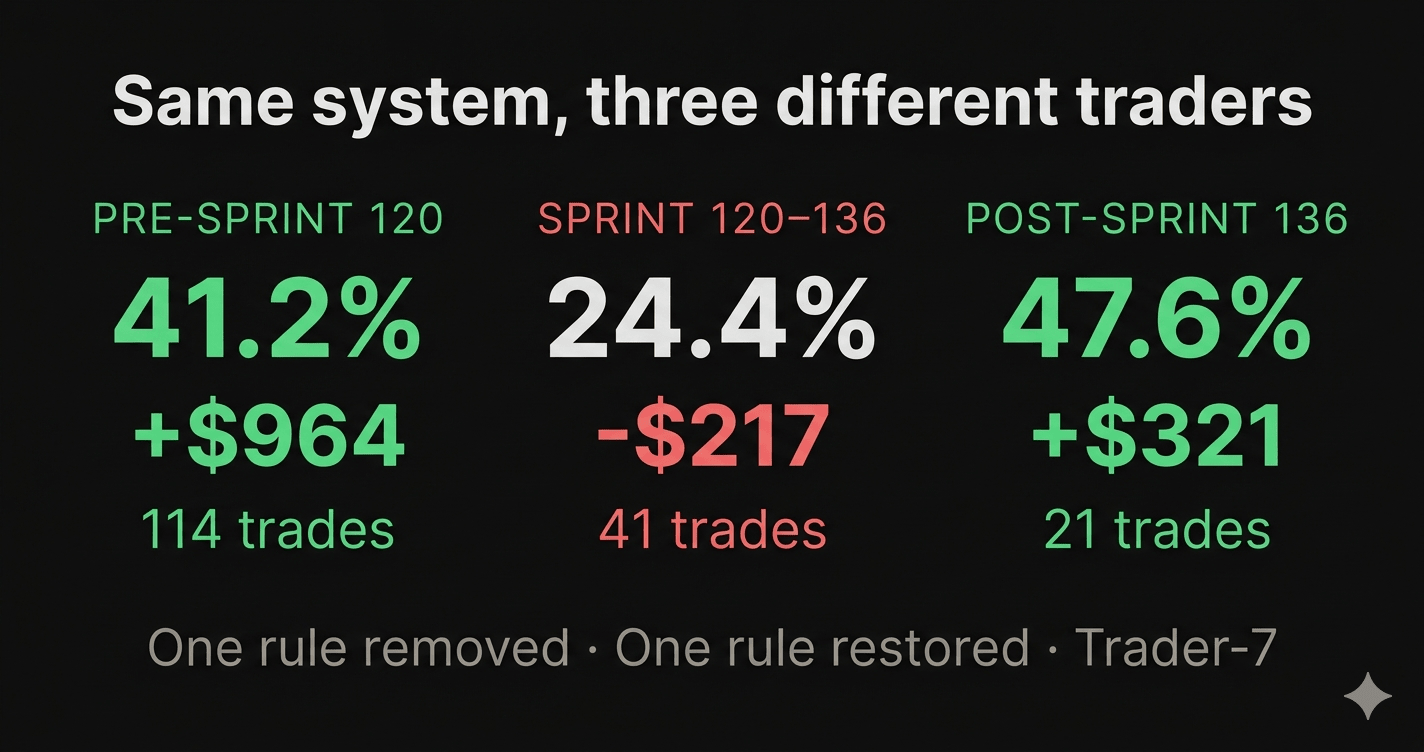
Three-period performance comparison: Pre-Sprint 120 at 41.2% win rate +$964, Sprint 120-136 at 24.4% win rate -$217, Post-Sprint 136 at 47.6% win rate +$321.
Build Log

Same system, three different traders

26 May 2026
4 min read

Same code, same market, three time periods. One made $964, one lost $217, one's up $321. The difference wasn't the algorithm.
Read More
Tiago Forte's book Building a Second Brain propped on a working desk, beside a podcast mic, with a laptop showing the author's prompts workspace and a large monitor showing his blog in the background.
Build Log

The Prodigal Second Brain

25 May 2026
7 min read

I built a second brain in 2020 and drowned it in my own output. PARA was the right answer to the wrong era. Here is the shape that fits this one.

Read More
Page 1 of 10Next →