Telling AI to act as your customers makes its answer worse: 52% of shoppers would buy, it said. Real sales: 33%.
Jamie Watters
Ex-banker, founder at 58, building with AI.
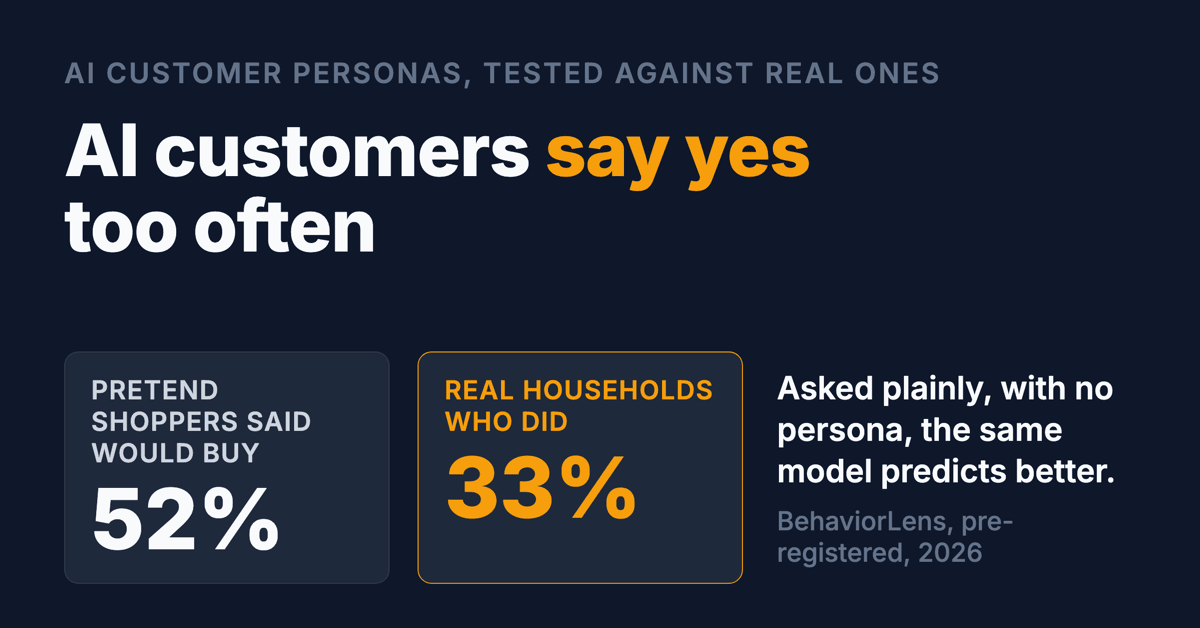
Ask an AI to pretend to be your customer and it will tend to like your idea more than your customers do. In a pre-registered test against a supermarket's real purchase records, a panel of AI shoppers predicted a 52% purchase rate across five product categories over the next 28 days. The real rate was 33% (BehaviorLens). Asked to predict coupon redemptions, the same panel said 32%. The tills said 14%.
I built a product on the opposite bet.
In January 2026 I wrote the plan for PlebTest: AI customer personas that interview you about your idea, push back, and hand down a verdict of kill, pivot or build. It was for founders who dread cold calls, which is me. The landing page promised "brutally honest feedback without picking up the phone". The plan said 1,000 paying founders and $250,000 a year by the end of 2026, with 60% of free trials converting to paid and break-even at three customers (the planning documents are in the public repo). I had checked none of it with a single real customer. A tool for validating ideas, itself never validated. The README says so now, at the top.
What I built
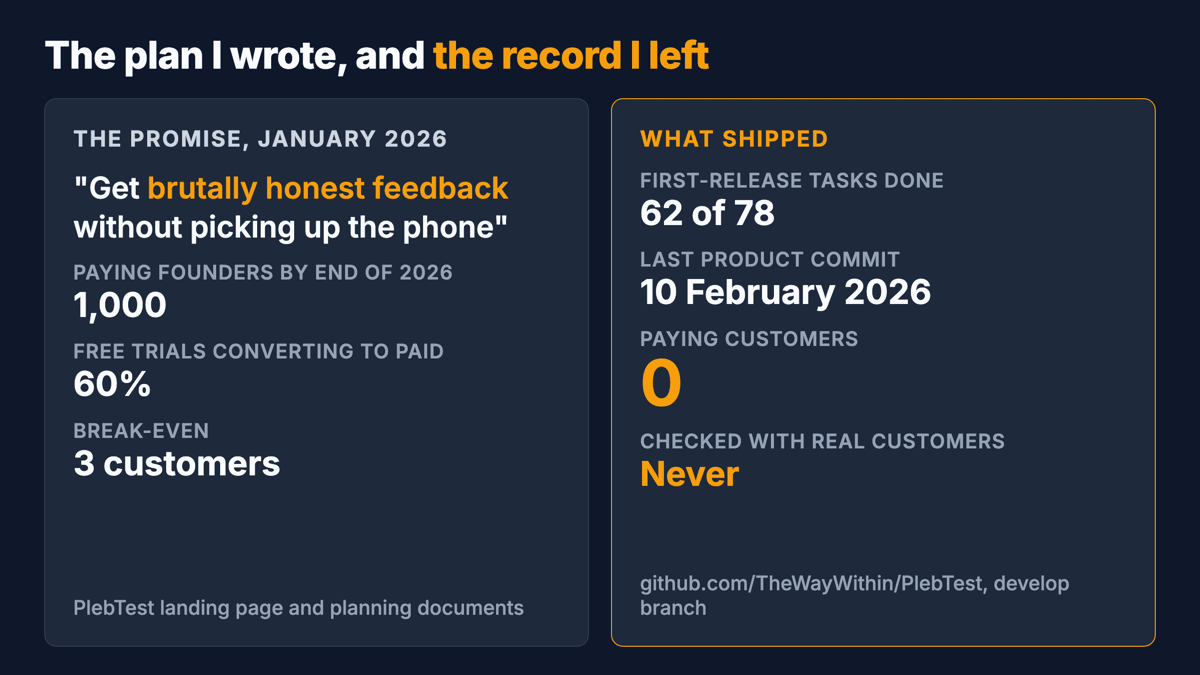
The plan on the left, the record on the right. Both are in the repo.
The engine worked. By 10 February the develop branch had 62 of the 78 tasks for the first release done: sign-in, Stripe billing with pro-rated upgrades, two interview modes, a one-line quick check, and a report that handed down the verdict (commit history). The part I was proudest of was the anti-sycophancy design. Every panel of personas was 40% high-sceptic, 40% medium, 20% low. The toughest preset, the Critic, had to find at least three objections before showing interest, alongside the Pragmatist and the Cheerleader (architecture notes). A scorecard counted objections in every session against a minimum of two, and a golden set of test ideas checked the engine wasn't going soft (project plan). The spec also said to rerun any reply with too few objections. I never built that part.
Every one of those is a dial. None of them is a reference point. I could make the fake customers harsher or kinder. I had no way of knowing which setting matched real customers, because real customers were the thing the product existed to avoid.
I announced the landing page on LinkedIn on 24 January. The task for launching the product itself, a marketing launch plan, stayed unticked. The last commit to the product was 10 February. I parked it in May, in July I retired the whole model of selling software like this on my own, and the README marks PlebTest killed in August.
What the studies say
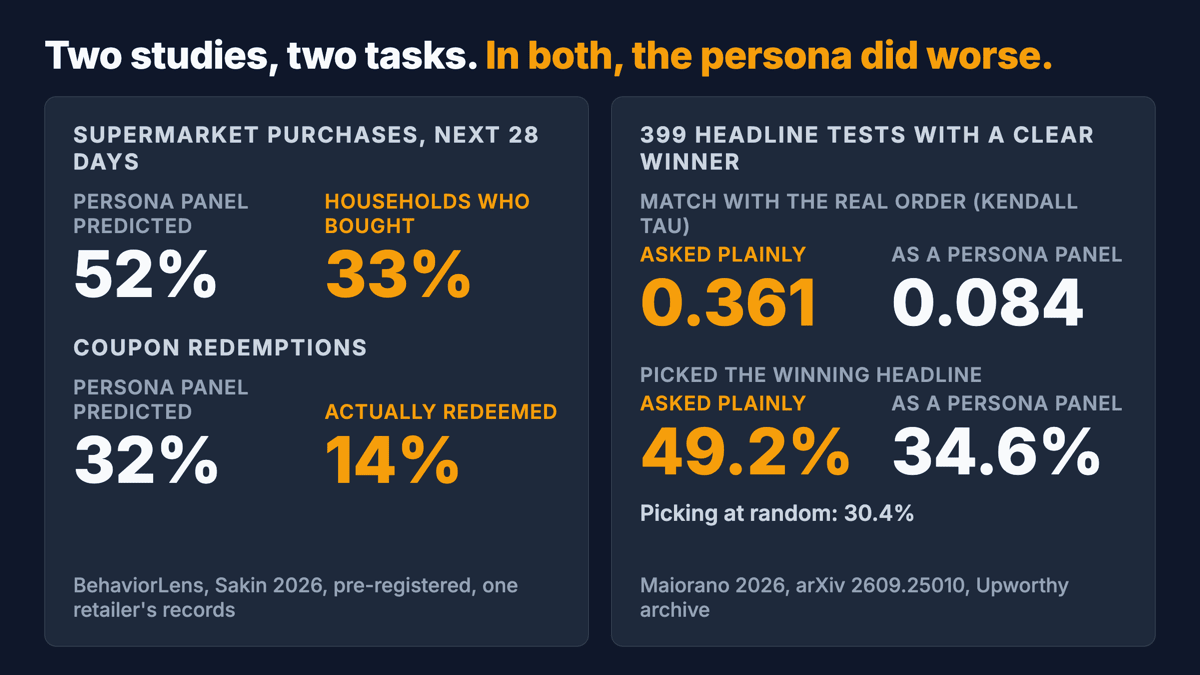
Two studies, two different tasks and models. In both, the persona was the weaker method.
Two pre-registered studies from this year put numbers on the thing I'd been tuning by feel.
The first, BehaviorLens (Meryem Sakin, 2026), gave language-model personas a household's shopping history and asked whether it would buy in each of five categories over the next 28 days. That ran across 1,456 household-periods, and every answer was checked against what the household bought. Persona panel: 52% predicted, 33% observed. Coupons: 32% predicted, 14% redeemed. The models were also asked to rank nine coupon campaigns by how many people would redeem them, scored on rank agreement, where 1 is a perfect match and 0 is no better than chance. A gradient-boosting model, the standard machine-learning tool for this, built on the same data, scored 0.55. A language model given the same structured data and no persona scored 0.13. The persona panel scored minus 0.10. The author's own caveats: nine campaigns is nine data points, the dataset is public so the models may have seen it in training, each question was asked once, and only one persona design was tested.
The second (Alexandre Maiorano, 2026) took the 399 of 1,695 headline A/B tests in the Upworthy archive that had a clear winner, where real readers on real traffic picked it by clicking. Asking the model which headline a typical reader would click, with no further persona, matched the real ranking at 0.361 and picked the winner 49.2% of the time. A panel of ten personas built from real audience demographics scored 0.084 and 34.6%. Picking at random gets 30.4% (arXiv 2609.25010). His explanation: asked plainly, the model draws on an accurate sense of what people in general do. Told to play a particular person, it adds bias and noise.
I'd built the persona layer as the feature. In both studies it was the part that made the answer worse.
Both of those panels were built from real data: each household's own shopping record, or published demographics of the real audience. The persona a founder writes from a guess about their customer has less to go on.
Why the sceptic dial could not fix it
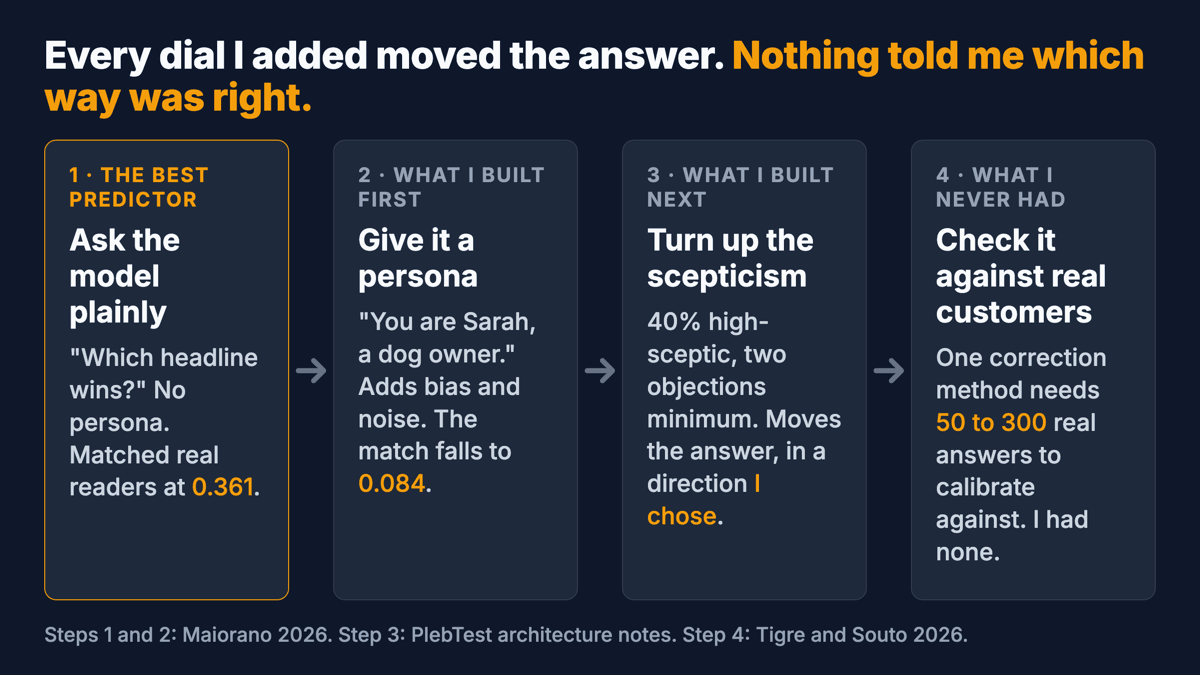
Each step after the first made the answer different. None made it checkable.
My instinct was that the trouble with AI customers is that they're too nice, so the fix is to make them meaner. The BehaviorLens result agrees the panel was too nice, so a meaner panel might well land closer. The trouble is knowing how much closer, or when it has gone past. A dial that adds objections moves the answer by an amount I chose, with nothing real to check it against.
BehaviorLens shows what a real reference point does. Calibrated on a held-back slice of the real purchase data, the persona panel's extra error over the no-persona model fell from 0.0550 to 0.0049 on its accuracy score, about nine tenths of the gap gone. The fix for a fake customer is real customers.
Tigre and Souto (2026) ask when you can trust a synthetic consumer panel as it is, when you can correct it, and when you should abandon it. Their correction method needs a sample of 50 to 300 real responses to calibrate against. And once you have that sample, their own figures show the real answers on their own are more precise than the corrected panel (arXiv 2609.13148). A founder who uses an AI panel to avoid talking to 50 people has exactly the data needed to calibrate it: none.
Simile, which sells simulated users for marketing and product research, raised $200 million at a $2 billion valuation on 30 July 2026 (TechCrunch). I don't think that contradicts the studies. A buyer with real customer data can, in principle, calibrate a panel against it. The product I built was for the one buyer who has nothing to calibrate with.
What a fake customer is still good for
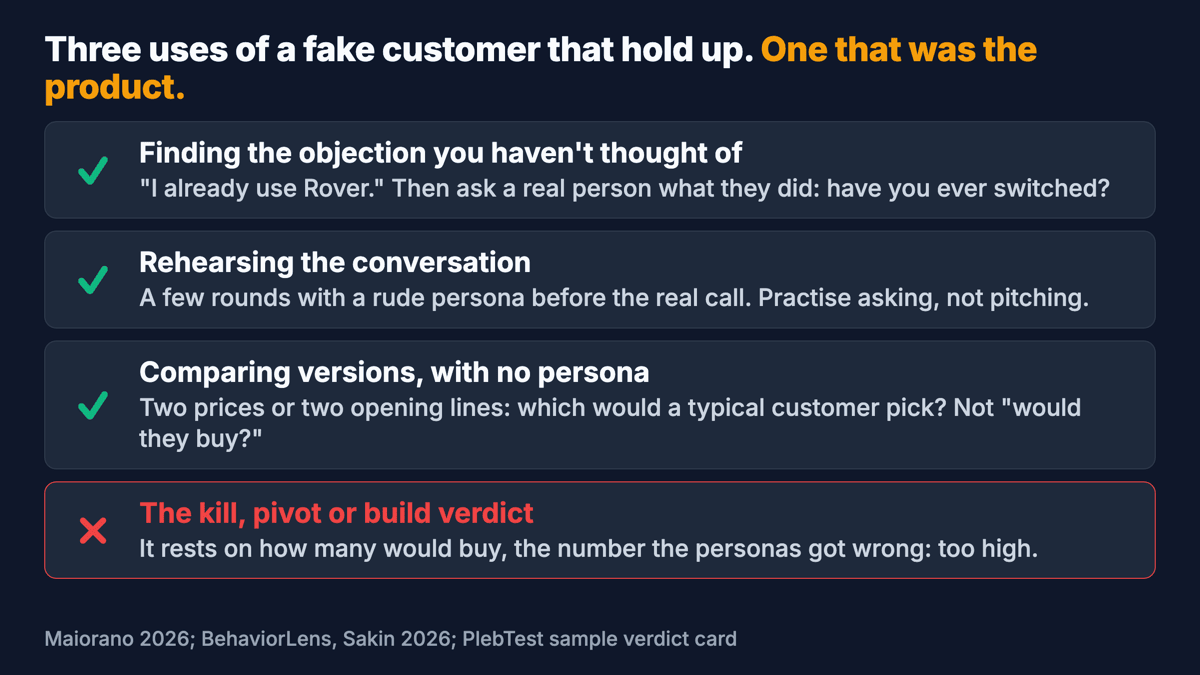
Keep the first three. The fourth was the product.
I'd use one again for three things, and never for the fourth.
- Finding the objection you haven't thought of. My own sample card had a persona called Sarah saying "I already use Rover. Unless you're half the price, I'm not switching." As a reminder that the question exists, that's free and instant. Whether real dog owners would say it is a separate question the persona can't answer. So turn it into a question for a real person about what they did: how did you find your dog walker, and have you ever switched?
- Rehearsing the conversation. If you're going to talk to real people and the prospect scares you, a few rounds with a rude persona takes the edge off. Practise asking what people did, not pitching. That's practice, not evidence.
- Comparing versions, with no persona. The headline study's win was a comparison: give the model two or more versions of the same thing and ask which a typical customer would pick. Two prices, two opening lines, two ways of describing the problem. Don't ask it whether people would buy at all. That's a level, and the level is what the personas got wrong.
The fourth is the verdict. Kill, pivot or build was the product's whole promise. None of the three studies tested a verdict like that, but every verdict rests on a guess about how many people would buy, and that guess is the number the personas got wrong, in the kind direction.
What replaces it is the step the product was built to skip: a few conversations with real people about what they did, not what they would do. PlebTest's own plan had a task for exactly that, a minimum real-world validation plan. It was never built.
The evidence is narrow. BehaviorLens tested purchase forecasting at one retailer. Maiorano tested headline ranking, and the gap was small on a second news dataset and vanished on Reddit titles. Tigre and Souto tested population estimates. None of them tested an interview about an unbuilt product. If someone publishes a pre-registered test where persona panels beat the plain question on real purchase data, I'll change my mind and say so here.
The repo is public under an MIT licence. The engine runs. The verdict screen still says kill, pivot or build in large type. The studies say to read everything on that screen except the verdict.
Sources
- Sakin, M. (2026). BehaviorLens: a pre-registered evaluation of LLM personas against held-out dunnhumby retail transactions. https://github.com/meryemsakin/BehaviorLens
- Maiorano, A. C. (2026). Do Synthetic Personas Predict Real Audience Response? A Sim-to-Real Study Where a No-Persona Baseline Beats Persona-Based Copy Simulation. arXiv:2609.25010. https://arxiv.org/abs/2609.25010
- Tigre, R. and Gobato Souto, H. (2026). When Can You Trust Your Synthetic Users? Diagnostics and Corrections for LLM Consumer Panels. arXiv:2609.13148. https://arxiv.org/abs/2609.13148
- TechCrunch, 30 July 2026. Synthetic-user startup Simile raises $200M at $2B valuation 5 months after $100M Series A. https://techcrunch.com/?p=3148353
- PlebTest repository, planning documents, architecture, project plan and commit history. https://github.com/TheWayWithin/PlebTest